


Key Takeaways
- Meta Muse Voice Transcribe 1.0 combines real-time speech-to-text, speaker diarization, endpoint detection and multilingual code-switching in a unified AI model.
- Muse Voice Transcribe uses streaming audio processing and Adaptive Delay to balance transcription accuracy with low latency for responsive voice AI applications.
- Key Muse Voice Transcribe use cases include AI voice agents, contact centers, meeting intelligence, live dictation, accessibility tools and multilingual transcription.
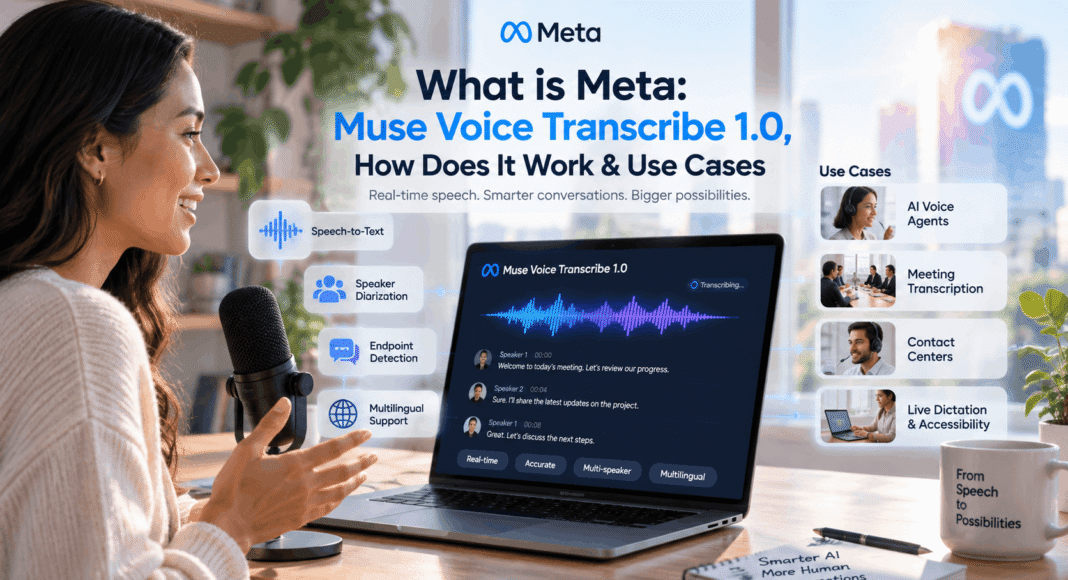
Meta Muse Voice Transcribe 1.0 processes real-time speech using a unified AI model for transcription, speaker diarization, endpoint detection, multilingual recognition, and code-switching. Designed for low-latency audio understanding, it supports practical applications such as AI voice agents, meeting transcription, contact centers, live dictation, accessibility tools, and enterprise voice workflows.
Meta Muse Voice Transcribe 1.0 is a real-time speech AI model designed to transform how applications understand spoken conversations. Developed by Meta Superintelligence Labs, the model goes beyond conventional speech-to-text by combining streaming automatic speech recognition, speaker diarization, conversational endpoint detection, multilingual processing, and code-switching within a unified audio perception system.
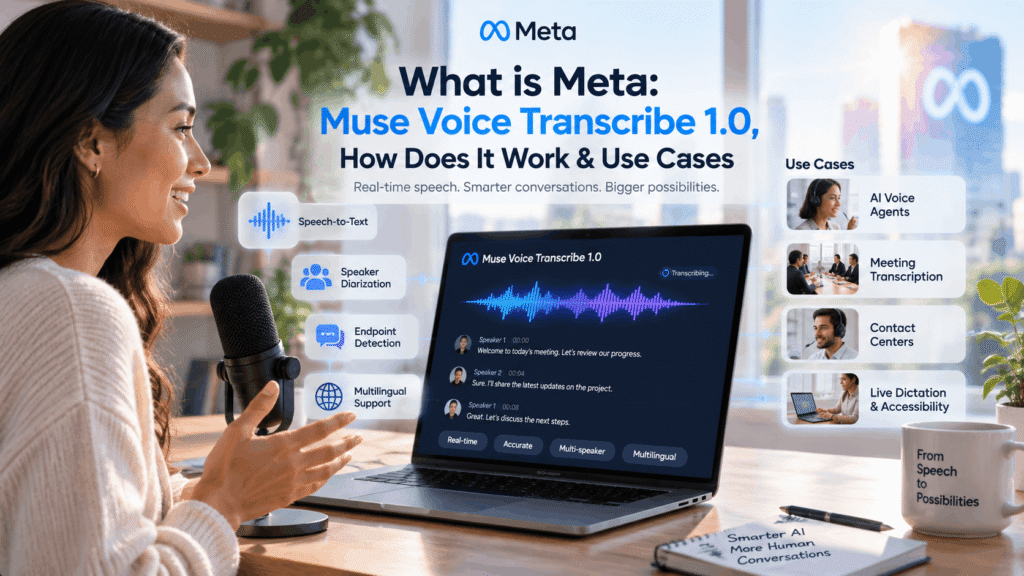
Instead of relying on separate tools to detect speech, transcribe words, identify speakers, and determine when someone has finished talking, Muse Voice Transcribe 1.0 handles these functions together. Its streaming architecture processes incoming audio continuously, while Adaptive Delay helps balance transcription accuracy and response speed by allowing the model to listen longer when additional context is needed.
This approach makes Meta Muse Voice Transcribe particularly relevant for AI voice agents, contact centers, meeting transcription, live dictation, accessibility applications, multilingual customer support, and voice-driven developer tools. Its ability to distinguish multiple speakers and process conversations that switch between languages also expands its potential for international and enterprise applications.
Muse Voice Transcribe 1.0 is especially notable for combining low-latency speech recognition with competitive API pricing. However, organizations must also consider limitations such as hosted API dependency, the absence of self-hosted open weights, and limited word-level metadata.
This guide explores what Meta Muse Voice Transcribe 1.0 is, how its real-time speech recognition architecture works, its key features, multilingual capabilities, performance benchmarks, API specifications, pricing, limitations, and the most practical use cases for businesses and developers in the growing voice AI ecosystem.
Before we venture further into this article, we would like to share who we are and what we do.
About 9cv9
9cv9 is a business tech startup based in Singapore and Asia, with a strong presence all over the world.
With over ten years of startup and business experience, and being highly involved in connecting with thousands of companies and startups, the 9cv9 team has listed some of the top and best companies/tools in this review.
If you like to get your company listed in our top B2B software reviews, check out our world-class 9cv9 Media and PR service and pricing plans here.
What is Meta: Muse Voice Transcribe 1.0, How Does It Work & Use Cases
- What is Meta Muse Voice Transcribe 1.0?
- Benchmark Evaluation and Performance Metrics
- API Specifications, Technical Parameters, and Constraints
- Multilingual Capabilities and Code-Switching Performance
- Commercial Pricing Model and Cost Analysis
- Application Deployment Patterns and Real-World Use Cases
- Strategic Assessment and Future Outlook
1. What is Meta Muse Voice Transcribe 1.0?
Meta Muse Voice Transcribe 1.0 is a real-time audio perception and speech-to-text model developed by Meta Superintelligence Labs and released on September 1, 2026. Rather than functioning as a conventional transcription engine that simply converts completed audio recordings into text, the model is designed to understand continuously arriving speech while simultaneously identifying speakers and detecting conversational boundaries.
The model combines three important speech-processing capabilities within one streaming system: automatic speech recognition, speaker diarization, and speech endpointing. Meta says it can distinguish more than 20 speakers, process audio sessions exceeding one hour, handle multilingual speech and code-switching, and improve recognition through language, keyword, and contextual biasing.
This unified architecture makes Muse Voice Transcribe particularly relevant for voice agents, meeting transcription, call intelligence, live captions, dictation, customer support systems, and other applications where speech must be interpreted while a conversation is still taking place.
| Attribute | Meta Muse Voice Transcribe 1.0 |
|---|---|
| Developer | Meta Superintelligence Labs |
| Release Date | September 1, 2026 |
| Model Identifier | muse-voice-transcribe-1.0 |
| Primary Function | Real-time speech and audio perception |
| Input | Streaming or recorded audio |
| Output | Text and conversational structure |
| Core Capabilities | ASR, diarization and endpointing |
| Audio Processing Interval | 80 milliseconds |
| Processing Frequency | 12.5 audio chunks per second |
| Language Training Coverage | More than 70 languages |
| Extensively Verified Languages | 25 at initial release |
| Speaker Support | More than 20 speakers |
| Long Audio Support | More than one hour |
| Code-Switching | Supported |
| Context Biasing | Supported |
| Availability | Meta Model API, Meta AI for Mac and Muse Code |
How Meta Muse Voice Transcribe 1.0 Differs From Traditional Speech Recognition
Traditional speech-processing infrastructure often consists of several specialized components connected together. One system may detect whether somebody is speaking, another performs speech recognition, another identifies speakers, and another determines when an utterance has ended.
That approach can work effectively, but coordinating multiple models and services can increase system complexity and introduce additional processing stages.
Muse Voice Transcribe takes a more unified approach. Streaming ASR, diarization and endpointing are trained within the same real-time model, allowing conversational information to become part of the generated sequence rather than requiring all speaker information to be reconstructed through separate post-processing.
| Speech Processing Requirement | Traditional Architecture | Muse Voice Transcribe 1.0 |
|---|---|---|
| Speech Recognition | Separate ASR engine | Integrated streaming ASR |
| Speaker Identification | Often separate diarization stage | Native diarization |
| Speech Boundaries | VAD or endpointing component | Integrated endpointing |
| Streaming Processing | Often buffer dependent | Continuous 80 ms processing |
| Speaker Changes | Reconstructed separately | Represented through structural tokens |
| Multilingual Speech | May require language routing | Multilingual model |
| Code-Switching | Can require additional handling | Native capability |
| Context Optimization | Application-dependent | Language, keyword and context biasing |
| Long Conversations | Architecture dependent | More than one hour supported |
| System Complexity | Multiple coordinated components | Unified perception model |
How Does Meta Muse Voice Transcribe 1.0 Work?
Muse Voice Transcribe uses an autoregressive multimodal architecture that continuously processes incoming audio.
Instead of waiting for a large section of speech before generating a transcript, incoming audio is divided into 80-millisecond chunks. This corresponds to 12.5 chunks every second.
Each audio chunk is represented internally as a soft token. The autoregressive model then evaluates the accumulated audio context and determines what should happen next.
Conceptually, the process operates as a continuous listen-or-write cycle.
| Processing Stage | What Happens |
|---|---|
| Audio Capture | Speech enters the transcription system |
| Audio Segmentation | Audio is processed in 80-millisecond increments |
| Internal Representation | Each chunk becomes a soft audio token |
| Context Evaluation | The model evaluates accumulated acoustic and linguistic context |
| Decision | The model decides whether to continue listening or generate output |
| Text Generation | Recognized speech is emitted as transcript tokens |
| Structural Interpretation | Speaker changes and speech boundaries can also be generated |
| Stream Completion | Remaining buffered transcription is produced when audio ends |
The Listen-or-Write Architecture
One of the most important architectural characteristics of Muse Voice Transcribe is that the model does not have to produce text immediately after every audio chunk.
After processing incoming speech, it can effectively choose between generating transcript information or requesting additional audio context.
A special next-audio control token tells the runtime that more audio should be supplied. When the audio stream has finished, an end-of-audio signal allows the model to complete any transcription that remains buffered.
This creates a dynamic streaming system rather than one governed entirely by a fixed transcription delay.
| Model Decision | Purpose | Typical Situation |
|---|---|---|
| Generate Text | Commit recognized speech to the transcript | Speech is sufficiently clear |
| Continue Listening | Obtain additional acoustic context | Word or phrase remains ambiguous |
| Generate Speaker Structure | Identify conversational speaker information | Speaker change is detected |
| Generate Endpoint | Indicate completion of an utterance | Speaker finishes talking |
| Complete Remaining Text | Finalize buffered transcription | Audio stream terminates |
Adaptive Delay and the Speed-Accuracy Trade-Off
Real-time transcription systems face an important engineering problem: producing text too quickly can increase recognition mistakes, while waiting for additional audio improves contextual understanding but increases latency.
Meta addresses this problem through Adaptive Delay.
Instead of forcing every word to use the same waiting period, Muse Voice Transcribe can dynamically determine whether additional audio context is worthwhile. Predictable speech can therefore be emitted rapidly, while uncertain or context-dependent speech can receive additional listening time before the model commits to a transcription.
Meta reports that Adaptive Delay is trained using reinforcement learning, with optimization considering both transcription accuracy and latency. The objective is to find a better operating point between Word Error Rate and time to final transcription.
| Speech Situation | Model Behaviour | Intended Benefit |
|---|---|---|
| Highly predictable phrase | Transcribe rapidly | Lower perceived latency |
| Clear common vocabulary | Commit with limited delay | Fast real-time output |
| Ambiguous pronunciation | Listen for additional context | Reduce transcription errors |
| Specialized terminology | Use additional context where useful | Improve recognition accuracy |
| Context-dependent wording | Delay commitment selectively | Better semantic interpretation |
| Completed speech | Finalize transcription | Responsive conversation handling |
Native Speaker Diarization
Speaker diarization answers an important question that basic speech-to-text systems cannot: who said what?
Muse Voice Transcribe integrates speaker diarization directly into its generation process. Structural tokens identify potential speaker changes and assign speaker labels within the conversational sequence.
Meta reports support for conversations containing more than 20 speakers without requiring a separate offline diarization stage.
This capability makes the model particularly useful for meetings, interviews, focus groups, conference discussions and multi-party customer service environments.
| Scenario | Value of Native Diarization |
|---|---|
| Business Meetings | Separates comments from different participants |
| Interviews | Distinguishes interviewer and interviewee |
| Contact Centers | Separates agents from customers |
| Focus Groups | Organizes comments across many participants |
| Panel Discussions | Creates speaker-aware transcripts |
| Research Sessions | Makes multi-speaker recordings easier to analyze |
Real-Time Speech Endpointing
Another major capability is endpointing: determining when somebody has started or finished speaking.
Traditional voice systems frequently depend on silence thresholds or dedicated voice activity detection logic. This can create awkward delays when voice assistants wait too long before responding or incorrectly interrupt users who pause briefly.
Muse Voice Transcribe incorporates speech-onset and speech-endpoint information directly into its output structure.
For conversational AI, endpointing is particularly valuable because another system can begin generating a response as soon as the user’s turn is considered complete.
| Endpointing Event | Meaning | Application Benefit |
|---|---|---|
| Speech Onset | User begins speaking | Starts active speech processing |
| Continued Speech | User remains within the same turn | Prevents premature response |
| Short Pause | Context determines whether turn continues | More natural interaction |
| Speech Endpoint | User completes an utterance | Allows downstream AI to respond |
| New Speaker | Conversational participant changes | Supports multi-user interaction |
Multilingual Transcription and Code-Switching
Muse Voice Transcribe was trained across more than 70 languages, while Meta identified 25 languages as extensively verified at launch.
An especially important capability is native code-switching. Speakers can change languages during a sentence or conversation without requiring the application to manually route the audio between separate language-specific transcription models.
This makes the technology particularly relevant to multilingual workplaces, international customer service, global meetings and regions where conversations frequently combine multiple languages.
Context, Keyword and Language Biasing
Generic speech recognition models can struggle with company names, technical terminology, product names, industry abbreviations and other specialized vocabulary.
Muse Voice Transcribe supports language, keyword and context biasing to help applications provide information that can improve recognition.
A business application could therefore supply relevant terminology before or during transcription, potentially improving the recognition of vocabulary that is uncommon in general speech.
| Biasing Method | Primary Purpose | Example Application |
|---|---|---|
| Language Biasing | Prioritize expected language information | Regional applications |
| Keyword Biasing | Improve recognition of important terms | Product and company names |
| Context Biasing | Supply relevant situational information | Meetings and specialized workflows |
| Domain Vocabulary | Improve recognition of specialized terms | Technical and enterprise applications |
Performance and Real-Time Transcription
At its September 1, 2026 launch, Meta reported that Muse Voice Transcribe ranked first on Artificial Analysis for streaming speech-to-text and on public diarization benchmarks.
Meta also states that Adaptive Delay reaches the Pareto front of the speed-versus-accuracy trade-off when measured using time to final transcription.
These benchmark claims are important, but organizations evaluating the model should still conduct their own testing. Real-world transcription performance can vary considerably according to microphone quality, accents, background noise, overlapping speech, specialized vocabulary and deployment conditions.
Meta Muse Voice Transcribe 1.0 Use Cases
The combination of streaming transcription, speaker attribution, multilingual processing and endpoint detection gives Muse Voice Transcribe applications beyond conventional audio transcription.
| Use Case | How Muse Voice Transcribe Can Be Applied |
|---|---|
| AI Voice Agents | Converts user speech into structured input for conversational AI |
| Customer Support | Transcribes conversations while distinguishing agents and customers |
| Meeting Intelligence | Creates live speaker-aware meeting transcripts |
| Live Captions | Generates text while speech is occurring |
| Voice Dictation | Converts spoken content into text in productivity applications |
| Call Analytics | Creates structured transcripts for downstream conversation analysis |
| Interviews | Separates participants and creates searchable transcripts |
| Focus Groups | Handles conversations involving numerous speakers |
| Multilingual Support | Processes conversations containing multiple languages |
| Developer Tools | Enables voice-driven coding and development workflows |
| Contact Centers | Supports real-time transcription for agent-assistance systems |
| Accessibility | Provides real-time text representations of spoken conversations |
Muse Voice Transcribe for AI Voice Agents
AI voice agents represent one of the strongest potential applications.
A voice agent needs more than accurate transcription. It must determine when the user starts speaking, understand the words being spoken, recognize when the user has finished and quickly send the completed utterance to the reasoning or response model.
Because Muse Voice Transcribe combines transcription and endpointing, developers can potentially simplify this portion of the voice-agent pipeline.
The broader architecture could operate as follows:
User Speech → Muse Voice Transcribe → Structured Transcript → AI Reasoning Model → Response Generation → Speech Synthesis
Muse Voice Transcribe itself is primarily concerned with audio perception and transcription rather than generating the spoken response. A complete conversational voice system therefore still requires downstream intelligence and, when spoken output is required, text-to-speech technology.
Muse Voice Transcribe for Meetings and Enterprise Intelligence
Enterprise meeting intelligence is another strong use case because the model combines long-form audio processing with multi-speaker diarization.
Instead of producing a large undifferentiated transcript, applications can preserve information about different speakers and conversational turns. Downstream AI systems could subsequently use that structured transcript to generate summaries, extract decisions, identify action items or populate business systems.
This creates potential applications across sales intelligence, recruitment interviews, research sessions, customer success, corporate meetings and professional services.
Advantages of Meta Muse Voice Transcribe 1.0
The model’s primary advantage is not simply speech-to-text accuracy. Its architecture combines several capabilities that previously might have required independent components.
| Advantage | Business or Technical Significance |
|---|---|
| Unified Architecture | Reduces dependence on separate speech-processing components |
| Real-Time Streaming | Supports interactive applications |
| Adaptive Delay | Dynamically balances speed and recognition accuracy |
| Native Diarization | Enables speaker-aware applications |
| Native Endpointing | Improves conversational turn handling |
| Multilingual Processing | Supports globally distributed applications |
| Code-Switching | Handles multilingual conversations more naturally |
| Long Audio Support | Suitable for meetings and extended conversations |
| Context Biasing | Improves handling of domain-specific vocabulary |
| More Than 20 Speakers | Supports complex group conversations |
Limitations and Implementation Considerations
Muse Voice Transcribe should not be treated as a complete voice AI platform by itself. Its primary role is audio perception and speech transcription.
Applications may still require a large language model for reasoning, a text-to-speech model for spoken responses, application logic, data storage, privacy controls and business-system integrations.
Organizations should also evaluate transcription quality using their own audio conditions rather than relying exclusively on benchmark results.
| Requirement | Muse Voice Transcribe Role |
|---|---|
| Speech-to-Text | Core capability |
| Speaker Identification | Core capability |
| Turn Endpointing | Core capability |
| Multilingual Recognition | Core capability |
| Code-Switching | Core capability |
| AI Reasoning | Requires another model or system |
| Text-to-Speech | Requires separate technology |
| Business Workflow Automation | Requires application integration |
| Transcript Analytics | Usually handled downstream |
| Enterprise Data Governance | Must be implemented by the application |
Meta Muse Voice Transcribe 1.0 in the Emerging Voice AI Stack
Muse Voice Transcribe represents a broader shift in voice AI from collections of narrowly separated speech components toward unified real-time perception models.
Its architecture allows transcription, speaker attribution and conversational boundaries to be generated as related parts of the same streaming process. Adaptive Delay further changes the conventional streaming model by allowing transcription latency to vary according to the difficulty of the speech being interpreted.
For developers and enterprises, the practical significance is potentially simpler voice infrastructure combined with richer conversational information. Rather than receiving only words from an ASR engine, applications can receive a structured representation of an evolving conversation.
As real-time voice interfaces become increasingly important across AI assistants, contact centers, productivity software, meeting intelligence and enterprise automation, Meta Muse Voice Transcribe 1.0 provides an important example of how speech recognition is evolving into broader real-time audio perception.
2. Benchmark Evaluation and Performance Metrics
Meta Muse Voice Transcribe 1.0 entered the real-time speech-to-text market with strong benchmark results across transcription accuracy, latency, speaker diarization and operating cost. However, the results need to be interpreted carefully because some figures come from independent benchmarking, while others originate from Meta’s launch evaluations or third-party testing under different audio conditions.
At launch on September 1, 2026, Meta stated that Muse Voice Transcribe ranked first on Artificial Analysis for streaming speech-to-text and first on the public diarization benchmarks used in Meta’s evaluation. Artificial Analysis independently reported approximately 3.1% final Word Error Rate and roughly 0.16 seconds of post-speech latency for the model.
Artificial Analysis Streaming Speech-to-Text Benchmark
Artificial Analysis provides one of the most useful independent comparisons because competing real-time transcription systems are evaluated using a common methodology.
In the September 1, 2026 snapshot, Muse Voice Transcribe recorded a final streaming Word Error Rate of 3.0623%. Its first-partial WER was 3.5747%.
Lower WER indicates greater transcription accuracy because the metric measures substitutions, deletions and insertions relative to the reference transcript.
| Artificial Analysis Metric | Muse Voice Transcribe 1.0 | Interpretation |
|---|---|---|
| Final Streaming WER | 3.0623% | Approximately 3.1 word errors per 100 reference words |
| First-Partial WER | 3.5747% | Accuracy of the initial streaming transcript |
| Time to Final Transcript | 0.163 seconds | Time after detected speech endpoint |
| First-Partial Latency | 0.127 seconds | Time to first post-endpoint partial result |
| Normalized Cost | $3.00 per 1,000 minutes | Approximately $0.18 per audio hour |
The same Artificial Analysis snapshot placed Muse ahead of Cartesia Ink-2, ElevenLabs Scribe v2 Realtime, Qwen3 ASR Flash Realtime, OpenAI GPT Live Transcribe, Grok Speech to Text Streaming, Google Gemini 3.5 Transcribe Live and AssemblyAI U3.5 Realtime Pro on final WER.
Muse Voice Transcribe Accuracy Compared With Competitors
The September 1 benchmark provides a useful picture of the competitive streaming ASR landscape.
| Streaming Speech-to-Text Model | Final WER | First-Partial WER |
|---|---|---|
| Meta Muse Voice Transcribe 1.0 | 3.0623% | 3.5747% |
| Cartesia Ink-2, Semantic Endpoint | 3.3612% | 4.8878% |
| ElevenLabs Scribe v2 Realtime | 3.5946% | 3.5928% |
| Qwen3 ASR Flash Realtime | 3.7339% | 19.9445% |
| OpenAI GPT Live Transcribe | 3.9177% | 6.3477% |
| Grok Speech to Text Streaming | 3.9329% | 18.2751% |
| Google Gemini 3.5 Transcribe Live | 3.9983% | 5.7743% |
| AssemblyAI U3.5 Realtime Pro | 4.0180% | 4.0412% |
These figures show why Muse Voice Transcribe attracted attention at launch. Its advantage was not merely low latency or low WER independently; it delivered a particularly competitive combination of the two.
Real-Time Latency Performance
Latency is particularly important for voice agents, live captioning, customer support assistants and conversational AI.
Artificial Analysis measures the interval between the benchmark-detected end of speech and delivery of the transcript. Muse Voice Transcribe produced its first post-endpoint partial transcript in approximately 127 milliseconds and its finalized transcript in approximately 163 milliseconds.
| Latency Stage | Reported Time | Practical Meaning |
|---|---|---|
| Speech Endpoint | 0 ms reference | Benchmark detects completion of speech |
| First Partial Transcript | 127 ms | Initial post-endpoint transcript becomes available |
| Final Transcript | 163 ms | Transcript reaches final state |
| Partial-to-Final Gap | 36 ms | Additional stabilization after first result |
For conversational applications, a difference measured in hundreds of milliseconds can influence how responsive an AI assistant feels. Muse therefore targets a particularly important part of the voice AI stack: generating accurate text quickly enough that downstream reasoning and speech generation can begin without introducing unnecessary conversational pauses.
The Speed-Accuracy Pareto Frontier
Streaming ASR systems traditionally face a trade-off between accuracy and latency. Waiting for additional audio provides greater linguistic context and can improve recognition, but it also makes the transcription system slower.
Muse Voice Transcribe uses its Adaptive Delay mechanism to dynamically manage this trade-off.
Artificial Analysis’ launch snapshot placed Muse at a new Pareto point, meaning competing configurations did not simultaneously provide both lower WER and lower latency at that operating position. ElevenLabs Scribe v2 Realtime was slightly faster at finalization, for example, but recorded a higher WER.
| System | Final WER | Final Latency | Relative Position |
|---|---|---|---|
| Meta Muse Voice Transcribe | 3.06% | 0.163 s | Strongest accuracy-latency balance |
| ElevenLabs Scribe v2 Realtime | 3.59% | 0.141 s | Slightly faster, higher WER |
| Cartesia Ink-2 Semantic Endpoint | 3.36% | 0.431 s | Higher WER and higher latency |
| AssemblyAI U3.5 Realtime Pro | 4.02% | 0.191 s | Higher WER and latency |
| Google Gemini 3.5 Transcribe Live | 4.00% | 0.395 s | Higher WER and latency |
| OpenAI GPT Live Transcribe | 3.92% | 0.812 s | Significantly higher measured latency |
These measurements represent a benchmark snapshot rather than permanent performance rankings. Models, configurations and provider infrastructure can change over time.
Speaker Diarization Performance
Muse Voice Transcribe also distinguishes itself through integrated real-time speaker diarization.
Meta reported an average Diarization Error Rate of 17.5% across AMI-IHM, AMI-SDM and VoxConverse. The other systems shown in the launch comparison ranged from 21.1% to 28.6%.
| Diarization System | Processing Mode | Average DER |
|---|---|---|
| Meta Muse Voice Transcribe | Streaming | 17.5% |
| AssemblyAI U3.5 Pro | Offline | 21.1% |
| ElevenLabs Scribe v2 | Offline | 24.6% |
| Deepgram Nova 3 | Offline | 25.4% |
| AssemblyAI U3.5 Pro | Streaming | 27.6% |
| Deepgram Nova 3 | Streaming | 28.6% |
Lower DER is better.
The result is notable because offline diarization systems can analyze an entire recording before assigning speakers, whereas streaming systems must make attribution decisions while the conversation is unfolding. Meta’s architecture performs speaker attribution as part of the real-time transcription process.
Understanding the 17.5% DER Result
A 17.5% DER should not be interpreted as meaning exactly 17.5% of words are attributed to the wrong speaker. DER measures the proportion of reference speaker time affected by diarization errors, including missed speech, false-alarm speech and speaker confusion.
Consequently, describing the result as “one incorrect speaker label every six minutes” would be misleading.
| Metric | What It Measures |
|---|---|
| WER | Incorrect, missing or inserted transcript words |
| DER | Errors in determining who spoke and when |
| Latency | Time required to return transcription results |
| Speaker Capacity | Number of speakers the system can represent |
| Context Length | Duration of audio the model can process |
This distinction matters when evaluating meeting transcription and contact-center applications because transcription accuracy and speaker-attribution accuracy measure fundamentally different problems.
Third-Party Real-World Testing
Third-party testing also demonstrates why controlled benchmark results should not be treated as universal accuracy guarantees.
Kingy.ai reported testing Muse Voice Transcribe against a local Whisper large-v3-turbo Q5_0 configuration across approximately 30 minutes of audio. In its aggregated English portion, Muse reportedly achieved 11.93% WER compared with 15.34% for Whisper.
That represents an absolute reduction of 3.41 percentage points and an approximately 22.2% relative reduction in WER under that particular test setup.
| Kingy.ai Evaluation | Muse Voice Transcribe | Whisper large-v3-turbo |
|---|---|---|
| English Aggregate WER | 11.93% | 15.34% |
| Absolute Difference | 3.41 percentage points better | Baseline |
| Relative WER Reduction | Approximately 22.2% | Baseline |
| Hindi-English Mixed Test | 54.21% | 30.84% |
The much higher error rates compared with Artificial Analysis demonstrate how strongly ASR performance depends on dataset composition, accents, recording conditions, domain vocabulary, normalization rules and scoring methodology.
Multilingual and Code-Switching Challenges
Muse Voice Transcribe supports multilingual speech and code-switching, but multilingual capability should not be confused with identical benchmark accuracy across every supported language.
The Kingy.ai Hindi-English stress test produced substantially poorer conventional WER-style results for Muse than its English evaluation. One reported issue involved how English technical terminology embedded within another language was rendered.
This illustrates a broader limitation of conventional WER evaluation: two transcripts can communicate similar semantic information while receiving significantly different scores because their written representation differs.
For enterprises, multilingual testing should therefore include both conventional WER and human evaluation of semantic correctness, terminology handling, script consistency and code-switching behavior.
Cost and Performance Comparison
Pricing strengthens Muse Voice Transcribe’s competitive position. Artificial Analysis normalized its launch pricing to $3 per 1,000 audio minutes, equivalent to approximately $0.18 per hour.
| Streaming ASR System | Final WER | Final Latency | Normalized Cost per 1,000 Minutes |
|---|---|---|---|
| Meta Muse Voice Transcribe 1.0 | 3.06% | 0.163 s | $3.00 |
| Cartesia Ink-2, Semantic Endpoint | 3.36% | 0.431 s | $4.00 |
| ElevenLabs Scribe v2 Realtime | 3.59% | 0.141 s | $6.50 |
| Qwen3 ASR Flash Realtime | 3.73% | 0.476 s | $5.40 |
| OpenAI GPT Live Transcribe | 3.92% | 0.812 s | $17.00 |
| Grok Speech to Text Streaming | 3.93% | 0.373 s | $3.33 |
| Google Gemini 3.5 Transcribe Live | 4.00% | 0.395 s | $9.00 |
| AssemblyAI U3.5 Realtime Pro | 4.02% | 0.191 s | $7.50 |
These are normalized Artificial Analysis estimates from the September 1, 2026 snapshot rather than guaranteed long-term vendor pricing. Enterprise discounts and pricing changes can produce different effective costs.
What the Benchmarks Mean for Enterprises
Muse Voice Transcribe 1.0’s launch results suggest that Meta is competing aggressively across three dimensions simultaneously: accuracy, latency and price.
| Enterprise Requirement | Benchmark Evidence | Potential Business Impact |
|---|---|---|
| Accurate Live Transcription | 3.06% AA final WER | Cleaner real-time transcripts |
| Responsive Voice Agents | 163 ms final latency | Reduced conversational delay |
| Fast Partial Results | 127 ms partial latency | Earlier downstream processing |
| Multi-Speaker Recognition | 17.5% average DER | Better meeting and call attribution |
| Low Processing Cost | Approximately $0.18/hour | Lower high-volume transcription costs |
| Multilingual Operations | 70+ training languages | Broader international deployment potential |
| Code-Switching | Native support | Better handling of multilingual conversations |
The strongest conclusion is therefore not that Muse Voice Transcribe will achieve 3.06% WER in every deployment. Rather, its September 2026 benchmark results show an unusually strong combination of streaming accuracy, response speed, integrated diarization and low API cost.
Organizations considering the model for voice agents, meeting intelligence, contact centers, live captions or enterprise transcription should benchmark it against their own recordings. Background noise, overlapping speakers, specialized terminology, accents, microphones and multilingual speech can produce results substantially different from standardized English benchmarks.
3. API Specifications, Technical Parameters, and Constraints
Meta Muse Voice Transcribe 1.0 is available as a hosted speech-to-text service through the Meta Model API under the model identifier muse-voice-transcribe-1.0. It supports both real-time streaming transcription and transcription of previously recorded audio.
Meta has not announced downloadable Muse Voice Transcribe weights for organizations to deploy on their own infrastructure. Consequently, production integrations currently center on Meta’s hosted API or third-party services that expose access to the model. Meta’s official launch announcement confirms availability through the Meta Model API, Meta AI for Mac and Muse Code.
For developers, the two principal integration patterns are a persistent WebSocket connection for live audio and an HTTP transcription request for completed recordings.
| Integration Method | Primary Purpose | Audio Delivery | Typical Application |
|---|---|---|---|
| WebSocket Streaming | Real-time transcription | Continuous PCM audio | Voice agents and live captions |
| HTTP File Transcription | Existing recordings | Complete WAV recording | Uploaded calls and recordings |
| Meta AI Integration | End-user dictation | Application-managed | Desktop voice input |
| Muse Code Integration | Developer voice workflows | Application-managed | Voice-assisted development |
Real-Time WebSocket API
For applications requiring immediate transcription, Muse Voice Transcribe provides a persistent WebSocket interface.
The WebSocket architecture allows an application to establish a session, configure the transcription behavior and continuously transmit audio while receiving interim and final transcription events.
Public integrations identify the real-time service as Meta’s ASR realtime endpoint and use muse-voice-transcribe-1.0 as the default model. LiveKit’s implementation, for example, sends mono PCM16 audio at 24 kHz and receives cumulative interim transcripts with server-side endpointing.
| Streaming API Characteristic | Specification |
|---|---|
| Model | muse-voice-transcribe-1.0 |
| Transport | Secure WebSocket |
| Preferred Sample Rate | 24 kHz |
| Alternative Sample Rate | 16 kHz |
| Channels | Mono |
| Sample Format | Signed 16-bit PCM |
| Streaming Output | Interim and final transcripts |
| Endpoint Detection | Supported |
| Speaker Diarization | Supported |
| Keyword Biasing | Supported |
| Language Biasing | Supported |
| Maximum Session Duration | 60 minutes |
Audio Input Requirements
Muse Voice Transcribe uses relatively strict audio requirements compared with APIs that automatically accept many compressed media formats.
For real-time streaming, 24 kHz is the model’s native sample rate. A 16 kHz input is also supported. Integrations commonly resample incompatible input before sending it to Meta.
For file transcription, OpenRouter’s current model specification states that recordings must use mono, 16-bit PCM WAV at either 16 kHz or 24 kHz. Other formats therefore need conversion before submission through that interface.
| Audio Property | Requirement | Engineering Consideration |
|---|---|---|
| Preferred Sample Rate | 24 kHz | Native operating rate |
| Alternative Rate | 16 kHz | Supported lower-rate input |
| Bit Depth | 16-bit | Input should use PCM16 |
| Channels | Mono | Stereo sources require conversion |
| Streaming Container | Raw PCM stream | Appropriate for WebSocket transmission |
| File Container | WAV | Required for supported file workflow |
| Compressed Audio | Conversion required | MP3 and similar inputs should be transcoded |
Transcription Operating Modes
Muse Voice Transcribe supports three important operating patterns: push-to-talk, endpointing and diarization.
These modes allow developers to configure the service according to the application’s interaction model rather than treating every transcription request identically. Public Meta integrations expose the corresponding modes as PUSH_TO_TALK, ENDPOINTING and DIARIZATION.
| Session Mode | Primary Function | Best-Suited Applications |
|---|---|---|
| Push-to-Talk | Treats supplied speech as a single turn | Dictation and voice commands |
| Endpointing | Detects individual speech boundaries | Conversational AI and voice agents |
| Diarization | Adds speaker attribution to speech turns | Meetings, interviews and calls |
Push-to-Talk Mode
Push-to-talk is the simplest operational configuration.
The application effectively controls the speech interaction and provides a recording that should be interpreted as a single conversational turn. This approach is appropriate when another component already determines when recording begins and ends.
Typical applications include voice search, voice commands, short-form dictation and microphone-button interfaces.
Endpointing Mode
Endpointing allows Muse Voice Transcribe to determine conversational speech boundaries.
The model generates speech-onset and speech-endpoint information while processing the audio stream. Meta specifically trains endpointing together with streaming ASR rather than requiring an entirely separate endpoint detector.
| Endpoint Event | Meaning | Application Response |
|---|---|---|
| Speech Onset | User begins speaking | Begin active transcription |
| Partial Transcript | Speech remains in progress | Display or process provisional text |
| Speech Endpoint | Model detects turn completion | Begin downstream AI processing |
| Final Transcript | Turn has stabilized | Store or process completed transcript |
This configuration is especially important for conversational voice agents because detecting the end of a user’s turn quickly can reduce the delay before the AI begins responding.
Diarization Mode
Diarization extends transcription with speaker attribution.
Meta’s underlying architecture uses structural speaker tokens to represent potential speaker changes and distinguish speakers. The model supports conversations containing more than 20 speakers and long audio exceeding one hour at the model capability level.
Speaker identities are anonymous and session-specific rather than persistent biometric identities. A label representing Speaker A identifies a conversational participant within that transcription; it should not be interpreted as proof of that person’s identity across unrelated sessions.
| Diarization Capability | Behaviour |
|---|---|
| Speaker Separation | Native |
| Speaker Labels | Anonymous |
| Speaker Changes | Detected during transcription |
| Supported Speaker Scale | More than 20 speakers at model level |
| Persistent Speaker Identity | No |
| External Offline Diarization | Not required for basic attribution |
Keyword Biasing
Keyword biasing is particularly valuable for enterprise transcription.
Developers can supply important names and domain-specific vocabulary to guide recognition toward terminology that might otherwise be phonetically confused with common words.
LiveKit’s Meta integration confirms that recognition keywords can be supplied during initial session configuration. Once the active stream has been established, those settings cannot be modified without creating another session.
| Keyword Category | Potential Application |
|---|---|
| Company Names | Corporate meetings |
| Product Names | Sales and customer-support calls |
| Employee Names | Internal meetings |
| Technical Terminology | Engineering conversations |
| Industry Vocabulary | Specialized enterprise transcription |
| Brand Terminology | Customer-facing voice applications |
Language Biasing
Muse Voice Transcribe was trained on more than 70 languages, with 25 languages extensively verified by Meta at launch. It can also perform code-switching within or between sentences.
Language biasing allows an application to indicate languages that are likely to occur instead of relying entirely on automatic language detection.
| Configuration | Behaviour |
|---|---|
| No Language Bias | Automatic recognition |
| Single Language Bias | Favors an expected language |
| Multiple Language Biases | Helps multilingual applications |
| Code-Switching | Supported natively |
| Verified Languages | 25 at launch |
| Training Coverage | More than 70 languages |
Language and keyword configuration can therefore be combined for applications operating in specialized multilingual environments.
File Transcription API
Developers processing completed recordings can use the non-streaming transcription workflow rather than maintaining a WebSocket connection.
Current public integrations identify the file operation as an ASR transcription POST request. The request accepts a complete supported recording and returns a completed transcript.
| File API Property | Current Specification |
|---|---|
| Request Type | HTTP POST |
| Audio Container | WAV |
| Encoding | Mono PCM16 |
| Sample Rates | 16 kHz or 24 kHz |
| Maximum Audio Duration | 10 minutes |
| Maximum Request Size | 32 MB |
| Streaming Connection | Not required |
The 10-minute and 32 MB limits apply to the file-upload workflow rather than the model’s underlying ability to process long audio. Longer recordings therefore require segmentation or use of an appropriate streaming workflow.
Real-Time Session Duration
A single real-time WebSocket session is currently capped at approximately 60 minutes according to public Meta integrations.
Once that limit is reached, the connection closes and the client must establish a new session. Pipecat’s Meta integration explicitly handles this behavior by reconnecting to a fresh session.
| Audio Duration | Recommended Integration Strategy |
|---|---|
| Short voice command | Push-to-talk |
| Short uploaded recording | File transcription |
| Live conversation | WebSocket endpointing |
| Multi-speaker meeting | WebSocket diarization |
| Session approaching 60 min | Prepare connection rollover |
| Recording over 10 min | Segment recording or use streaming |
Interim and Final Transcripts
Streaming applications should distinguish provisional transcription from completed transcription.
In endpointing mode, public integrations report a sequence consisting of speech-start information, cumulative partial transcripts, speech-end detection and a completed post-processed transcript.
Partial transcripts are useful for responsive user interfaces, but downstream systems should avoid assuming that every partial word is permanent.
| Transcript State | Stability | Recommended Usage |
|---|---|---|
| Interim Text | Provisional | Live captions and UI feedback |
| Cumulative Partial | Increasingly complete | Real-time display |
| Speech End | Boundary event | Trigger downstream preparation |
| Final Transcript | Stabilized | Storage, analytics and AI processing |
Word-Level Timestamps and Confidence Scores
An important limitation is that Muse Voice Transcribe does not currently expose several metadata features common in mature transcription platforms.
OpenRouter’s current specification explicitly notes the absence of word-level timestamps and confidence scores.
| Output Capability | Native Support | Engineering Impact |
|---|---|---|
| Transcript Text | Yes | Directly usable |
| Interim Transcripts | Yes | Supports live applications |
| Speaker Attribution | Yes | Useful for multi-speaker audio |
| Speech Endpoint Events | Yes | Useful for voice agents |
| Word-Level Timestamps | No | External alignment may be necessary |
| Word Confidence Scores | No | Application must manage uncertainty differently |
| Persistent Speaker Identity | No | External identity mapping required |
These limitations matter for applications such as subtitle editing, legal transcription review and media indexing where precise word-to-audio alignment is required.
Important API Constraints
Several claimed specifications should be separated from publicly verifiable limits. In particular, the frequently cited limits of eight concurrent streams and 1,000 session starts per hour were not confirmed in the publicly accessible Meta materials or reliable integrations reviewed for this section.
They should therefore not be presented as universal Muse Voice Transcribe limits. Rate limits may depend on Meta account configuration, access tier or future API policy.
| Constraint | Verified Public Status | Recommended Engineering Approach |
|---|---|---|
| 60-Minute WebSocket Session | Documented by integrations | Implement automatic session rollover |
| 10-Minute File Duration | Documented | Split longer uploaded recordings |
| 32 MB File Request | Documented | Validate uploads before transmission |
| 16/24 kHz PCM Input | Documented | Resample unsupported input |
| Word-Level Timestamps | Not supported | Add alignment layer when necessary |
| Confidence Scores | Not supported | Implement application-level uncertainty handling |
| Eight Concurrent Streams | Not publicly confirmed | Check current account limits |
| 1,000 Session Starts/Hour | Not publicly confirmed | Check current Meta API quota |
What Developers Should Know Before Integration
Muse Voice Transcribe 1.0 is technically well suited to applications where transcription is part of an interactive voice pipeline rather than merely an offline speech-to-text job.
Its WebSocket streaming architecture, adaptive transcription, native endpointing, speaker diarization, multilingual processing and runtime vocabulary biasing make it particularly relevant for AI voice agents, customer-service platforms, meeting assistants and real-time enterprise applications.
However, developers should design around its current operational boundaries. Audio may require preprocessing, WebSocket sessions need lifecycle management, long file uploads require segmentation, speaker labels are not persistent identities, and applications requiring word-level timestamps or confidence scores need additional processing.
Most importantly, production teams should verify account-specific quotas, authentication requirements, data-handling policies and current API parameters directly within their Meta Model API environment before finalizing infrastructure. These operational details can change independently of the Muse Voice Transcribe model itself.
4. Multilingual Capabilities and Code-Switching Performance
Meta Muse Voice Transcribe 1.0 is designed for multilingual, real-time speech recognition rather than English-only transcription. Meta reports that the model was trained using speech spanning more than 70 languages, with 25 languages extensively verified for its initial September 2026 release.
An important distinction is that training coverage does not necessarily mean every language has identical production-level accuracy. Meta specifically recommends the extensively verified languages as the strongest starting point for developers deploying multilingual applications.
Extensively Verified Languages
The initial recommended set covers major European, Asian and Middle Eastern languages, including several languages widely used across Southeast and South Asia.
| Region | Extensively Verified Languages |
|---|---|
| East Asia | Japanese, Korean, Mandarin Chinese |
| Southeast Asia | Indonesian, Malay, Tagalog, Thai, Vietnamese |
| South Asia | Bengali, Hindi, Kannada, Marathi, Tamil, Telugu |
| Western Europe | Dutch, English, French, German, Italian, Portuguese, Spanish |
| Central and Eastern Europe | Polish, Turkish |
| Middle East | Arabic, Hebrew |
The publicly documented 25-language list consists of Arabic, Bengali, Dutch, English, French, German, Hebrew, Hindi, Indonesian, Italian, Japanese, Kannada, Korean, Malay, Mandarin Chinese, Marathi, Polish, Portuguese, Spanish, Tagalog, Tamil, Telugu, Thai, Turkish and Vietnamese.
Understanding the 70+ Language Claim
The distinction between “trained” and “extensively verified” is important when assessing Muse Voice Transcribe for international deployments.
| Language Classification | Coverage | What It Means |
|---|---|---|
| Training Coverage | 70+ languages | Languages represented during model training |
| Extensively Verified | 25 languages | Languages Meta specifically recommends at launch |
| Multilingual Recognition | Supported | Model can recognize speech across languages |
| Code-Switching | Native | Languages can change within or between sentences |
| Language Biasing | Supported | Expected languages can be supplied as recognition hints |
| Equal Accuracy Across Languages | Not established | Performance should be tested individually |
Meta has not published directly comparable Word Error Rate figures for every one of the 25 verified languages. Enterprises should therefore avoid assuming that the approximately 3.06% English streaming WER reported by Artificial Analysis applies equally to Vietnamese, Hindi, Mandarin, Japanese or other languages.
Native Code-Switching
One of Muse Voice Transcribe’s most notable multilingual capabilities is native code-switching.
Code-switching occurs when a speaker changes languages during a conversation. The transition can occur between sentences or directly within a single sentence.
Meta states that Muse Voice Transcribe supports arbitrary code-switching in both situations.
| Speech Pattern | Muse Voice Transcribe Capability |
|---|---|
| Single-language sentence | Supported |
| Language change between sentences | Supported |
| Language change within a sentence | Supported |
| Multiple languages in conversation | Supported |
| Technical English inside another language | Supported |
| Language biasing | Supported |
| Keyword biasing | Supported |
| Context biasing | Supported |
Why Code-Switching Matters
Conventional multilingual speech-recognition systems may require applications to identify the language before transcription or route speech to different language-specific models.
That architecture becomes problematic when people naturally mix languages.
Muse Voice Transcribe instead treats multilingual speech as part of the same continuous recognition process. Meta’s published architecture allows the model to continue processing the incoming audio stream as languages change rather than requiring the conversation to restart every time a different language appears.
This capability can be particularly useful in multilingual regions and international workplaces.
| Use Case | Typical Code-Switching Challenge | Potential Muse Advantage |
|---|---|---|
| International Meetings | Employees mix English and local languages | Continuous multilingual transcription |
| Customer Support | Customer changes language during call | No separate ASR routing required |
| Technical Discussions | English technical terminology appears in local speech | Context and keyword biasing |
| Education | Instructor mixes languages when explaining concepts | Unified transcript |
| Interviews | Participants naturally alternate languages | Continuous recognition |
| Voice Assistants | Commands contain names and foreign terminology | More natural conversational input |
Meta’s Mandarin-English Demonstration
Meta demonstrated the capability using a particularly demanding Mandarin-English example.
Rather than switching languages at clean sentence boundaries, the speaker repeatedly inserted English technology vocabulary into otherwise Mandarin speech.
The demonstration included terminology associated with local AI inference, hardware specifications, model quantization and decoding. English terms included Ollama, Muse Glimmer, NVIDIA RTX 3090, 4bit GGUF, GDDR6X VRAM, DFlash and speculative decoding.
| Technical Term Type | Example From Meta Demonstration |
|---|---|
| AI Software | Ollama |
| Meta Model | Muse Glimmer |
| GPU | NVIDIA RTX 3090 |
| Quantization | 4bit GGUF |
| GPU Memory | GDDR6X VRAM |
| Decoding Technology | DFlash |
| Inference Technique | Speculative decoding |
This example is significant because technical vocabulary is often among the hardest content for multilingual ASR systems. Product names, abbreviations and hardware identifiers may have pronunciations that do not follow the surrounding language’s normal vocabulary.
Mixed-Script Transcription
Code-switching creates another problem beyond recognizing the spoken words: determining how those words should be written.
Meta’s Mandarin-English demonstration preserves English technical terminology using Latin characters while surrounding Mandarin speech is represented in its expected script. This produces a mixed-script transcript that more closely resembles how many bilingual technology users actually write.
| Spoken Content | Preferred Output Behaviour |
|---|---|
| Mandarin vocabulary | Mandarin script |
| English vocabulary | Latin characters |
| Brand names | Preserve conventional brand spelling |
| Hardware names | Preserve conventional product notation |
| Acronyms | Preserve expected acronym representation |
| Numbers and specifications | Maintain recognizable technical formatting |
Language Biasing
Language biasing allows developers to indicate which languages are expected in a session.
This is a hint rather than necessarily a hard restriction on what the model can recognize. When an application already knows that a conversation is likely to involve particular languages, supplying that information can help guide recognition.
| Configuration Strategy | Suitable Scenario |
|---|---|
| Automatic Recognition | Language is unknown |
| Single-Language Bias | Conversation is primarily one language |
| Multiple-Language Bias | Bilingual meeting or customer call |
| Language + Keyword Bias | Multilingual technical conversation |
| Language + Context Bias | Domain-specific enterprise conversation |
Keyword Biasing for Multilingual Speech
Keyword biasing becomes particularly valuable when English product names, technical abbreviations or company terminology are embedded within another language.
A developer can provide vocabulary that the model should expect to encounter. Meta specifically highlights keyword and context biasing as mechanisms for improving recognition.
| Keyword Category | Example | Why Biasing Helps |
|---|---|---|
| Acronyms | VRAM, GGUF | Prevents phonetic reinterpretation |
| Product Names | Muse Glimmer | Preserves specialized terminology |
| Hardware | NVIDIA RTX 3090 | Improves recognition of model identifiers |
| Company Names | Meta | Helps preserve proper nouns |
| Locations | Menlo Park | Reduces proper-name errors |
| Industry Terminology | Speculative decoding | Improves domain-specific transcription |
Context Biasing
Context biasing provides a broader semantic signal than simply supplying individual keywords.
For example, an enterprise transcription application could provide contextual information indicating that a conversation concerns AI infrastructure, financial services, medical technology or another specialized domain.
Meta’s launch demonstration also showed context biasing helping Muse correctly recognize relevant names and terminology during multilingual conversations.
Together, language, keyword and context biasing give developers several mechanisms for adapting a general multilingual speech model to specialized environments.
Multilingual Voice Agents
Code-switching is especially important for conversational AI.
A multilingual voice agent cannot provide a natural experience if users have to manually select a language every time they change how they speak. Muse Voice Transcribe’s ability to recognize language changes within a sentence potentially removes part of this friction.
| Voice AI Requirement | Muse Capability |
|---|---|
| Real-Time Multilingual ASR | Yes |
| Mid-Sentence Code-Switching | Yes |
| Automatic Language Handling | Yes |
| Language Biasing | Yes |
| Specialized Vocabulary | Keyword biasing |
| Domain Awareness | Context biasing |
| Speaker Separation | Native diarization |
| Turn Completion | Native endpointing |
This combination is relevant to multilingual customer-support bots, travel assistants, enterprise copilots and personal voice assistants.
Applications in Southeast Asia
Muse Voice Transcribe has potentially significant relevance for Southeast Asian deployments because Indonesian, Malay, Tagalog, Thai and Vietnamese are among its extensively verified launch languages, while English is also extensively verified.
In markets where English frequently appears alongside local languages in business, technology and education, native code-switching could reduce the need for complex language-routing infrastructure.
| Application | Multilingual Requirement |
|---|---|
| Contact Centers | Local language plus English terminology |
| Recruitment Interviews | Mixed business and conversational language |
| Banking Support | Local speech plus financial terminology |
| E-Commerce | Product and brand names embedded in local speech |
| Enterprise Meetings | English terminology within local-language discussions |
| Technology Support | Heavy use of English technical vocabulary |
Script Selection and Transliteration Challenges
Code-switching support does not eliminate every multilingual transcription problem.
Third-party evaluations indicate that script representation can affect conventional accuracy measurements. In particular, a system may correctly recognize a borrowed or foreign term phonetically but represent it using the surrounding language’s writing system rather than preserving its original Latin spelling.
From an ASR benchmarking perspective, this can create a large penalty because WER requires textual correspondence with the reference transcript. From a human perspective, the transcription may remain understandable.
For enterprise applications, however, script consistency can matter considerably.
| Potential Issue | Enterprise Impact | Mitigation |
|---|---|---|
| Loanword Transliteration | Search mismatch | Normalize known terminology |
| Acronym Script Conversion | Database matching failures | Supply keyword biasing |
| Brand Name Variation | Entity-resolution errors | Maintain terminology dictionary |
| Mixed-Script Output | Search/indexing inconsistencies | Apply post-processing rules |
| Technical Term Variation | Analytics fragmentation | Normalize canonical terminology |
| Proper-Name Variation | CRM matching problems | Use contextual vocabulary |
Code-Switching Performance Should Be Tested Separately
A model supporting 25 extensively verified languages does not automatically mean every possible combination of those languages has been equally validated.
English-only transcription, Vietnamese-only transcription and Vietnamese-English code-switching are three distinct evaluation scenarios.
| Evaluation Dimension | What Enterprises Should Measure |
|---|---|
| Single-Language WER | Accuracy within each target language |
| Code-Switching WER | Accuracy during language transitions |
| Proper-Noun Accuracy | People, companies and locations |
| Technical Vocabulary | Industry-specific terminology |
| Script Consistency | Correct writing system for borrowed terms |
| Acronym Accuracy | Preservation of abbreviations |
| Number Accuracy | Dates, prices and measurements |
| Semantic Accuracy | Whether meaning remains correct |
| Latency | Response speed during language switching |
Multilingual Strengths and Limitations
Muse Voice Transcribe 1.0 represents an important advancement in real-time multilingual speech recognition because multilingual processing is integrated directly into the model rather than treated as an additional translation layer.
| Area | Assessment |
|---|---|
| Training Language Coverage | Strong, with 70+ languages |
| Extensively Verified Coverage | 25 languages at launch |
| Mid-Sentence Code-Switching | Native support |
| Between-Sentence Switching | Native support |
| Technical Vocabulary | Enhanced through keyword biasing |
| Domain Adaptation | Context biasing supported |
| Southeast Asian Coverage | Strong launch representation |
| Equal Accuracy Across Languages | Not demonstrated |
| Mixed-Script Consistency | Requires application testing |
| Production Reliability | Should be validated using domain-specific audio |
The most important capability is therefore not simply the number of languages Muse Voice Transcribe recognizes. Its differentiator is the ability to treat multilingual speech, code-switching, specialized terminology, speaker changes and conversational boundaries as components of the same continuous audio-perception problem.
For enterprises building multilingual voice agents, contact-center systems, meeting intelligence platforms or international transcription services, this architecture could significantly simplify the speech-processing stack. However, production evaluation should test the exact language combinations, accents, terminology and script conventions encountered by real users rather than assuming that English benchmark performance will transfer uniformly across Meta’s entire multilingual coverage.
5. Commercial Pricing Model and Cost Analysis
Meta has positioned Muse Voice Transcribe 1.0 as an aggressively priced real-time speech-to-text model. At launch, the Meta Model API rate was $3.00 per 1,000 processed audio minutes, equivalent to $0.003 per minute or $0.18 per audio hour. Independent benchmark tracker Artificial Analysis reported the same normalized price in its September 2026 streaming speech-to-text evaluation.
The pricing is particularly notable because Muse combines streaming transcription with capabilities such as endpointing and native diarization rather than requiring developers to construct these functions entirely from separate speech-processing models. Meta confirms that the model performs real-time ASR, endpointing and diarization for more than 20 speakers.
Muse Voice Transcribe 1.0 Pricing
The standard published API rate can be converted into several useful units for budgeting.
| Pricing Measurement | Muse Voice Transcribe 1.0 |
|---|---|
| Cost per Audio Minute | $0.003 |
| Cost per 100 Audio Minutes | $0.30 |
| Cost per 1,000 Audio Minutes | $3.00 |
| Cost per Audio Hour | $0.18 |
| Cost per 100 Audio Hours | $18.00 |
| Cost per 1,000 Audio Hours | $180.00 |
| Cost per 10,000 Audio Hours | $1,800.00 |
The linear pricing makes large-scale forecasting relatively straightforward. For example, processing 1,000 hours of audio would cost approximately $180 at the published rate, while 10,000 hours would cost approximately $1,800.
Pricing Compared With Real-Time Speech-to-Text Competitors
Artificial Analysis’ September 1, 2026 snapshot provides a useful standardized comparison because prices are normalized to 1,000 audio minutes.
| Streaming Speech-to-Text Model | Cost per 1,000 Minutes | Approx. Cost per Hour |
|---|---|---|
| Meta Muse Voice Transcribe 1.0 | $3.00 | $0.18 |
| Cartesia Ink-2 | $4.00 | $0.24 |
| Qwen3 ASR Flash Realtime | $5.40 | $0.324 |
| ElevenLabs Scribe v2 Realtime | $6.50 | $0.39 |
| Deepgram Flux | $6.50 | $0.39 |
| AssemblyAI U3.5 Realtime Pro | $7.50 | $0.45 |
| Google Gemini 3.5 Transcribe Live | $9.00 | $0.54 |
| OpenAI GPT Live Transcribe | $17.00 | $1.02 |
These figures represent the Artificial Analysis normalized benchmark snapshot rather than guaranteed long-term vendor prices. Enterprise discounts, promotional pricing and API pricing changes can alter actual production costs.
Cost Advantage Against Major Competitors
At the September 2026 benchmark prices, Muse costs 25% less than Cartesia Ink-2 and approximately 53.8% less than either ElevenLabs Scribe v2 Realtime or Deepgram Flux.
| Comparison | Competitor Cost | Muse Cost | Muse Cost Reduction |
|---|---|---|---|
| Cartesia Ink-2 | $4.00 / 1,000 min | $3.00 | 25.0% |
| Qwen3 ASR Flash Realtime | $5.40 / 1,000 min | $3.00 | 44.4% |
| ElevenLabs Scribe v2 Realtime | $6.50 / 1,000 min | $3.00 | 53.8% |
| Deepgram Flux | $6.50 / 1,000 min | $3.00 | 53.8% |
| AssemblyAI U3.5 Realtime Pro | $7.50 / 1,000 min | $3.00 | 60.0% |
| Google Gemini 3.5 Transcribe Live | $9.00 / 1,000 min | $3.00 | 66.7% |
| OpenAI GPT Live Transcribe | $17.00 / 1,000 min | $3.00 | 82.4% |
Artificial Analysis also described the broader streaming STT market as having substantial pricing variation, making price an important consideration alongside WER and latency.
Enterprise Cost Analysis
Muse’s pricing becomes more significant when transcription is deployed across thousands of hours of customer calls, meetings or voice-agent interactions.
| Monthly Audio Volume | Muse at $0.18/hr | Cartesia at $0.24/hr | ElevenLabs at $0.39/hr | Deepgram Flux at $0.39/hr |
|---|---|---|---|---|
| 100 hours | $18 | $24 | $39 | $39 |
| 1,000 hours | $180 | $240 | $390 | $390 |
| 5,000 hours | $900 | $1,200 | $1,950 | $1,950 |
| 10,000 hours | $1,800 | $2,400 | $3,900 | $3,900 |
| 50,000 hours | $9,000 | $12,000 | $19,500 | $19,500 |
| 100,000 hours | $18,000 | $24,000 | $39,000 | $39,000 |
At 10,000 audio hours per month, Muse would therefore cost approximately $1,800 at the published rate. The equivalent normalized benchmark pricing would be approximately $2,400 for Cartesia and $3,900 for either ElevenLabs Scribe v2 Realtime or Deepgram Flux.
Annual Enterprise Cost
The differences become more substantial when calculated over a full year.
| Monthly Volume | Muse Annual Cost | Cartesia Annual Cost | ElevenLabs Annual Cost |
|---|---|---|---|
| 1,000 hours | $2,160 | $2,880 | $4,680 |
| 10,000 hours | $21,600 | $28,800 | $46,800 |
| 50,000 hours | $108,000 | $144,000 | $234,000 |
| 100,000 hours | $216,000 | $288,000 | $468,000 |
An organization processing 10,000 hours monthly could therefore save approximately $25,200 annually compared with the $0.39-per-hour benchmark rate.
At 100,000 hours per month, that difference grows to approximately $252,000 annually.
Cost per Voice Agent
Another useful way to evaluate Muse is by estimating transcription expenditure for individual AI voice agents.
Consider a voice agent processing four hours of actual user audio every day.
| Usage Measurement | Audio Volume | Muse Transcription Cost |
|---|---|---|
| Daily | 4 hours | $0.72 |
| 30-Day Month | 120 hours | $21.60 |
| Annual | 1,460 hours | $262.80 |
A deployment with 1,000 equivalent voice-agent workloads would therefore represent approximately $262,800 in annual Muse transcription expenditure before considering volume discounts, infrastructure costs or other components of the voice AI stack.
Diarization Economics
Muse’s native diarization can also affect the total cost of ownership.
Meta designed diarization as part of the same real-time audio perception model rather than requiring an entirely separate offline diarization pipeline. Meta reports support for more than 20 speakers.
Third-party pricing analysis notes that some competing platforms charge separately for speaker labeling. For example, one September 2026 comparison cited AssemblyAI streaming transcription at approximately $0.45 per hour plus approximately $0.12 per hour for streaming diarization.
| Architecture | Potential Billing Components |
|---|---|
| Conventional ASR Stack | Transcription + diarization + endpointing infrastructure |
| Muse Voice Transcribe | Unified real-time transcription and diarization |
| Enterprise Voice Agent | Muse + LLM + text-to-speech + application infrastructure |
The financial advantage is therefore potentially greater than a simple ASR price comparison when an application also requires speaker separation.
Cost per Customer-Support Call
At $0.003 per processed minute, the transcription component of individual conversations is inexpensive.
| Average Call Duration | Approximate Muse Cost |
|---|---|
| 5 minutes | $0.015 |
| 10 minutes | $0.030 |
| 15 minutes | $0.045 |
| 30 minutes | $0.090 |
| 45 minutes | $0.135 |
| 60 minutes | $0.180 |
A contact center processing one million 10-minute calls would generate approximately 10 million audio minutes. At the published Muse rate, the transcription cost would be approximately $30,000 before any negotiated enterprise pricing.
Accuracy, Latency and Price Combined
Price alone does not determine the economics of speech recognition. An inexpensive model that produces poor transcripts can increase downstream correction costs.
Muse’s launch position is notable because its low price coincided with strong Artificial Analysis performance.
| Metric | Muse Voice Transcribe 1.0 |
|---|---|
| Final Streaming WER | 3.0623% |
| First-Partial WER | 3.5747% |
| Final Transcript Latency | 0.163 seconds |
| First-Partial Latency | 0.127 seconds |
| Cost per 1,000 Minutes | $3.00 |
| Approximate Cost per Hour | $0.18 |
Artificial Analysis reported Muse as the leading final-transcript model in its September 1 streaming benchmark snapshot, with approximately 3.1% WER and 0.16-second final latency.
Pricing Claims That Require Caution
Several additional commercial claims circulating around Muse Voice Transcribe are not as clearly documented as the base $0.18-per-hour price.
The available public evidence strongly supports the $3-per-1,000-minute rate. However, claims concerning universal zero-data-retention availability at no additional charge, exact per-second billing granularity and guaranteed pricing parity across every streaming and file-upload configuration should be verified against the current Meta Model API commercial terms before being presented as contractual features.
| Pricing Claim | Verification Assessment |
|---|---|
| $3.00 per 1,000 audio minutes | Publicly supported |
| $0.18 per audio hour | Publicly supported |
| Diarization integrated into Muse | Publicly supported |
| Endpointing integrated into Muse | Publicly supported |
| No separate diarization model required | Publicly supported |
| Exact whole-second billing | Requires current API verification |
| Universal ZDR at no additional charge | Requires current API verification |
| Identical billing for every API mode | Requires current API verification |
| Enterprise volume discounts | Not publicly established |
This distinction is important because technical capability and commercial entitlement are not always the same thing. A feature may exist within the model without establishing that every API account receives identical pricing, quotas, retention policies or contractual terms.
Total Cost of Ownership
Enterprises should also avoid treating the $0.18-per-hour transcription rate as the complete cost of operating a voice AI application.
| Cost Layer | Typical Requirement |
|---|---|
| Speech Recognition | Muse Voice Transcribe |
| AI Reasoning | LLM or conversational model |
| Speech Generation | Text-to-speech model |
| Telephony | Voice carrier or communications platform |
| Storage | Audio and transcript retention |
| Analytics | Conversation processing and reporting |
| Application Infrastructure | Servers, databases and networking |
| Compliance | Governance, auditing and security |
| Monitoring | Reliability and performance observability |
For a pure transcription workload, Muse’s published API rate can be the dominant processing charge. For a complete AI voice-agent system, however, ASR represents only one part of the overall infrastructure budget.
Commercial Positioning of Muse Voice Transcribe 1.0
Meta’s $0.18-per-hour launch pricing gives Muse Voice Transcribe a strong commercial position in the real-time speech recognition market. Artificial Analysis recorded its normalized cost at $3 per 1,000 minutes, compared with $4 for Cartesia Ink-2 and $6.50 for ElevenLabs Scribe v2 Realtime and Deepgram Flux in the September 2026 benchmark snapshot.
For high-volume applications such as contact centers, AI voice agents, meeting transcription, live captions and enterprise conversation intelligence, relatively small differences in per-hour pricing can translate into substantial annual savings.
Muse’s larger economic advantage, however, comes from the combination of price and architecture. Real-time ASR, endpointing, multilingual code-switching and speaker diarization are integrated into a single audio perception model. This potentially reduces not only API expenditure but also the engineering complexity associated with coordinating multiple independent speech-processing services.
6. Application Deployment Patterns and Real-World Use Cases
Meta Muse Voice Transcribe 1.0 is designed as a real-time audio perception layer that can sit between human speech and downstream applications such as AI agents, developer tools, meeting assistants and accessibility software.
Meta has already deployed the model within its own ecosystem. Muse Voice Transcribe powers voice dictation across Meta AI for Mac and Muse Code, while external developers can build applications around the same underlying model through the Meta Model API. Meta specifically describes the technology as capable of streaming ASR, endpointing and diarization in real time.
Where Muse Voice Transcribe Fits in an AI Application
Muse Voice Transcribe is primarily a perception model. Its role is to transform incoming speech into structured textual and conversational information that other software can act upon.
A typical deployment architecture looks like this:
Microphone or Audio Stream → Muse Voice Transcribe → Transcript and Conversation Events → LLM or Application Logic → Action or Response
For conversational applications, an additional speech-generation model can turn the response back into spoken audio.
| Application Layer | Typical Technology | Primary Responsibility |
|---|---|---|
| Audio Input | Microphone or telephony | Capture speech |
| Speech Perception | Muse Voice Transcribe | Transcription, endpointing and diarization |
| Reasoning | LLM or application logic | Understand requests and determine actions |
| Business Integration | APIs and databases | Execute application-specific workflows |
| Speech Output | Text-to-speech model | Generate spoken responses |
| User Interface | Desktop, mobile or web | Present transcripts and responses |
Meta AI for Mac Dictation
One of the clearest real-world deployments is system-wide dictation through Meta AI for Mac.
Meta states that users can hold the Fn key and dictate while working with applications and windows on their Mac. The spoken input is transcribed by Muse Voice Transcribe, providing a practical demonstration of the model as a general-purpose voice input layer rather than simply a standalone transcription service.
| Dictation Requirement | Muse Voice Transcribe Contribution |
|---|---|
| Immediate Voice Input | Streaming transcription |
| Fast Visual Feedback | 80 ms audio processing cycle |
| Specialized Terminology | Keyword and context biasing |
| Multilingual Dictation | 25 extensively verified languages |
| Mixed-Language Speech | Native code-switching |
| Long Dictation | Long-context audio support |
Muse Code and Voice-Driven Development
Muse Voice Transcribe also powers dictation within Meta’s Muse Code development environment.
This creates an interesting application of speech recognition: voice-driven software development. Instead of typing every instruction, developers can describe programming tasks, implementation requirements or coding-agent instructions verbally.
Meta explicitly identifies Muse Code as one of the products powered by Muse Voice Transcribe.
| Developer Workflow | Potential Voice Application |
|---|---|
| Coding Instructions | Describe requested changes verbally |
| Agent Prompts | Dictate development tasks |
| Documentation | Convert technical explanations into text |
| Bug Reports | Describe observed software problems |
| Code Reviews | Dictate review comments |
| Technical Notes | Capture ideas without leaving the IDE |
Keyword and context biasing can be particularly valuable in this environment because programming conversations frequently contain library names, APIs, variables, model names and technical abbreviations.
Conversational AI Voice Agents
Voice agents are one of the strongest potential deployment patterns for Muse Voice Transcribe.
Traditional voice agents frequently combine automatic speech recognition with separate voice activity detection and endpoint-detection systems. Muse instead trains endpointing directly alongside streaming ASR.
The model emits dedicated speech-onset and speech-endpoint information that applications can use to identify conversational turns.
User Speech → Streaming ASR → Speech Endpoint → LLM Processing → Response Generation → Text-to-Speech
| Voice Agent Requirement | Muse Capability | Operational Benefit |
|---|---|---|
| Real-Time Transcription | Streaming ASR | Processes speech as it arrives |
| User Starts Talking | Speech onset detection | Identifies beginning of turn |
| User Stops Talking | Endpointing | Enables rapid LLM handoff |
| Multilingual Users | Code-switching | Supports natural language switching |
| Specialized Vocabulary | Keyword biasing | Improves domain terminology |
| Conversation Context | Context biasing | Improves recognition of relevant terms |
Why Endpointing Matters for Voice Agents
A conversational AI system must determine not only what somebody said but when that person has finished speaking.
Waiting too long creates an unnatural pause. Responding too early risks interrupting the speaker.
Muse Voice Transcribe introduces dedicated speech-onset and speech-endpoint tokens into the same model responsible for transcription. Meta trains endpointing jointly with streaming ASR, allowing the model to make conversational boundary decisions using speech context rather than relying exclusively on fixed silence thresholds.
This makes Muse particularly suitable as the “ears” of a real-time AI agent.
Contact Center Assistants and Agent Copilots
Contact centers represent another potentially strong enterprise deployment.
Muse can transcribe conversations while simultaneously distinguishing different speakers. A contact-center application could use those outputs to separate customer and agent turns before passing the conversation into analytics or an AI assistant.
| Contact Center Function | Muse Role | Downstream Application |
|---|---|---|
| Live Call Transcription | Streaming ASR | Agent transcript |
| Agent/Customer Separation | Diarization | Conversation analytics |
| Turn Detection | Endpointing | Real-time AI assistance |
| Product Terminology | Keyword biasing | Improved recognition |
| Multilingual Calls | Code-switching | International support |
| Conversation Analysis | Structured transcript | LLM-generated insights |
Potential downstream functions include answer recommendations, knowledge-base retrieval, compliance prompts, automatic notes, call summaries and CRM updates.
Meeting Intelligence
Muse Voice Transcribe supports more than 20 speakers and audio exceeding one hour at the model level, making meeting intelligence another natural application.
Meta demonstrated the model transcribing eight people speaking in the same room while assigning speaker labels in real time.
Meeting Audio → Speaker-Aware Transcript → LLM Analysis → Summary, Decisions and Action Items
| Meeting Intelligence Feature | Muse Contribution |
|---|---|
| Live Notes | Streaming transcription |
| Speaker Separation | Native diarization |
| Long Meetings | More than one hour of audio context |
| International Meetings | Multilingual recognition |
| Mixed Languages | Code-switching |
| Technical Meetings | Keyword and context biasing |
An LLM downstream from Muse could subsequently summarize discussions, identify decisions and extract action items.
Interviews and Recruitment
Recruitment platforms and interview-intelligence systems could similarly use the model to capture conversations between interviewers and candidates.
Native diarization is particularly useful because the transcript can preserve conversational structure instead of producing a single uninterrupted text block.
| Recruitment Application | Potential Implementation |
|---|---|
| Candidate Interviews | Speaker-aware transcript |
| Recruiter Notes | Real-time dictation |
| Interview Summaries | LLM processing of transcript |
| Technical Interviews | Keyword-biased recognition |
| Multilingual Interviews | Code-switching support |
| Panel Interviews | Multi-speaker diarization |
Human review remains important where transcripts contribute to consequential employment decisions.
Live Captioning and Accessibility
The model’s continuous 80-millisecond audio processing architecture also makes it suitable for real-time captions and accessibility interfaces.
Muse does not wait for an entire recording to finish before producing output. Instead, it continuously decides whether to listen for additional audio or emit transcription tokens.
| Accessibility Application | Relevant Capability |
|---|---|
| Live Captions | Streaming ASR |
| Multi-Speaker Captions | Diarization |
| International Events | Multilingual transcription |
| Bilingual Conversations | Code-switching |
| Voice Navigation | Low-latency transcription |
| Voice Commands | Endpoint detection |
Multilingual Customer Service
Multilingual support creates another important deployment pattern.
Muse was trained across more than 70 languages, with 25 extensively verified at launch. It can also handle language switching within the same sentence.
This architecture could reduce the need for systems that first classify a caller’s language and then route the audio into a completely different ASR engine.
Customer Speech → Muse Multilingual ASR → Unified Transcript → Customer-Service AI
For multinational businesses, this can simplify voice infrastructure when customers naturally combine English with another language.
Media, Podcasts and Long-Form Audio
Long-context support and speaker diarization also make Muse applicable to podcasts, recorded discussions and other long-form content.
| Media Workflow | Potential Muse Function |
|---|---|
| Podcast Transcription | Generate searchable text |
| Panel Discussions | Identify different speakers |
| Recorded Interviews | Preserve interviewer and guest turns |
| Video Captions | Generate transcription |
| Content Repurposing | Feed transcripts into downstream LLMs |
| Archive Search | Convert spoken content into searchable data |
Applications requiring frame-accurate subtitles or precise word-level synchronization may still require a separate alignment layer.
Recommended Deployment Patterns
Different applications should use different parts of the Muse architecture rather than applying one configuration universally.
| Recommended Use Case | Core Architectural Advantage | Implementation Consideration |
|---|---|---|
| Conversational Voice Agents | Native endpointing | Connect transcript output to an LLM |
| Contact Center Copilots | Streaming diarization | Validate speaker assignments |
| Meeting Intelligence | Multi-speaker transcription | Add summarization downstream |
| Live Dictation | Low-latency streaming ASR | Apply vocabulary biasing where useful |
| Voice Coding | Context and keyword biasing | Supply technical terminology |
| Multilingual Support | Native code-switching | Test target language combinations |
| Live Captioning | Continuous transcription | Handle provisional transcript updates |
| Interviews | Speaker-aware transcript | Review consequential records |
| Long-Form Media | Long audio context | Add timestamp alignment if required |
High-Stakes Legal, Medical and Financial Applications
High transcription accuracy does not automatically make an ASR model suitable for unattended high-stakes record keeping.
Legal proceedings, clinical documentation, financial instructions and regulated communications may require exact wording, reliable speaker attribution and auditable timestamps.
| Risk Area | Why It Matters | Recommended Safeguard |
|---|---|---|
| Transcription Error | Words may be incorrectly recognized | Human review |
| Speaker Confusion | Diarization can misattribute speech | Verify speaker identity |
| Numbers | Financial or medical values can be critical | Explicit validation |
| Proper Names | Names may be incorrectly transcribed | Context and keyword biasing |
| Timestamps | Precise alignment may be required | External alignment system |
| Compliance | Regulations vary by application | Governance and audit controls |
Muse should therefore be treated as an AI-generated transcription layer rather than an automatically authoritative legal or clinical record.
Understanding Diarization Risk
Meta reported an average Diarization Error Rate of 17.5% across the AMI-IHM, AMI-SDM and VoxConverse evaluation used in its launch materials. That result should not be interpreted as meaning that one out of every six minutes necessarily receives the wrong speaker label.
DER incorporates several categories of speaker-attribution error, including speaker confusion, missed speech and false-alarm speech.
Nevertheless, the benchmark reinforces an important deployment principle: speaker labels should be validated when attribution has legal, financial, medical or other consequential implications.
Real-World Applications Versus Unverified Examples
Some third-party pages associate Muse Voice Transcribe with applications or projects carrying names such as heyBen Talking Mode, Neo Coding Assistant, Gyeol Translate, Nano Banana Canvas and Handy.
However, reliable primary evidence establishing these applications as production Muse Voice Transcribe deployments was not found in the sources reviewed. They should therefore not be presented as confirmed customer case studies.
The publicly verifiable deployments are substantially clearer:
| Deployment | Verification Status | Application |
|---|---|---|
| Meta AI for Mac | Confirmed by Meta | System-wide voice dictation |
| Muse Code | Confirmed by Meta | Developer voice input |
| Meta Model API | Confirmed by Meta | Third-party application development |
| Meta Research Demo | Confirmed by Meta | Live multi-speaker transcription |
| Third-Party Voice Agents | Technically supported | Individual deployments require verification |
| Third-Party Coding Tools | Technically supported | Individual deployments require verification |
This distinction is important for accurately describing the model’s real-world adoption rather than converting technically possible use cases into unsupported customer claims.
Muse Voice Transcribe Deployment Matrix
The model’s capabilities make it particularly attractive where multiple speech-processing requirements occur simultaneously.
| Application | Streaming ASR | Endpointing | Diarization | Code-Switching | Biasing |
|---|---|---|---|---|---|
| Voice Agent | High | High | Optional | High | High |
| Contact Center | High | High | High | High | High |
| Meeting Assistant | High | Medium | High | High | High |
| Mac Dictation | High | Medium | Low | High | High |
| Voice Coding | High | Medium | Low | Medium | High |
| Live Captions | High | Medium | High | High | Medium |
| Interview Platform | High | Medium | High | High | High |
| Podcast Transcription | Medium | Low | High | Medium | Medium |
| Accessibility Tool | High | High | Medium | High | Medium |
Enterprise Deployment Considerations
Muse Voice Transcribe 1.0 is most compelling when organizations need more than basic speech-to-text. Its unified architecture combines streaming recognition, endpointing, speaker diarization, multilingual processing and contextual biasing within the same audio perception model.
This can simplify application architecture by reducing the number of independent speech-processing components developers must coordinate.
However, production deployments should still implement appropriate transcript validation, session management, error handling, monitoring and human review. Organizations operating in regulated industries should also independently assess privacy, retention, security and compliance requirements before sending sensitive audio to a hosted transcription service.
The strongest real-world opportunities for Muse Voice Transcribe therefore lie in conversational voice agents, contact-center copilots, meeting intelligence, multilingual transcription, live dictation, accessibility systems and voice-driven developer workflows. Meta’s own deployment across Meta AI for Mac and Muse Code demonstrates that the company is positioning Muse Voice Transcribe not simply as another transcription API, but as a reusable real-time speech perception layer for the emerging voice-first AI ecosystem.
7. Strategic Assessment and Future Outlook
Meta Muse Voice Transcribe 1.0 represents a significant architectural development in real-time speech AI. Rather than treating transcription, speaker diarization and conversational endpoint detection as separate problems, Meta has trained these capabilities within a unified autoregressive audio perception model.
The strategic importance extends beyond benchmark accuracy. Muse suggests that real-time speech infrastructure may increasingly evolve from collections of specialized models into unified perception systems capable of understanding both spoken content and conversational structure.
Meta describes Muse Voice Transcribe as its first real-time audio perception model, indicating that the company views the September 2026 release as an initial step rather than the endpoint of its voice-model strategy.
From Modular Speech Pipelines to Unified Audio Perception
Traditional production voice systems commonly combine multiple components. Voice activity detection identifies speech, ASR converts audio into text, diarization identifies speakers, and endpointing determines when conversational turns finish.
Muse Voice Transcribe challenges this architecture by generating transcription and conversational information within a single model.
| Architectural Function | Traditional Voice Stack | Muse Voice Transcribe Approach |
|---|---|---|
| Speech Recognition | Dedicated ASR model | Unified model |
| Speaker Diarization | Separate diarization system | Native generation |
| Turn Detection | VAD or endpoint detector | Native endpointing |
| Speaker Tracking | Post-processing or separate service | Integrated speaker representation |
| Multilingual Recognition | Potential language routing | Native multilingual processing |
| Code-Switching | Additional routing may be required | Native capability |
| Processing Architecture | Multiple coordinated components | Single autoregressive perception model |
Meta reports that Muse performs streaming ASR, diarization for more than 20 speakers and endpointing in real time, while also supporting multilingual code-switching and language, keyword and context biasing.
Why Architectural Consolidation Matters
The attraction of a unified architecture is not simply having fewer models.
Every additional component in a real-time voice pipeline introduces another interface where data must be transferred, synchronized and interpreted. Separate services can also produce conflicting assumptions about timestamps, speaker boundaries and conversational turns.
A unified model can potentially reduce these coordination requirements.
Audio Stream → Unified Speech Perception → Structured Conversation → AI Agent or Application
Instead of:
Audio → VAD → ASR → Diarization → Endpoint Detection → Reconciliation → Application
| Potential Advantage | Strategic Impact |
|---|---|
| Fewer Speech Components | Simpler application architecture |
| Shared Model State | Greater contextual continuity |
| Native Endpointing | Faster conversational handoff |
| Native Diarization | Reduced dependence on post-processing |
| Unified Multilingual Processing | Less language-routing complexity |
| Integrated Biasing | Better domain-specific recognition |
| Fewer Service Boundaries | Potentially lower coordination latency |
The Rise of Speech Perception Models
Muse also illustrates a broader conceptual shift from speech recognition toward speech perception.
Traditional ASR principally answers: “What words were spoken?”
A real-time perception model attempts to provide additional information:
What was said?
Who was speaking?
When did the speaker begin?
When did the speaker finish?
Did the language change?
Should the model wait for additional context?
This richer interpretation is particularly valuable for conversational AI because an intelligent voice system needs conversational structure, not merely a transcript.
Strategic Importance for AI Voice Agents
Voice agents could become one of the largest beneficiaries of this architectural direction.
A conventional AI voice agent must coordinate speech detection, transcription, turn detection, reasoning and speech synthesis. Errors or latency anywhere in this sequence can make the conversation feel unnatural.
Muse reduces part of that orchestration by combining several input-side functions.
| Voice Agent Layer | Muse Contribution |
|---|---|
| Speech Detection | Speech-onset information |
| Speech Recognition | Streaming ASR |
| Turn Completion | Native endpointing |
| Multiple Speakers | Native diarization |
| Multilingual Input | 25 extensively verified languages |
| Language Switching | Native code-switching |
| Domain Terminology | Keyword and context biasing |
| Reasoning | Requires downstream AI |
| Spoken Response | Requires text-to-speech |
The likely long-term direction is therefore not Muse replacing the complete voice AI stack. Instead, it can become a highly capable perception layer feeding reasoning and speech-generation systems.
Pricing as a Strategic Weapon
Meta’s launch pricing is equally significant.
Muse Voice Transcribe is currently tracked at approximately $3 per 1,000 audio minutes, equivalent to $0.18 per hour. Independent September 2026 tracking also places it at approximately 3.06% English streaming WER and 163 milliseconds of final-transcript latency.
| Strategic Dimension | Muse Launch Position |
|---|---|
| API Price | $3 per 1,000 minutes |
| Approximate Hourly Cost | $0.18 |
| Streaming WER Snapshot | Approximately 3.06% |
| Final Latency Snapshot | Approximately 163 ms |
| Speaker Diarization | More than 20 speakers |
| Endpointing | Integrated |
| Code-Switching | Integrated |
The combination matters more than any individual metric. Meta is competing simultaneously on transcription quality, latency, conversational capabilities and price.
Pressure on Specialized Speech-to-Text Vendors
If low-cost unified speech models continue improving, specialist ASR providers may increasingly need to differentiate beyond basic transcription.
Competing primarily on Word Error Rate becomes harder when several vendors produce sufficiently accurate transcription at increasingly low prices.
Future differentiation may consequently move toward enterprise-specific capabilities.
| Traditional Differentiator | Emerging Competitive Differentiator |
|---|---|
| Lower WER | Domain-specific workflow intelligence |
| More Languages | Better multilingual enterprise workflows |
| Faster ASR | End-to-end conversational responsiveness |
| Basic Diarization | Reliable speaker-aware analytics |
| Transcription API | Agent-ready voice infrastructure |
| Generic Speech Recognition | Industry-specific models and controls |
| API Availability | Governance, deployment and observability |
Mature providers can still differentiate through compliance, deployment flexibility, specialized vocabulary, telephony optimization, analytics, support and enterprise governance.
The Trade-Off: Simplicity Versus Modularity
Unified models introduce their own architectural disadvantages.
A modular speech pipeline gives engineering teams substantial control. A company can replace its VAD while keeping the existing ASR engine, deploy specialized diarization for particular acoustic conditions or run sensitive components locally.
A unified hosted model reduces this flexibility.
| Consideration | Modular Architecture | Unified Muse Architecture |
|---|---|---|
| Component Replacement | High flexibility | Limited |
| Architecture Complexity | Higher | Lower |
| Independent Optimization | Strong | Limited |
| Deployment Control | Potentially extensive | API-dependent |
| Integration Complexity | Higher | Potentially lower |
| Vendor Dependency | Can be distributed | Greater concentration |
| Troubleshooting | Component-level | More model-dependent |
| Model State | Fragmented | Unified |
Closed API and Vendor Dependency
Another important strategic limitation is deployment control.
Muse Voice Transcribe is currently delivered through Meta’s hosted ecosystem rather than as openly downloadable model weights. Organizations therefore depend on Meta for model availability, API behavior, pricing and operational policies.
That distinction matters for organizations requiring air-gapped infrastructure, strict data residency or highly customized inference environments.
| Enterprise Requirement | Current Strategic Consideration |
|---|---|
| Hosted API Deployment | Strong fit |
| Rapid Voice-Agent Development | Strong fit |
| Self-Hosted Inference | Limited |
| Air-Gapped Deployment | Potential limitation |
| Custom Model Modification | Limited |
| Infrastructure Independence | Lower than open-weight alternatives |
| Specialized Compliance | Requires individual assessment |
Missing Enterprise Metadata
Muse also lacks some features that specialized transcription platforms provide.
Current reporting indicates that the API provides turn-level rather than word-level timestamps and does not expose word-level confidence scores. VentureBeat additionally reports that sound-event and emotion detection are absent.
| Capability | Muse Voice Transcribe 1.0 |
|---|---|
| Streaming Transcription | Supported |
| Speaker Diarization | Supported |
| Endpointing | Supported |
| Code-Switching | Supported |
| Context Biasing | Supported |
| Word-Level Timestamps | Not currently provided |
| Word-Level Confidence | Not currently provided |
| Sound Event Detection | Not currently provided |
| Emotion Detection | Not currently provided |
These omissions can matter for subtitle synchronization, forensic review, regulated transcription, quality-assurance systems and applications requiring precise alignment between words and recordings.
Future Direction: Voice-Native AI
Muse Voice Transcribe should also be viewed within Meta’s broader AI strategy.
Meta launched Muse Voice Transcribe on September 1, 2026 as the first real-time audio perception model from Meta Superintelligence Labs. Meta’s broader Muse ecosystem has subsequently expanded into consumer and agentic AI products, reinforcing the company’s increasing investment in voice-enabled and multimodal AI experiences.
This creates several plausible directions for future development.
| Future Direction | Potential Development |
|---|---|
| Voice Agents | Tighter integration between perception and reasoning |
| Multimodal Assistants | Combined audio, visual and contextual understanding |
| Desktop AI | Persistent voice interaction across applications |
| Smart Glasses | Real-time environmental and conversational perception |
| Enterprise Agents | Voice-controlled workflow execution |
| Meeting Intelligence | Richer conversational understanding |
| Developer Tools | Natural voice interaction with coding agents |
| Accessibility | More responsive speech-driven interfaces |
From Speech-to-Text Toward Speech-to-Action
Perhaps the most strategically important transition is from speech-to-text toward speech-to-action.
Traditional transcription ends when words have been converted into text.
Agentic systems can treat transcription as only the first stage.
Speech → Perception → Intent → Reasoning → Tool Use → Action
For example, a user could verbally request a meeting, describe a coding change, ask an enterprise agent to update a CRM record or instruct an assistant to research and purchase something.
Muse Voice Transcribe’s role would be to convert the spoken interaction into sufficiently accurate, structured conversational input for the agent performing those actions.
Strategic Strengths and Risks
| Strategic Factor | Assessment |
|---|---|
| Streaming Accuracy | Strong launch benchmark performance |
| Latency | Highly competitive |
| API Pricing | Aggressive |
| Unified Architecture | Major technical differentiator |
| Native Diarization | Strong capability |
| Endpointing | Valuable for conversational AI |
| Multilingual Support | Broad |
| Code-Switching | Important international advantage |
| Self-Hosting | Current weakness |
| Word-Level Metadata | Current limitation |
| Vendor Independence | Limited |
| Enterprise Customization | Less flexible than modular stacks |
Future Competitive Landscape
Muse Voice Transcribe is unlikely to eliminate specialized speech-recognition vendors. Instead, it changes the competitive baseline.
Basic streaming transcription is becoming cheaper, faster and increasingly integrated with other conversational capabilities. As that happens, value is likely to migrate upward toward complete voice infrastructure, enterprise workflows, specialized industry intelligence and agentic systems.
Speech vendors may therefore compete less on “how accurately can this API transcribe a sentence?” and increasingly on “how effectively can this platform understand and operationalize a conversation?”
Overall Strategic Assessment
Meta Muse Voice Transcribe 1.0 represents an important step toward unified real-time audio perception.
Its architectural significance comes from treating transcription, speaker attribution, endpointing, multilingual processing and conversational structure as interconnected outputs of one model rather than independent stages assembled into a speech pipeline. Meta’s launch positioning, aggressive pricing and strong initial benchmark performance make that approach commercially significant as well as technically interesting.
Its limitations remain meaningful. Hosted API dependency, lack of open weights, limited word-level metadata and reduced component-level customization can make traditional modular architectures preferable for certain regulated or highly specialized deployments.
Nevertheless, Muse Voice Transcribe provides a clear indication of where real-time voice AI is heading: away from speech-to-text as an isolated utility and toward unified speech perception as the input layer for conversational and agentic AI systems. If this architectural direction continues, future voice interfaces will increasingly be designed not simply to transcribe human speech, but to understand conversational structure quickly enough for AI systems to reason and act in real time.
Conclusion
Meta Muse Voice Transcribe 1.0 represents an important evolution in real-time speech AI, moving beyond conventional speech-to-text toward a more unified approach to audio perception. By combining streaming automatic speech recognition, speaker diarization, conversational endpoint detection, multilingual processing and code-switching within a single model, Muse Voice Transcribe can simplify many of the complex pipelines traditionally required for voice-enabled applications.
Its strongest advantages are the combination of low-latency transcription, competitive accuracy, native multi-speaker processing and multilingual capabilities. These characteristics make Meta Muse Voice Transcribe 1.0 particularly relevant for AI voice agents, contact-center copilots, meeting intelligence platforms, live captions, accessibility tools, voice-driven developer workflows, real-time dictation and multilingual enterprise applications.
The model also demonstrates how speech recognition is becoming increasingly integrated with conversational AI. Instead of merely determining what was said, Muse Voice Transcribe can help applications understand when someone starts or stops speaking, distinguish between different participants and process conversations that switch between languages. This richer conversational structure can then be passed to large language models and other AI systems for reasoning, summarization, workflow automation and response generation.
However, Muse Voice Transcribe 1.0 is not a complete replacement for every speech-processing architecture. Organizations requiring self-hosted models, highly customized speech components, precise word-level timestamps, detailed confidence scores or specialized compliance controls may still benefit from modular or domain-specific alternatives. Enterprises should also test transcription and diarization performance against their own accents, languages, terminology, audio environments and real-world workloads before production deployment.
Ultimately, Meta Muse Voice Transcribe 1.0 highlights the broader direction of the voice AI industry. Speech-to-text is evolving from a standalone transcription utility into a real-time perception layer for intelligent applications. As conversational agents, multimodal assistants and voice-controlled software become more widespread, unified models such as Muse Voice Transcribe could play an increasingly important role in enabling AI systems to listen, understand conversational structure and respond to human speech with significantly less friction.
If you find this article useful, why not share it with your hiring manager and C-level suite friends and also leave a nice comment below?
We, at the 9cv9 Research Team, strive to bring the latest and most meaningful data, guides, and statistics to your doorstep.
To get access to top-quality guides, click over to 9cv9 Blog.
To hire top talents using our modern AI-powered recruitment agency, find out more at 9cv9 Modern AI-Powered Recruitment Agency.
People Also Ask
What is Meta Muse Voice Transcribe 1.0?
Meta Muse Voice Transcribe 1.0 is a real-time speech AI model designed to convert spoken audio into text while supporting speaker diarization, endpoint detection, multilingual speech and code-switching.
How does Meta Muse Voice Transcribe 1.0 work?
Muse Voice Transcribe processes streaming audio in small chunks and generates text as speech arrives. Its unified architecture can also detect speaker turns and determine when an utterance begins or ends.
Who developed Muse Voice Transcribe 1.0?
Muse Voice Transcribe 1.0 was developed by Meta Superintelligence Labs as part of Meta’s Muse family of AI models for real-time voice and multimodal applications.
What is Muse Voice Transcribe 1.0 used for?
Muse Voice Transcribe can power AI voice agents, meeting transcription, contact centers, live captions, dictation, accessibility tools, developer applications and multilingual voice interfaces.
Is Meta Muse Voice Transcribe a speech-to-text model?
Yes. Muse Voice Transcribe performs automatic speech recognition, but it goes beyond basic speech-to-text by integrating speaker diarization and speech endpoint detection into the same real-time model.
Does Muse Voice Transcribe support real-time transcription?
Yes. Muse Voice Transcribe is designed for streaming transcription, allowing applications to process and transcribe speech while a person is still speaking rather than waiting for an entire recording.
What is speaker diarization in Muse Voice Transcribe?
Speaker diarization identifies different speakers within an audio stream and associates speech with speaker labels. This makes transcripts easier to understand in meetings, interviews and conversations.
How many speakers can Muse Voice Transcribe handle?
Meta says Muse Voice Transcribe can perform diarization with more than 20 speakers, making it suitable for multi-person meetings, discussions and other complex conversational audio.
What is endpointing in Muse Voice Transcribe?
Endpointing determines when a speaker’s utterance has started and finished. It helps voice applications respond quickly without relying solely on fixed silence thresholds or separate endpointing systems.
What is Adaptive Delay in Muse Voice Transcribe?
Adaptive Delay is Meta’s approach for dynamically deciding how long the model should listen before producing words, helping balance transcription accuracy with the low latency required by real-time voice applications.
How fast is Meta Muse Voice Transcribe 1.0?
Muse is designed for low-latency streaming speech recognition. At launch, Meta reported leading performance on streaming speech benchmarks, although actual latency depends on audio, network and application conditions.
How accurate is Muse Voice Transcribe 1.0?
Artificial Analysis reported about 3.1% word error rate for Muse in its English streaming benchmark at launch. Real-world accuracy can vary significantly with accents, noise, languages and recording quality.
What languages does Muse Voice Transcribe support?
Meta trained Muse Voice Transcribe using more than 70 languages and reported extensive verification across 25 languages at launch, supporting a broad range of multilingual voice applications.
Does Muse Voice Transcribe support code-switching?
Yes. Muse Voice Transcribe supports code-switching, allowing it to recognize conversations where speakers change languages within the same sentence or across different parts of a conversation.
Does Muse Voice Transcribe support English?
Yes. English is among the extensively verified languages for Muse Voice Transcribe, and its launch benchmarking included strong results on English streaming speech recognition tests.
Can Muse Voice Transcribe identify individual people?
Muse can distinguish speakers through diarization, but its speaker labels are session-based rather than persistent biometric identities. Applications should not treat those labels as verified personal identification.
Can Muse Voice Transcribe transcribe meetings?
Yes. Its real-time transcription and multi-speaker diarization make Muse suitable for meeting transcripts. Applications can add downstream AI systems to generate summaries, action items and searchable meeting notes.
Can Muse Voice Transcribe be used for AI voice agents?
Yes. Streaming transcription and endpoint detection make Muse well suited to conversational AI agents because applications can recognize speech and determine when users have finished speaking before generating responses.
Can Muse Voice Transcribe be used in contact centers?
Yes. Contact centers can use Muse for real-time transcription and speaker-aware conversations, then connect the transcript to AI systems for agent assistance, summaries, CRM updates and conversation analysis.
Can Muse Voice Transcribe be used for interviews?
Yes. Muse can support recruitment, research and media interviews by generating speaker-aware transcripts. Keyword and language biasing can also help applications handle specialized terminology and names.
Can Muse Voice Transcribe generate live captions?
Yes. Its streaming speech recognition makes it suitable for live captioning and accessibility applications where spoken content needs to appear as text with minimal delay.
Can developers access Meta Muse Voice Transcribe 1.0?
Yes. Meta provides developer access to Muse Voice Transcribe through the Meta Model API, enabling developers to integrate real-time speech perception into applications and AI workflows.
What is the Muse Voice Transcribe 1.0 API model name?
The API model identifier is muse-voice-transcribe-1.0. Developers should check Meta’s current Model API documentation because availability, capabilities and API specifications can change.
How much does Muse Voice Transcribe 1.0 cost?
At launch, public benchmark data listed Muse at about $3 per 1,000 audio minutes, equivalent to roughly $0.003 per minute or $0.18 per audio hour. Current API pricing should be verified with Meta.
Is Meta Muse Voice Transcribe 1.0 open source?
No downloadable open weights for Muse Voice Transcribe 1.0 were released at launch. It is primarily offered as a hosted model, so it should not be assumed to support local or self-hosted deployment.
Does Muse Voice Transcribe provide word-level timestamps?
Muse Voice Transcribe did not provide word-level timestamps at launch. Applications requiring precise subtitle synchronization or word-level alignment may need an additional alignment or transcription layer.
Does Muse Voice Transcribe provide confidence scores?
Word-level confidence scores were not part of Muse Voice Transcribe’s initial public capabilities. Applications requiring detailed confidence metadata may need additional validation or speech-processing tools.
What audio format does Muse Voice Transcribe support?
Real-time integrations commonly use mono signed 16-bit PCM audio, with 24 kHz preferred and 16 kHz supported. File-based integrations can use compatible PCM16 WAV audio.
What are the advantages of Meta Muse Voice Transcribe 1.0?
Its main advantages include low-latency transcription, integrated diarization and endpointing, multilingual recognition, code-switching and competitive API pricing within a unified real-time speech model.
What are the limitations of Muse Voice Transcribe 1.0?
Key limitations include no released open weights, dependence on Meta’s hosted infrastructure, lack of word-level timestamps and confidence scores, and accuracy that can vary across languages and real-world audio conditions.
Sources
Layer3Labs Kingy AI BibiGPT Meta AI Research The Decoder OpenRouter The New Stack BenchLM Meta for Developers Reddit The Indian Express