


Key Takeaways
- Cohere Command A+ is a 218B-parameter Sparse Mixture-of-Experts enterprise AI model with approximately 25B active parameters per token for efficient reasoning and agentic workflows.
- Command A+ combines multimodal understanding, RAG, tool use, citations, multilingual processing, and a 128K context window for complex enterprise AI applications.
- Apache 2.0 licensing, open weights, W4A4 quantization, and self-hosting support make Command A+ suitable for private, on-premises, and sovereign AI deployments.
Cohere Command A+ powers enterprise AI applications with advanced reasoning, multimodal understanding, multilingual processing, RAG, and agentic workflows. The open-weight model uses a Sparse Mixture-of-Experts architecture with 218 billion total parameters and approximately 25 billion active parameters per token, supporting efficient private, on-premises, and sovereign AI deployments.
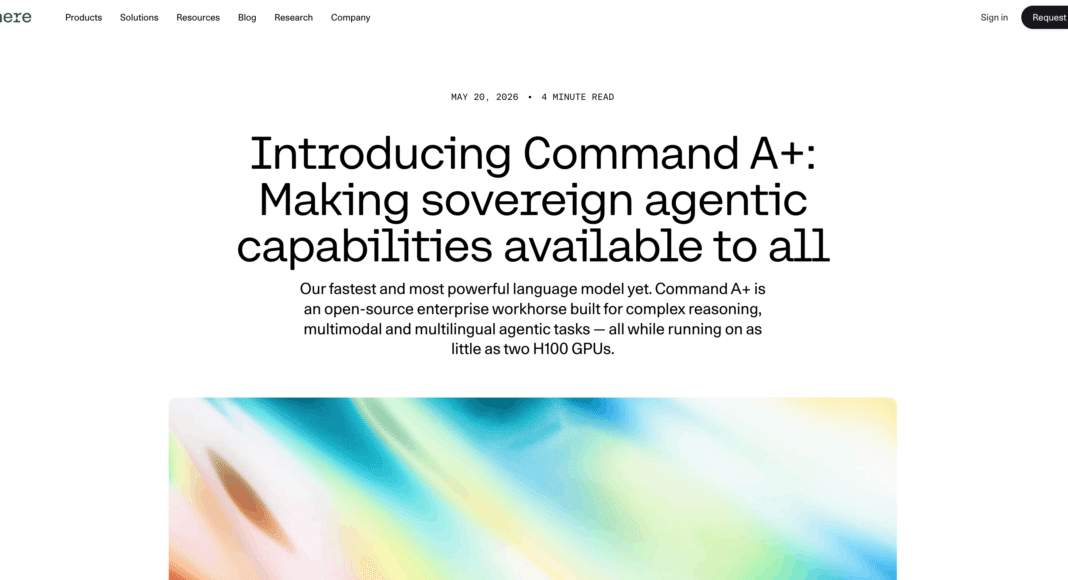
Cohere Command A+ is an enterprise-focused artificial intelligence model designed for organizations building advanced AI agents, retrieval-augmented generation systems, multimodal applications, multilingual tools, and private AI infrastructure. Released in 2026, Command A+ represents a major evolution of Cohere’s Command model family by combining reasoning, vision, tool use, structured outputs, citations, and enterprise-grade language capabilities within a single open-weight model.
At its core, Cohere Command A+ uses a 218-billion-parameter Sparse Mixture-of-Experts architecture, while activating approximately 25 billion parameters for each token. Instead of processing every request through the entire model, its routing system selects specialized experts to handle individual tokens. This approach gives Command A+ substantial overall model capacity while reducing the computational workload required during inference.
Command A+ is particularly notable for enterprise AI agents and complex business workflows. It supports a 128,000-token context window and up to 64,000 output tokens, allowing the model to work with lengthy documents, retrieved enterprise knowledge, multi-step tasks, tool calls, images, and extended agent interactions. Its multilingual capabilities also make it suitable for international organizations operating across different markets and languages.
Another important feature is deployment flexibility. Command A+ is released under the permissive Apache 2.0 license and offers downloadable weights, enabling businesses to run the model on private clouds, virtual private clouds, on-premises servers, or isolated infrastructure. Its W4A4 quantized version further reduces hardware requirements, making self-hosted deployment more practical for enterprises seeking greater control over sensitive information, data residency, security, and AI infrastructure.
Command A+ also fits into Cohere’s wider enterprise AI ecosystem. Embed models can retrieve semantically relevant information, Rerank models can prioritize the strongest evidence, and Command A+ can then reason over that context to generate grounded responses with citations. This architecture is particularly useful for enterprise search, knowledge assistants, document intelligence, customer support, research, data analysis, and other RAG applications.
Understanding what Cohere Command A+ is and how it works is therefore important for businesses evaluating the next generation of enterprise AI models. This guide explores the Command A+ architecture, Sparse Mixture-of-Experts design, reasoning and multimodal capabilities, performance benchmarks, quantization, self-hosting options, enterprise integrations, pricing considerations, and practical use cases to determine where the model fits within modern AI infrastructure.
Before we venture further into this article, we would like to share who we are and what we do.
About 9cv9
9cv9 is a business tech startup based in Singapore and Asia, with a strong presence all over the world.
With over ten years of startup and business experience, and being highly involved in connecting with thousands of companies and startups, the 9cv9 team has listed some of the top and best companies/tools in this review.
If you like to get your company listed in our top B2B software reviews, check out our world-class 9cv9 Media and PR service and pricing plans here.
What is Cohere: Command A+ Model, How It Works & Its Use Cases
- What Is Cohere Command A+?
- Technical Architecture and Inference Mechanics
- Quantitative Performance Benchmarks and Empirical Evaluation
- Enterprise Ecosystem Integration: Coding Agents, Translation, Embeddings, and Reranking
- Enterprise Deployment, Sovereign Infrastructure, and Self-Hosting
- Financial Analysis, Pricing Models, and Total Cost of Ownership
- Industry Adoption, Developer Feedback, and Strategic Trade-offs
1. What Is Cohere Command A+?
Cohere Command A+ is an open-weight enterprise artificial intelligence model released in May 2026. It is designed to combine reasoning, agentic workflows, multilingual processing, vision understanding, retrieval-based applications, translation, and tool use within a single foundation model.
Rather than requiring organizations to deploy separate models for reasoning, document vision, translation, and enterprise agents, Command A+ consolidates capabilities previously represented across the Command A product family into one architecture. Cohere positions the model particularly strongly for enterprises, governments, regulated industries, and organizations that need greater control over where AI models and sensitive information are hosted.
The model is significant because it combines a very large 218-billion-parameter architecture with sparse computation. Only approximately 25 billion parameters are active for each token, helping reduce the computational burden associated with operating a model of this overall size.
Command A+ at a Glance
| Specification | Cohere Command A+ |
|---|---|
| Developer | Cohere and Cohere Labs |
| Release Date | May 20, 2026 |
| Model ID | command-a-plus-05-2026 |
| Architecture | Decoder-only Sparse Mixture-of-Experts |
| Total Parameters | 218 billion |
| Active Parameters | 25 billion |
| Context Window | 128,000 tokens |
| Maximum Output | 64,000 tokens |
| Input Modalities | Text and images |
| Output Modality | Text |
| Supported Languages | 48 |
| License | Apache 2.0 |
| Primary Focus | Enterprise AI and sovereign AI |
| Major Capabilities | Reasoning, agents, vision, translation, tool use, RAG |
| Private Deployment | Supported |
| Air-Gapped Deployment | Supported |
How Cohere Command A+ Works
At the core of Command A+ is a Sparse Mixture-of-Experts, or MoE, architecture. Instead of processing every input through the model’s entire 218 billion parameters, the architecture selectively activates specialized groups of parameters according to the token being processed.
Command A+ contains 128 routed experts. For each token, eight of these experts are activated, alongside a shared expert that processes all tokens. A routing mechanism determines which experts should handle each token. This allows the model to maintain a very large overall capacity without requiring all parameters to participate in every inference operation.
| Processing Stage | What Happens |
|---|---|
| User Input | Command A+ receives text, images, documents, or instructions |
| Token Processing | Input is converted into tokens for model processing |
| Expert Routing | The MoE router determines which experts should process each token |
| Sparse Activation | Eight of 128 routed experts are activated for each token |
| Shared Processing | A shared expert participates across tokens |
| Reasoning | Relevant information is processed across the transformer layers |
| Tool Interaction | External tools can be called when an agentic workflow requires them |
| Response Generation | The model produces text, structured data, citations, or actions |
Why the Mixture-of-Experts Architecture Matters
Large dense AI models normally activate most or all of their parameters during inference. Increasing parameter counts can therefore substantially increase GPU requirements and operating costs.
Command A+ approaches this problem differently. Its 218 billion parameters provide a large pool of model capacity, while sparse routing keeps active computation at approximately 25 billion parameters per token.
This does not mean Command A+ has the same memory footprint as an ordinary 25-billion-parameter dense model, because the complete model weights still need to be stored and made accessible. However, sparse activation can significantly improve inference efficiency compared with executing all 218 billion parameters for every token.
| Architecture Characteristic | Enterprise Benefit |
|---|---|
| 218B total parameters | Large overall model capacity |
| 25B active parameters | Lower active computation per token |
| 128 routed experts | Specialized processing capacity |
| 8 routed experts per token | Sparse inference |
| Shared expert | Common processing across tokens |
| Token-choice routing | Dynamic expert selection |
Command A+ Hardware and Quantization
One of Command A+’s most important characteristics is its relatively flexible deployment footprint.
Cohere provides BF16, FP8, and W4A4 versions of the model. The W4A4 configuration substantially reduces hardware requirements and can operate on as little as one NVIDIA B200 or two NVIDIA H100 GPUs according to Cohere’s published deployment specifications.
| Quantization | Precision | Example Minimum Blackwell Deployment | Example Minimum Hopper Deployment |
|---|---|---|---|
| BF16 | 16-bit | 4 B200 GPUs | 8 H100 GPUs |
| FP8 | 8-bit | 2 B200 GPUs | 4 H100 GPUs |
| W4A4 | 4-bit | 1 B200 GPU | 2 H100 GPUs |
This range gives enterprises greater flexibility when balancing model quality, infrastructure availability, throughput, latency, and deployment costs.
Multimodal Document Understanding
Command A+ accepts both text and images as input while producing text as output. This allows organizations to process information that is difficult to represent as plain text alone.
Typical enterprise documents may contain tables, screenshots, scanned forms, charts, diagrams, invoices, reports, or mixed visual and textual information. Vision capabilities allow these materials to become part of an AI workflow without necessarily requiring an entirely separate vision-language model.
Potential applications include invoice interpretation, document classification, financial-report analysis, chart interpretation, form processing, contract review, and knowledge extraction from scanned corporate documents.
Enterprise Reasoning and AI Agents
Command A+ places substantial emphasis on agentic AI.
An AI agent differs from a conventional chatbot because it can perform multi-stage workflows rather than simply generate an answer. A model may determine what information it needs, invoke external tools, analyze returned information, make intermediate decisions, and continue until the requested task has been completed.
Command A+ supports tool use and structured outputs, making it suitable for systems that interact with enterprise APIs, databases, search systems, business applications, and internal knowledge repositories. Cohere describes it as its strongest Command-family model for agentic applications.
| Agent Capability | Example Enterprise Application |
|---|---|
| Reasoning | Investigating a complex business question |
| Tool Calling | Querying an internal database |
| Structured Outputs | Returning standardized JSON-style records |
| Document Understanding | Reading reports, forms, and screenshots |
| Retrieval | Searching corporate knowledge bases |
| Multi-Step Execution | Completing workflows across several systems |
| Multilingual Processing | Supporting international operations |
Retrieval-Augmented Generation and Enterprise Search
Command A+ can also serve as the reasoning layer within retrieval-augmented generation systems.
In a RAG architecture, an enterprise first retrieves relevant information from an approved knowledge source. The retrieved information is then supplied to the language model, which generates an answer based on that context.
This approach is particularly useful for organizations whose important information exists inside private repositories rather than in an AI model’s original training data.
Potential sources include company policies, technical documentation, product catalogs, research repositories, contracts, CRM records, support documentation, and internal databases.
| RAG Component | Role |
|---|---|
| User Query | Defines the information request |
| Retrieval System | Searches relevant enterprise information |
| Knowledge Repository | Stores trusted organizational data |
| Command A+ | Interprets and reasons over retrieved context |
| Citation Layer | Connects responses with supporting material |
| Application | Presents the final answer or triggers an action |
Multilingual Enterprise AI
Command A+ supports 48 languages, including all official European Union languages. This represents a substantial expansion over earlier models in the Command family.
Multilingual capability can be especially valuable for multinational organizations that need one AI system to process documents, customer inquiries, internal knowledge, and business workflows across multiple regions.
Instead of maintaining independent language-specific systems, organizations can potentially consolidate more workloads around a common model and infrastructure layer.
Private and Sovereign AI Deployment
Another major Command A+ use case is sovereign AI.
Because the model weights are available under the Apache 2.0 license, organizations can deploy Command A+ within infrastructure they control. Cohere specifically identifies private clouds, virtual private clouds, on-premises infrastructure, and fully air-gapped environments as potential deployment configurations.
This can be particularly important where confidential information cannot be routinely transmitted to external AI APIs.
| Deployment Model | Typical Requirement |
|---|---|
| Hosted AI | Fast implementation and managed infrastructure |
| Private Cloud | Greater organizational control |
| Virtual Private Cloud | Isolated enterprise deployment |
| On-Premises | Internal infrastructure and data governance |
| Air-Gapped Environment | Highly sensitive or isolated workloads |
| Sovereign Infrastructure | National or regional data-control requirements |
The Apache 2.0 License
Command A+ represents an important change from some earlier Command-family open-weight releases.
The model is distributed under Apache 2.0, providing considerably more permissive possibilities for commercial deployment, modification, integration, and private operation than non-commercial licenses associated with certain previous releases.
For enterprises, this can reduce dependence on a single hosted API provider and create greater flexibility around infrastructure, customization, deployment location, and application architecture.
Key Cohere Command A+ Use Cases
Command A+ is primarily positioned for sophisticated enterprise workloads rather than simple consumer chatbot applications.
| Use Case | How Command A+ Can Be Applied |
|---|---|
| Enterprise AI Agents | Execute multi-step business workflows |
| RAG Systems | Answer questions using private company knowledge |
| Document Intelligence | Analyze reports, forms, invoices, and contracts |
| Visual Document Processing | Interpret screenshots, charts, and scanned material |
| Enterprise Search | Generate answers from internal information |
| Customer Support | Power contextual multilingual support assistants |
| Financial Services | Analyze controlled financial and operational information |
| Government AI | Operate models within sovereign infrastructure |
| Legal Workflows | Review and summarize large document collections |
| Research | Analyze extensive collections of technical information |
| Translation | Support multilingual enterprise communication |
| Data Extraction | Convert unstructured information into structured outputs |
| Software Agents | Combine reasoning with tools and APIs |
| Knowledge Assistants | Build internal employee copilots |
Command A+ Compared With a Traditional Enterprise LLM
| Capability | Traditional Dense LLM | Command A+ |
|---|---|---|
| Architecture | Dense transformer | Sparse MoE transformer |
| Parameter Activation | Large portion of model | 25B active parameters |
| Vision Input | Model dependent | Supported |
| Reasoning | Model dependent | Integrated |
| Tool Use | Model dependent | Supported |
| RAG | Often supported | Enterprise-focused |
| Multilingual Coverage | Varies | 48 languages |
| Open Weights | Often unavailable | Available |
| License | Varies | Apache 2.0 |
| Private Deployment | Provider dependent | Core deployment option |
| Air-Gapped Operation | Often difficult | Supported deployment scenario |
Command A+ and the Shift Toward Sovereign Enterprise AI
Command A+ also fits within Cohere’s broader emphasis on sovereign enterprise AI. In 2026, Cohere and German AI company Aleph Alpha announced plans to combine their businesses, with the resulting organization operating under the Cohere name and maintaining major operations in Canada and Germany. The transaction has been presented as part of a strategy to provide enterprise and public-sector organizations with greater technological and infrastructure sovereignty.
Command A+ should not, however, be described as a model created by the completed Cohere-Aleph Alpha merger. The model was released in May 2026, while the companies’ combination remained subject to regulatory approvals later in 2026.
Why Cohere Command A+ Matters
Command A+ represents Cohere’s attempt to bring several previously separate enterprise AI capabilities into one deployable foundation model.
Its combination of a 218-billion-parameter Sparse Mixture-of-Experts architecture, 25 billion active parameters, multimodal input, 128K context window, agentic tool use, reasoning, multilingual support, open weights, and Apache 2.0 licensing makes it particularly relevant for organizations seeking capable AI without surrendering control of their infrastructure or sensitive information.
For businesses, the central value proposition is therefore not simply model size. Command A+ is designed around consolidation and operational control: one model can support enterprise search, RAG, document intelligence, multilingual applications, AI agents, reasoning workflows, and private deployments while remaining capable of operating inside infrastructure controlled by the organization.
2. Technical Architecture and Inference Mechanics
Cohere Command A+ uses a Sparse Mixture-of-Experts architecture designed to combine very large model capacity with a more practical enterprise inference footprint. The model contains 218 billion total parameters, but only about 25 billion parameters are active for each token.
This distinction is central to how Command A+ operates. Instead of sending every token through the complete parameter set, the model dynamically routes tokens through a subset of specialized expert networks. The result is an architecture intended to provide the capacity of a very large foundation model while reducing the computation required during each inference step.
Sparse Mixture-of-Experts Routing
Command A+ contains 128 routed experts together with one shared expert. For each token, eight of the 128 routed experts are selected, while the shared expert processes every token.
Importantly, Command A+ does not use a conventional softmax-based router as described in the original text. Cohere’s technical documentation states that the model uses a token-choice router with normalized sigmoid activation over the top-k expert logits. Additive-bias load balancing is used to encourage a more even distribution of tokens among experts. The MoE system is also trained using a fully dropless configuration.
| Architecture Component | Command A+ Configuration | Purpose |
|---|---|---|
| Total Parameters | 218 billion | Provides overall model capacity |
| Active Parameters | Approximately 25 billion | Reduces per-token computation |
| Routed Experts | 128 | Provides specialized processing pathways |
| Active Routed Experts | 8 per token | Limits computation to relevant experts |
| Shared Expert | 1 | Processes every token |
| Routing Strategy | Token-choice routing | Dynamically selects experts |
| Router Activation | Normalized sigmoid over top-k logits | Scores selected expert pathways |
| Load Balancing | Additive-bias based | Encourages balanced expert utilization |
| MoE Training | Fully dropless | Avoids deliberately dropping routed tokens |
Conceptually, each token passes through the shared processing pathway while simultaneously being assigned to eight routed experts. Their outputs are then combined before the representation continues through the transformer.
This sparse activation is particularly important for inference. Command A+ can maintain 218 billion parameters of overall capacity without requiring all 218 billion parameters to participate in every token-generation step.
Why Sparse Routing Matters for Enterprise AI
Sparse MoE architectures address one of the fundamental problems associated with increasingly large AI models: computational efficiency.
A conventional dense model generally uses its entire parameter set for every token. Command A+ instead separates total capacity from active computation.
| Model Property | Dense Architecture | Command A+ Sparse MoE |
|---|---|---|
| Parameter Utilization | Most parameters participate | Selected experts participate |
| Total Capacity | Closely tied to active compute | Can greatly exceed active compute |
| Expert Specialization | No explicit expert routing | 128 routed experts |
| Per-Token Processing | Dense | Sparse |
| Scaling Strategy | Increase dense parameters | Increase expert capacity |
| Active Parameters | Near total model size | Approximately 25B of 218B |
This does not mean Command A+ has the memory requirements of an ordinary 25-billion-parameter dense model. The complete expert weights still need to be stored and made available to the inference system. Sparse routing primarily reduces active computation rather than making the remaining parameters disappear from memory.
Hybrid Attention Architecture
Command A+ combines two attention mechanisms instead of applying global self-attention uniformly throughout the model.
Its transformer layers interleave sliding-window attention and global attention at a 3:1 ratio. Three sliding-window attention layers are followed by a global attention layer, continuing this pattern through the architecture.
| Attention Mechanism | Role |
|---|---|
| Sliding-Window Attention | Efficiently processes localized token relationships |
| Global Attention | Captures dependencies across the broader sequence |
| Interleaving Ratio | 3 sliding-window layers to 1 global layer |
| Context Length | 128K |
| Maximum Output Length | 64K |
Sliding-window attention limits how far individual tokens need to attend within those layers, reducing the computational burden associated with long sequences. Periodic global-attention layers then allow information to propagate across the broader context.
This architecture is particularly relevant for enterprise workloads involving lengthy reports, knowledge retrieval, agent histories, code repositories, regulatory documents, and multi-step workflows.
Positional Encoding in Command A+
One important correction is required to the claim that Command A+ completely removes explicit positional embeddings.
Cohere’s published model architecture states that the sliding-window attention layers use Rotary Positional Embeddings, while the global-attention layers operate without positional embeddings.
| Attention Layer | Positional Mechanism |
|---|---|
| Sliding-Window Attention | Rotary Positional Embeddings |
| Global Attention | No positional embeddings |
| Overall Design | Hybrid positional architecture |
Command A+ therefore uses a hybrid approach rather than eliminating RoPE across the entire model.
128K Context and 64K Output
Command A+ supports a context length of 128K and output generation of up to 64K tokens.
The combination provides substantial room for both input material and generated responses. The unusually large output allowance is particularly relevant for agentic and reasoning-heavy workloads where the model may need to generate extensive intermediate or final results.
| Workload | Benefit of Long Context or Output |
|---|---|
| Document Analysis | Processes large collections of source material |
| Enterprise RAG | Accommodates retrieved evidence and instructions |
| Coding Agents | Handles code context and lengthy generated changes |
| Research Agents | Supports multi-stage analytical workflows |
| Tool-Based Agents | Maintains longer interaction histories |
| Report Generation | Produces extensive structured outputs |
| Document Extraction | Processes information from lengthy documents |
However, the assertion that Cohere specifically reduced Command A+’s input window from Command A’s 256K context to reallocate KV-cache memory toward the 64K output budget should be treated as an architectural interpretation unless directly substantiated by Cohere. The published technical specifications establish the 128K context and 64K output limits, but they do not by themselves prove that this was the precise engineering rationale.
Multilingual Architecture
Command A+ was trained across 48 languages, substantially broadening its applicability to multinational enterprises. Its supported languages include major European and global business languages such as English, Arabic, Chinese, Japanese, Korean, Hindi, Vietnamese, German, French, Spanish, Portuguese, and numerous others.
This multilingual coverage is especially relevant for organizations seeking to consolidate regional AI systems around one foundation model.
| Multilingual Application | Enterprise Use |
|---|---|
| Customer Support | Multilingual service automation |
| Knowledge Search | Search across international repositories |
| Document Processing | Analyze documents from multiple markets |
| Enterprise Agents | Operate across regional business systems |
| Translation Workflows | Transform business information between languages |
| Global RAG | Retrieve and interpret multilingual knowledge |
Claims of exact tokenizer improvements such as 20% fewer Arabic tokens, 18% fewer Japanese tokens, or 16% fewer Korean tokens should not be presented as established Command A+ specifications without a primary benchmark supporting those particular figures.
W4A4 and NVFP4 Quantization
One of the most technically significant aspects of Command A+ is Cohere’s approach to low-precision inference.
The W4A4 release applies NVFP4 quantization to the model’s Mixture-of-Experts pathways, reducing both expert weights and activations to four-bit precision. Cohere does not simply quantize the entire architecture uniformly.
Instead, quantization is selectively concentrated on the MoE experts, which represent most of the model’s parameters.
| Model Component | Precision Strategy |
|---|---|
| MoE Expert Weights | 4-bit NVFP4 |
| MoE Expert Activations | 4-bit NVFP4 |
| Q/K/V/O Projections | Full precision |
| Attention Computation | Full precision |
| KV Cache | Full precision |
| Quantization Strategy | Selective rather than model-wide |
This distinction is important for long-context enterprise workloads. Attention operations and the KV cache can be particularly sensitive to aggressive quantization, so preserving higher precision in those pathways helps protect model quality while most of the parameter-heavy expert computation benefits from four-bit execution.
Quantization-Aware Distillation
Cohere also uses Quantization-Aware Distillation, or QAD, during post-training.
Rather than simply converting a completed high-precision model into four-bit form, the quantized student model is trained to reproduce the output distribution of its full-precision teacher.
Fake quantization operators are introduced during the forward pass, while straight-through estimators are used during backward propagation. This allows the model to adapt to quantization effects during training rather than encountering them only after training has finished.
The objective is to preserve as much of the original model’s quality as possible while substantially reducing the hardware footprint of inference.
Command A+ Quantization Options
Cohere provides Command A+ in BF16, FP8, and W4A4 configurations. The official model documentation reports negligible benchmark-quality differences among the three configurations and recommends W4A4 for most applications because of its smaller hardware footprint and stronger speed and latency characteristics.
| Quantization | Precision | Minimum Blackwell Configuration | Minimum Hopper Configuration |
|---|---|---|---|
| BF16 | 16-bit | 4 x NVIDIA B200 | 8 x NVIDIA H100 |
| FP8 | 8-bit | 2 x NVIDIA B200 | 4 x NVIDIA H100 |
| W4A4 | 4-bit | 1 x NVIDIA B200 | 2 x NVIDIA H100 |
The progression illustrates the operational advantage of quantization particularly clearly. Moving from BF16 to W4A4 reduces the example minimum Blackwell configuration from four B200 GPUs to one B200, while the corresponding Hopper configuration falls from eight H100 GPUs to two.
Why W4A4 Changes the Deployment Economics
Quantization is particularly consequential for organizations seeking to self-host large models.
Without aggressive quantization, a 218-billion-parameter model normally requires substantial accelerator infrastructure. By concentrating four-bit quantization on the parameter-heavy MoE experts while maintaining higher precision for sensitive attention operations, Command A+ can operate on considerably smaller hardware configurations.
| Enterprise Consideration | W4A4 Impact |
|---|---|
| GPU Count | Significantly reduced |
| Infrastructure Cost | Potentially lower |
| Expert Computation | Accelerated through low precision |
| Deployment Density | More workloads per infrastructure footprint |
| Private AI | More practical |
| On-Premises Deployment | Lower hardware barrier |
| Sovereign AI | Easier deployment within controlled infrastructure |
This matters for enterprises because the economics of private AI depend not only on model quality but also on the number and class of accelerators required to operate the model reliably.
Command A+ Inference Pipeline
The complete Command A+ inference architecture can be understood as a sequence of complementary optimization layers.
| Inference Stage | Command A+ Mechanism | Primary Benefit |
|---|---|---|
| Input Processing | Multilingual tokenization | Efficient sequence representation |
| Local Context Modeling | Sliding-window attention | Lower long-context computation |
| Long-Range Modeling | Periodic global attention | Maintains broader dependencies |
| Expert Selection | Token-choice router | Dynamic specialization |
| Expert Computation | Top-8 of 128 experts | Sparse execution |
| Universal Processing | Shared expert | Common token processing |
| Quantized Execution | NVFP4 W4A4 experts | Lower inference footprint |
| Attention Processing | Higher precision | Protects sensitive calculations |
| KV Cache | Higher precision | Supports reliable long-context inference |
| Output Generation | Up to 64K tokens | Supports extensive agentic workflows |
Technical Significance of the Architecture
Command A+ combines several optimization strategies rather than relying on a single technique to improve inference efficiency.
Sparse expert routing limits how much of the 218-billion-parameter network participates in processing each token. Hybrid attention reduces the need for global attention at every transformer layer. Selective NVFP4 quantization reduces the memory and computation associated with the parameter-heavy MoE experts. Quantization-Aware Distillation is then used to mitigate the quality degradation normally associated with aggressive four-bit inference.
Together, these design decisions make Command A+ particularly relevant to enterprises seeking large-model reasoning and agent capabilities without relying exclusively on very large GPU clusters. The architecture is therefore best understood not simply as a 218-billion-parameter model, but as a system engineered to make that scale more practical for private, sovereign, and enterprise AI deployment.
3. Quantitative Performance Benchmarks and Empirical Evaluation
Cohere Command A+ shows its largest performance improvements in agentic execution, mathematical reasoning, data analysis, multimodal understanding, and long-horizon tool-based workflows.
However, benchmark results require careful interpretation. Cohere-reported evaluations, independent Artificial Analysis testing, and third-party benchmark aggregators do not always use identical prompts, inference settings, scoring methodologies, or model configurations. As a result, figures should be compared within the same evaluation framework rather than treated as universally interchangeable.
Independent testing also shows that Command A+ is not a frontier leader across every category. Its strongest positioning is in enterprise-oriented agentic workloads, efficient inference, multilingual processing, grounding, and reliable task execution rather than maximum performance on every scientific or coding benchmark.
Command A+ Core Benchmark Performance
Command A+ records particularly substantial results on Tau2 Telecom, AIME 2025, data analysis, multimodal reasoning, and visual mathematics.
| Benchmark | Evaluated Capability | Command A+ Performance |
|---|---|---|
| Tau2 Telecom | Multi-turn telecom agent execution | 85.0% |
| AIME 2025 | Competition-level mathematical reasoning | 90.0% |
| Cohere Data Analysis | Tables, spreadsheets and analytical workflows | 45.0% |
| Terminal-Bench Hard | Autonomous terminal and coding tasks | 25.0% |
| MMMU | Broad multimodal reasoning | 75.1% |
| MMMU-Pro | Difficult multimodal reasoning | 63.0% |
| MathVista | Visual mathematical reasoning | 80.6% |
| CharXiv Reasoning | Scientific chart reasoning | 52.7% |
| SciCode | Scientific coding | Approximately 38% |
| IFBench | Instruction following | Approximately 74% |
These published results indicate that Command A+’s strongest improvements are concentrated around practical reasoning and agentic execution rather than simply conventional knowledge benchmarks.
Agentic Performance
Agentic workloads are particularly important to understanding Command A+. These evaluations test whether a model can maintain state, select actions, interact with tools, respond to changing conditions, and successfully complete an objective over multiple steps.
Tau2 Telecom is a notable example. Command A+ reaches an 85% success rate in the telecom evaluation. Independent Artificial Analysis results across the broader Tau2 benchmark report approximately 80.7%.
| Agentic Capability | Why It Matters |
|---|---|
| Multi-Turn Reasoning | Maintains objectives across extended interactions |
| Tool Selection | Determines when external systems are required |
| Tool Execution | Generates appropriate tool requests |
| State Tracking | Remembers previous actions and returned information |
| Error Recovery | Adjusts plans when an action fails |
| Long-Horizon Planning | Breaks complex objectives into multiple operations |
| Grounding | Connects conclusions to retrieved information |
These characteristics make Command A+ more relevant to enterprise agents that must actually complete processes rather than simply answer questions.
Mathematical Reasoning
Command A+ achieves 90% on the AIME 2025 evaluation in Cohere-associated benchmark reporting, making mathematics one of its stronger reasoning categories.
This is significant because mathematical benchmarks test several capabilities simultaneously: decomposition, intermediate reasoning, symbolic manipulation, numerical accuracy, and maintaining consistency across multiple reasoning stages.
| Mathematical Evaluation | Command A+ |
|---|---|
| AIME 2025 | 90.0% |
| MT-AIME 2025 | 86.0% |
| MathVista | 80.6% |
MathVista additionally introduces visual information, meaning the model must combine image interpretation with mathematical reasoning rather than solving a purely textual problem.
Multimodal and Visual Reasoning
Command A+ incorporates image understanding directly into the broader Command architecture.
The model records 75.1% on MMMU and 80.6% on MathVista, while its CharXiv Reasoning result reaches 52.7%. These evaluations cover combinations of image interpretation, charts, diagrams, scientific figures, mathematics, and domain-specific reasoning.
| Benchmark | Command A+ | Primary Capability |
|---|---|---|
| MMMU | 75.1% | Multidisciplinary multimodal reasoning |
| MMMU-Pro | 63.0% | Difficult multimodal understanding |
| MathVista | 80.6% | Visual mathematical reasoning |
| CharXiv Reasoning | 52.7% | Scientific chart reasoning |
For enterprises, these capabilities can translate into applications involving financial charts, scanned documents, reports, presentation slides, diagrams, forms, screenshots, and other mixed-media information.
Coding and Terminal Execution
Command A+ demonstrates meaningful agentic coding capability, but coding is not its strongest benchmark category.
Artificial Analysis reports approximately 25% on Terminal-Bench Hard and roughly 38% to 39% on SciCode. The independent assessment specifically identifies difficult scientific reasoning and coding as areas where Command A+ trails stronger peers.
| Coding Evaluation | Approximate Command A+ Result |
|---|---|
| Terminal-Bench Hard | 25% |
| Terminal-Bench v2.1 | 22.8% |
| SciCode | 38–39% |
| Artificial Analysis Coding Index | 27.8 |
This distinction is important for buyers. Command A+ may be attractive as an enterprise workflow agent capable of interacting with software and tools, but organizations primarily seeking maximum autonomous software-engineering performance should compare it against dedicated coding-oriented models.
Artificial Analysis Independent Evaluation
Command A+’s Artificial Analysis scores require additional context because the Intelligence Index methodology has evolved.
At launch in May 2026, Artificial Analysis reported a score of 37 under the Intelligence Index methodology then in use. More recent model-comparison pages using updated evaluations show materially different index values, including approximately 13–14. Therefore, the launch figure of 37 should not be directly compared with scores produced under later benchmark versions.
The launch evaluation also reported approximately 281 output tokens per second through Cohere’s API, demonstrating that inference speed is one of Command A+’s notable characteristics.
| Independent Metric | Observed Result |
|---|---|
| Launch Intelligence Index | 37 under launch methodology |
| AA-Omniscience Non-Hallucination | 86% |
| GPQA Diamond | Approximately 76% |
| Humanity’s Last Exam | Approximately 11–12% |
| Terminal-Bench Hard | Approximately 25% |
| SciCode | Approximately 38–39% |
| Launch API Output Speed | Approximately 281 tokens/sec |
One particularly interesting result is the 86% AA-Omniscience Non-Hallucination score. At launch, Artificial Analysis ranked Command A+ first on this measure. This metric evaluates whether the model avoids fabricating answers when it lacks sufficient knowledge, an especially relevant property for enterprise AI systems.
Enterprise RAG and Grounded Generation
Retrieval-augmented generation is one of the areas where Cohere’s Command family has historically been differentiated.
Command A+ accepts external documents through Cohere’s RAG workflow and can generate responses grounded in those documents. The system also provides fine-grained citations connecting specific portions of generated text to the source documents used to support them.
| RAG Capability | Command A+ Support |
|---|---|
| External Document Grounding | Supported |
| Fine-Grained Citations | Supported |
| Citation-to-Document Mapping | Supported |
| Text-Span Attribution | Supported |
| Streaming Citations | Supported |
| Accurate Citation Mode | Supported |
| Fast Citation Mode | Supported |
| Private Deployment | Supported |
This architecture is particularly useful for internal knowledge assistants, compliance systems, research applications, enterprise search, customer-support platforms, and document intelligence systems.
Fine-Grained Citation Grounding
Command-family citation functionality goes beyond simply appending a list of references to the end of an answer.
The API can identify the exact generated text span supported by a document and associate that span with its corresponding source. Citation objects contain start and end positions, the cited generated text, and information identifying the supporting document.
Conceptually, the process works as follows:
| Stage | Citation Grounding Process |
|---|---|
| Document Retrieval | Relevant documents are supplied to Command A+ |
| Grounded Generation | Model generates an answer using supplied context |
| Evidence Attribution | Supported answer spans are associated with sources |
| Citation Generation | Citation objects identify supporting documents |
| Application Rendering | Interface presents citations to the user |
| Human Verification | User can inspect the original evidence |
Cohere also provides two citation modes. Accurate mode prioritizes precise alignment between the completed response and its sources, while fast mode emits citations during streaming for applications where immediate feedback is more important.
Are Citations Native to Command A+?
It is reasonable to describe citation generation as an out-of-the-box capability of the Command family. Cohere explicitly documents fine-grained citation generation without requiring developers to build their own citation prompt-engineering or fine-tuning system.
However, describing this as proof that Command A+ can never create an incorrect source attribution would overstate the capability.
Cohere itself warns that RAG does not guarantee factual accuracy and does not completely eliminate hallucinations. Retrieved documents can also contain inaccurate, outdated, incomplete, or biased information. Citations improve traceability rather than guaranteeing truth.
Command A+ Versus Llama 3.1 70B for Enterprise RAG
The supplied figures claiming a 6% versus 14% RAG hallucination rate, 91% versus 78% multi-step tool accuracy, and approximately 12 versus 22 tokens per second on a 48 GB GPU could not be substantiated from authoritative Cohere documentation or the independent benchmark sources reviewed.
They should therefore not be presented as established benchmark results.
A more defensible comparison focuses on architectural differences.
| Enterprise RAG Factor | Command A+ | Llama 3.1 70B |
|---|---|---|
| Architecture | 218B Sparse MoE, approximately 25B active | 70B dense model |
| Enterprise RAG Orientation | Core design focus | General-purpose foundation model |
| Fine-Grained Citations | Built into Command RAG workflow | Usually application implemented |
| Tool Use | Native model capability | Supported through integrations |
| Image Input | Supported | Depends on Llama variant |
| Private Deployment | Supported | Supported |
| Open Weights | Yes | Yes |
| Enterprise Grounding | Strong product emphasis | Application dependent |
The distinction matters because enterprise RAG quality depends on much more than the underlying language model. Retrieval quality, reranking, chunking strategy, document freshness, prompts, context construction, and evaluation methodology can materially change hallucination and citation accuracy.
Benchmark Interpretation for Enterprise Buyers
Command A+’s benchmark profile suggests that it should not be evaluated solely as a general-purpose chatbot competing for the highest aggregate intelligence score.
Its strengths are more concentrated.
| Evaluation Area | Command A+ Positioning |
|---|---|
| Agentic Workflows | Strong |
| Mathematical Reasoning | Strong |
| Multimodal Understanding | Strong |
| Enterprise Data Analysis | Improved substantially |
| RAG and Grounding | Core specialization |
| Citation Generation | Major enterprise capability |
| Multilingual Processing | Strong |
| Coding | Competitive but not category-leading |
| Difficult Scientific Reasoning | Relative weakness |
| Hallucination Avoidance | Strong independent result |
| Inference Speed | Strong |
| Private Enterprise Deployment | Major differentiator |
What the Benchmarks Reveal About Command A+
The empirical results reinforce the broader design philosophy behind Cohere Command A+. It is not engineered solely to maximize academic benchmark rankings. Instead, its architecture emphasizes the combination of reasoning, agentic execution, multimodal understanding, retrieval, citations, multilingual processing, high-throughput inference, and private deployment.
Its 85% Tau2 Telecom result and 90% AIME 2025 result demonstrate substantial task-specific capability, while its 25% Terminal-Bench Hard performance illustrates that meaningful limitations remain in difficult autonomous coding environments. Independent testing also shows a particularly strong tendency to avoid answering when knowledge is insufficient, with an 86% non-hallucination result at launch.
For enterprise adoption, that combination may matter more than winning every general intelligence benchmark. Organizations deploying AI into operational systems need not only reasoning ability, but also predictable tool use, verifiable evidence, controllable infrastructure, efficient inference, and mechanisms for reducing unsupported answers.
4. Enterprise Ecosystem Integration: Coding Agents, Translation, Embeddings, and Reranking
Cohere Command A+ is designed to operate as part of a broader enterprise AI stack rather than as an isolated large language model. Cohere’s ecosystem separates specialized workloads across generative models, coding models, translation models, embeddings, reranking, document parsing, and retrieval components.
This modular architecture allows enterprises to use specialized models for individual stages of an AI workflow while reserving Command A+ for complex reasoning, generation, multimodal understanding, RAG, and agentic execution. Cohere’s documentation explicitly positions Embed and Rerank as complementary components for retrieval-augmented generation.
Cohere Enterprise AI Stack
| Cohere Component | Primary Function | Typical Enterprise Role |
|---|---|---|
| Command A+ | Reasoning and generation | Enterprise agents, RAG and complex workflows |
| North Mini Code | Agentic software engineering | Coding agents and terminal automation |
| North Small Translate | Machine translation | Multilingual enterprise content |
| Embed v4 | Multimodal embeddings | Initial semantic retrieval |
| Rerank v4 Pro | High-quality reranking | Precision-focused enterprise search |
| Rerank v4 Fast | Faster reranking | High-throughput retrieval |
| Cohere Parse | Document extraction | Preparing complex documents for AI systems |
Together, these components provide the building blocks for enterprise search and agent systems where documents are parsed, embedded, retrieved, reranked, interpreted, and ultimately transformed into grounded responses or actions.
North Mini Code for Agentic Software Engineering
For software-development workloads, Cohere introduced North Mini Code in June 2026 as the first model in its North family. It is specifically trained for agentic software engineering rather than functioning as a general-purpose assistant.
North Mini Code uses a sparse Mixture-of-Experts architecture containing 30 billion total parameters, with approximately 3 billion parameters active per token. It supports a 256K context window and as much as 64K of generated output, while its weights are released under Apache 2.0.
| North Mini Code Specification | Configuration |
|---|---|
| Model ID | north-mini-code-1-0 |
| Architecture | Sparse Mixture-of-Experts |
| Total Parameters | 30 billion |
| Active Parameters | 3 billion |
| Context Window | 256K |
| Maximum Output | 64K |
| Input | Text |
| Primary Workload | Agentic software engineering |
| License | Apache 2.0 |
| Local Deployment | Supported |
| Production Deployment | Cohere Model Vault |
Its comparatively small active parameter footprint makes North Mini Code particularly interesting for organizations seeking local coding agents without operating a very large inference cluster. Cohere specifically identifies repository-level modifications, terminal agents, local coding, code generation, and algorithmic reasoning among its intended workloads.
How North Mini Code Works
North Mini Code shares several architectural concepts with the larger Command A+ architecture.
It uses 128 experts, with eight activated for each token. Its attention architecture alternates sliding-window attention using RoPE with global attention without positional embeddings at a 3:1 ratio. The model was subsequently post-trained for agentic coding through supervised fine-tuning followed by reinforcement learning with verifiable rewards.
| Architectural Feature | North Mini Code |
|---|---|
| Routed Experts | 128 |
| Experts Activated per Token | 8 |
| Expert Activation | SwiGLU |
| Router | Sigmoid before top-k selection |
| Attention | Sliding-window plus global |
| Attention Ratio | 3:1 |
| Post-Training | SFT followed by RLVR |
| Agent Focus | Coding and terminal operation |
This specialization means an enterprise could use North Mini Code for repository manipulation and terminal execution while using Command A+ for broader business reasoning, document intelligence, research, or cross-application agents.
Local Coding and Deployment
The supplied claim that North Mini Code universally runs on any single 16 GB or 24 GB GPU requires qualification. The 3-billion-active-parameter design makes local inference significantly more practical, but actual VRAM requirements depend on weight precision, quantization, inference engine, KV-cache size, context length, and concurrency.
Similarly, the specific claim of 2.8 times higher throughput than Devstral Small 2 should only be used when accompanied by the exact Cohere benchmark configuration rather than treated as a universal hardware performance ratio.
Cohere does officially support the model through common inference environments, including Transformers, vLLM and SGLang, making it suitable for self-hosted developer tooling.
North Small Translate
Cohere expanded the North family again in September 2026 with North Small Translate, a purpose-built machine translation model supporting more than 50 languages and locale variants.
The model uses the same broad scale profile as Command A+: 218 billion total parameters and approximately 25 billion active parameters. However, it is optimized specifically for translation and has a 16K context window.
| North Small Translate Specification | Configuration |
|---|---|
| Model ID | north-small-translate-1-0 |
| Architecture | Sparse Mixture-of-Experts |
| Total Parameters | 218 billion |
| Active Parameters | 25 billion |
| Context Window | 16K |
| Maximum Output | 16K |
| Languages | More than 50 |
| W4A16 Hardware Guidance | 2 H100 or 1 B200 |
| FP8 Hardware Guidance | 4 H100 or 2 B200 |
| BF16 Hardware Guidance | 8 H100 or 4 B200 |
| Open-Weight License | CC BY-NC 4.0 |
One important correction is necessary: North Small Translate is not released under Apache 2.0. Its open weights are available for non-commercial use under Creative Commons Attribution-NonCommercial 4.0.
Is North Small Translate a Command A+ Fine-Tune?
North Small Translate has the same reported 218B-total and 25B-active scale as Command A+, but Cohere’s current public documentation describes it as a purpose-built MoE translation model.
Therefore, it would be premature to state definitively that it is a direct fine-tune of the released Command A+ checkpoint unless Cohere explicitly confirms that model lineage.
The detailed five-stage training pipeline in the supplied material — including coarse SFT, fine-grained SFT, DPO, GSPO-based online reinforcement learning and targeted DPO — and the stated WMT25 progression from 71.3% to 81.8% could not be verified from Cohere’s current public product documentation. These figures should consequently be treated as unverified rather than established specifications.
North Small Translate Enterprise Applications
The model is designed for workloads where translation must occur within controlled enterprise infrastructure.
| Translation Workload | Enterprise Application |
|---|---|
| Knowledge Management | Internal documentation and company wikis |
| Technical Translation | Manuals and operating procedures |
| Safety Documentation | Emergency and maintenance instructions |
| Employee Communications | HR policies and internal announcements |
| Customer Support | Multilingual customer communications |
| Product Localization | Regional product content |
| Private Translation | Sensitive documents within controlled infrastructure |
Cohere specifically highlights knowledge management, operational documentation, internal communication, localization, and customer support as target applications.
Embed v4 for Multimodal Retrieval
Before Command A+ can reason over enterprise knowledge, a retrieval system often needs to determine which information is relevant.
Cohere Embed v4 provides this initial semantic-retrieval layer.
Released in April 2025, Embed v4 can create embeddings from text and images and supports mixed-modality inputs. This makes it suitable for enterprise repositories containing conventional text alongside screenshots, diagrams, presentation slides, charts, and visually complex PDFs.
| Embed v4 Specification | Capability |
|---|---|
| Model | embed-v4.0 |
| Context Length | 128K |
| Modalities | Text and images |
| Mixed-Modality Input | Supported |
| 256-Dimensional Output | Supported |
| 512-Dimensional Output | Supported |
| 1,024-Dimensional Output | Supported |
| 1,536-Dimensional Output | Supported |
| Text-to-Text Retrieval | Supported |
| Text-to-Image Retrieval | Supported |
| Mixed-Modality Retrieval | Supported |
The flexible embedding dimensions are based on Matryoshka embeddings. Organizations can therefore choose among 256, 512, 1,024 and 1,536 dimensions depending on the trade-off required between storage, retrieval efficiency and representational richness.
Why Embeddings Matter for Command A+
An embedding model does not normally generate the final answer. Instead, it converts information into numerical representations that make semantic similarity searchable.
For example, an enterprise knowledge assistant could convert thousands of internal documents into Embed v4 vectors. When an employee asks a question, the system embeds the query and searches for semantically related material.
| Retrieval Stage | Function |
|---|---|
| Document Ingestion | Enterprise information enters the system |
| Embed v4 | Converts content into vector representations |
| Vector Search | Retrieves semantically related candidates |
| Rerank v4 | Reorders candidates by relevance |
| Command A+ | Reasons over the strongest evidence |
| Citation Layer | Connects generated claims with sources |
| Final Response | Returns a grounded enterprise answer |
Rerank v4 for Higher-Precision Retrieval
Vector search is efficient, but its first set of results is not necessarily ordered with sufficient precision for a high-quality RAG system.
Cohere Rerank provides a second relevance stage.
Rerank v4 is available in Pro and Fast variants. Both support more than 100 languages and have a 32,768-token context window. Unlike a basic vector-similarity calculation, reranking evaluates the relationship between the query and candidate document content before assigning relevance scores.
| Rerank Model | Primary Positioning |
|---|---|
| rerank-v4.0-pro | Maximum retrieval quality |
| rerank-v4.0-fast | Lower latency and higher throughput |
The two versions therefore allow enterprises to select the retrieval profile that best matches their workload rather than applying the same computational budget to every search.
Long-Document Reranking
One major improvement in Rerank v4 is its 32,768-token context window.
For comparison, Rerank 3.5 and Rerank 3.0 operate with 4,096-token contexts. Cohere estimates the Rerank v4 context as approximately 48 to 50 pages, meaning many ordinary enterprise documents can be evaluated substantially more holistically.
| Rerank Generation | Context Length |
|---|---|
| Rerank 3.0 | 4,096 tokens |
| Rerank 3.5 | 4,096 tokens |
| Rerank 4.0 Fast | 32,768 tokens |
| Rerank 4.0 Pro | 32,768 tokens |
When documents exceed the context capacity, Cohere automatically divides them into chunks and evaluates their relevance. This can simplify retrieval architectures involving lengthy policies, contracts, technical manuals and reports.
Structured Enterprise Data
Rerank v4 is not limited to plain prose.
It supports semi-structured information represented as JSON objects. Developers can specify which fields should participate in relevance ranking, allowing information such as titles, descriptions, authors, product fields or other metadata to influence retrieval.
This makes reranking useful beyond conventional document search.
| Data Source | Potential Reranking Application |
|---|---|
| Knowledge Articles | Enterprise search |
| Product Catalogs | Product discovery |
| Support Tickets | Case retrieval |
| CRM Records | Account intelligence |
| Policies | Compliance search |
| Technical Manuals | Engineering assistance |
| JSON Records | Structured enterprise retrieval |
| Research Documents | Evidence discovery |
How the Cohere RAG Stack Works
The combination of Embed, Rerank and Command creates a multi-stage retrieval architecture.
Embed v4 performs broad semantic retrieval efficiently. Rerank v4 then applies deeper relevance scoring to the candidate set. Only the strongest evidence needs to be passed into Command A+ for reasoning and response generation. Cohere’s own RAG documentation demonstrates this Embed-to-Rerank-to-generation pattern.
| Layer | Cohere Technology | Objective |
|---|---|---|
| Document Parsing | Cohere Parse | Extract usable information |
| Vectorization | Embed v4 | Represent semantic meaning |
| Candidate Search | Vector database | Find potentially relevant content |
| Precision Ranking | Rerank v4 | Select the strongest evidence |
| Reasoning | Command A+ | Interpret retrieved information |
| Generation | Command A+ | Produce the response |
| Grounding | Command citations | Attribute claims to evidence |
Why Cohere Uses Specialized Models
Cohere’s model portfolio illustrates an increasingly important enterprise AI architecture: different models can be optimized for different stages rather than forcing one enormous foundation model to perform every operation.
Command A+ can act as the high-capability reasoning and generation engine. North Mini Code handles specialized agentic software engineering. North Small Translate targets machine translation. Embed v4 provides multimodal semantic representations, while Rerank v4 improves retrieval precision before information reaches the generative model.
The result is a composable enterprise AI ecosystem in which organizations can select specialized components according to workload, latency, infrastructure, privacy and accuracy requirements rather than relying on a single general-purpose model for every task.
5. Enterprise Deployment, Sovereign Infrastructure, and Self-Hosting
Cohere Command A+ is designed for organizations that require greater control over AI infrastructure, model weights, sensitive information, and deployment location. Unlike API-only proprietary models, Command A+ is released under the Apache 2.0 license and can be deployed on infrastructure controlled by the organization.
This makes the model particularly relevant to financial institutions, governments, healthcare organizations, defense environments, telecommunications providers, and other regulated enterprises where sending confidential information to an external AI service may be undesirable or prohibited.
Cohere supports both hosted production access through its enterprise infrastructure and self-hosted deployment of the open model weights.
Command A+ Deployment Options
| Deployment Model | Infrastructure Control | Typical Enterprise Application |
|---|---|---|
| Cohere Hosted API | Low | Rapid application deployment |
| Cohere Model Vault | High | Controlled enterprise production workloads |
| Private Cloud | High | Enterprise AI with isolated infrastructure |
| Virtual Private Cloud | High | Regulated cloud workloads |
| Self-Hosted GPU Infrastructure | Very High | Full model and infrastructure control |
| On-Premises Deployment | Very High | Sensitive internal workloads |
| Air-Gapped Environment | Maximum | Highly restricted or classified environments |
Production Self-Hosting with vLLM
Command A+ can be served using vLLM, allowing organizations to expose the model through an OpenAI-compatible inference interface.
An important correction applies to the supplied technical specifications: the current W4A4 model documentation requires vLLM 0.25.0 or later, not version 0.21.0. Accurate reasoning and tool-call parsing additionally requires Cohere Melody version 0.9.0 or later.
| Self-Hosting Component | Current Requirement |
|---|---|
| Model | Command A+ W4A4 |
| Model Checkpoint | command-a-plus-05-2026-w4a4 |
| Inference Engine | vLLM |
| Minimum vLLM for W4A4 | 0.25.0 |
| Parsing Library | Cohere Melody 0.9.0 or later |
| Tool-Call Parser | Cohere Command parser |
| Reasoning Parser | Cohere Command parser |
| API Compatibility | OpenAI-compatible chat completions |
| Recommended Quantization | W4A4 |
Why Cohere Melody Is Required
Serving an enterprise reasoning model involves more than simply generating text.
Command A+ can generate reasoning information and structured tool calls that must be interpreted correctly by the inference server. Cohere Melody supplies the parsing support required by vLLM to distinguish these structured outputs.
The official configuration therefore enables both Cohere’s tool-call parser and reasoning parser, alongside automatic tool selection.
| Output Type | Infrastructure Requirement |
|---|---|
| Normal Text | Standard model generation |
| Reasoning Output | Cohere-compatible reasoning parser |
| Tool Calls | Cohere-compatible tool-call parser |
| Automatic Tool Choice | Explicit server configuration |
| Multimodal Requests | Image and text request processing |
OpenAI-Compatible API Integration
Once deployed through vLLM, Command A+ can expose an OpenAI-compatible chat-completions endpoint.
This is operationally useful because many existing enterprise AI applications, agent frameworks, development tools, and internal services already understand OpenAI-style request structures. Organizations can therefore potentially replace an external API endpoint with their internally hosted Command A+ service without completely redesigning the application layer.
The official model repository demonstrates both text and multimodal requests through this interface.
Command A+ GPU Requirements
Cohere publishes three principal precision configurations for organizations deploying Command A+.
| Model Format | Minimum NVIDIA Blackwell Configuration | Minimum NVIDIA Hopper Configuration |
|---|---|---|
| BF16 | 4 x B200 | 8 x H100 |
| FP8 | 2 x B200 | 4 x H100 |
| W4A4 | 1 x B200 | 2 x H100 |
Cohere recommends W4A4 for most applications because benchmark differences between the available quantizations are reported as negligible while W4A4 provides better speed, latency, and hardware efficiency.
Dual-H100 Enterprise Deployment
For organizations using NVIDIA Hopper infrastructure, the W4A4 version can operate on a minimum configuration of two H100 GPUs.
Tensor parallelism allows inference workloads and model execution to be distributed across those GPUs. The exact tensor-parallel configuration should nevertheless be selected according to the hardware topology rather than treated as a universal setting.
| Deployment Characteristic | Dual-H100 W4A4 Environment |
|---|---|
| GPU Architecture | NVIDIA Hopper |
| Minimum GPU Count | 2 |
| Model Precision | W4A4 |
| Inference Framework | vLLM |
| API Interface | OpenAI-compatible |
| Tool Calling | Supported |
| Reasoning Parsing | Supported |
| Image Input | Supported |
| Self-Hosted Operation | Supported |
A single NVIDIA B200 represents the smaller officially documented Blackwell deployment configuration.
SGLang as an Alternative Inference Engine
vLLM is not the only self-hosting option.
The official Command A+ model repository also provides instructions for serving the model using SGLang. This gives infrastructure teams additional flexibility when choosing an inference engine based on throughput, batching requirements, hardware topology, operational tooling, and existing infrastructure.
| Inference Option | Command A+ Support |
|---|---|
| Transformers | Supported |
| vLLM | Supported |
| SGLang | Supported |
| OpenAI-Compatible Serving | Supported |
| Containerized Deployment | Supported |
Managed Enterprise Deployment
Organizations that do not want to maintain their own GPU clusters can use Cohere’s managed infrastructure.
Cohere’s current Command A+ documentation identifies Model Vault as its production deployment route. Model Vault is designed to give enterprises dedicated model deployments while reducing the infrastructure-management burden associated with self-hosting a model of this size.
This creates two fundamentally different operating models.
| Approach | Primary Advantage | Primary Trade-Off |
|---|---|---|
| Self-Hosting | Maximum infrastructure control | Organization manages GPU operations |
| Managed Deployment | Lower operational complexity | Less direct infrastructure ownership |
Cloud Provider Availability
Claims that Command A+ is currently available as a specific managed model through Microsoft Azure AI Foundry, Amazon Bedrock, Amazon SageMaker, or Oracle Cloud Infrastructure should be verified against each provider’s current model catalog before publication.
Cohere has broad relationships with major cloud infrastructure providers, but availability of earlier Command models does not automatically establish availability of Command A+ specifically.
The safer distinction is therefore between confirmed Command A+ deployment mechanisms and provider-specific availability that can change over time.
| Deployment Channel | Command A+ Status |
|---|---|
| Cohere API | Confirmed |
| Cohere Model Vault | Confirmed production option |
| Downloadable Open Weights | Confirmed |
| vLLM Self-Hosting | Confirmed |
| SGLang Self-Hosting | Confirmed |
| Transformers | Confirmed |
| Specific Third-Party Clouds | Verify current provider catalog |
Sovereign AI Infrastructure
Sovereign AI refers to an organization’s or country’s ability to operate artificial intelligence while maintaining control over critical elements such as infrastructure, models, data, security policies, and geographic processing location.
Command A+’s open weights and self-hosting capabilities make it suitable for architectures designed around these requirements.
| Sovereignty Requirement | Command A+ Characteristic |
|---|---|
| Model Control | Downloadable weights |
| Infrastructure Control | Self-hosting supported |
| Data Residency | Deployment location can be controlled |
| Network Isolation | Local deployment is technically possible |
| Provider Independence | Model does not require Cohere API execution |
| Commercial Flexibility | Apache 2.0 license |
| Hardware Selection | Multiple supported deployment configurations |
| Application Control | OpenAI-compatible and native integrations |
Air-Gapped AI Deployment
Air-gapped environments are physically or logically isolated from external networks. They are used where information must remain within tightly controlled infrastructure.
Because Command A+ weights can be downloaded and operated locally, an organization can architect an inference environment that does not depend on continuous calls to Cohere’s hosted API.
After the necessary model weights, inference software, dependencies, and supporting assets have been securely transferred into the environment, inference can be performed locally.
This is fundamentally different from API-only AI services, where every inference request inherently depends on communication with external provider infrastructure.
What Air-Gapping Can Protect
| Security Concern | Air-Gapped Deployment Impact |
|---|---|
| Prompt Transmission | Can remain inside controlled infrastructure |
| Document Transmission | Can remain local |
| Model Inference | Performed locally |
| Network Exposure | Can be heavily restricted or eliminated |
| External API Dependency | Not required for model inference |
| Data Residency | Determined by organization |
| Logging | Controlled by internal infrastructure |
| Access Policies | Controlled by organization |
Apache 2.0 and Deployment Freedom
Command A+’s Apache 2.0 license is an important component of its enterprise positioning.
The license permits broad use, modification, distribution, and commercial deployment subject to its terms. This provides organizations considerably greater operational flexibility than models distributed under non-commercial licenses. The official Command A+ model repository confirms the Apache 2.0 licensing.
For enterprises, the practical significance is that Command A+ can become part of internally controlled infrastructure rather than remaining exclusively accessible through Cohere’s hosted services.
Open Weights and Architecture Transparency
Open weights also improve the degree of technical inspection possible compared with closed API-only models.
Security and AI engineering teams can inspect model configuration files, architecture definitions, tokenizer behavior, weight structures, quantization configuration, inference code, and deployment dependencies.
However, open weights should not be confused with complete model transparency.
| Transparency Layer | Open-Weight Availability |
|---|---|
| Model Weights | Available |
| Model Configuration | Available |
| Inference Configuration | Available |
| Quantization Information | Available |
| Architecture Information | Substantially documented |
| Complete Training Dataset | Not fully public |
| Every Training Decision | Not fully public |
| Complete Alignment Dataset | Not fully public |
Consequently, stating that organizations can completely audit the model’s “internal alignment mechanics” would be too strong. Open weights provide substantially more inspectability and deployment control, but they do not expose every aspect of how the model was created.
EU AI Act and Regulatory Compliance
Self-hosting Command A+ can help organizations satisfy certain data governance, security, residency, confidentiality, and infrastructure-control requirements.
It does not, by itself, make an AI deployment compliant with the EU AI Act or any other regulatory regime.
Compliance depends on the complete system and its intended use, including risk classification, data governance, cybersecurity, human oversight, transparency, record keeping, testing, monitoring, documentation, and other applicable obligations.
| Compliance Area | How Self-Hosting Can Help |
|---|---|
| Data Residency | Processing can remain within selected jurisdiction |
| Confidentiality | Sensitive prompts can stay within private systems |
| Access Control | Enterprise controls identity and permissions |
| Logging | Organization controls audit infrastructure |
| Model Versioning | Specific checkpoints can be pinned |
| Network Security | External connectivity can be restricted |
| Retention | Internal policies can govern stored information |
| Regulatory Compliance | Supports controls but does not guarantee compliance |
Self-Hosting Versus Managed Command A+
The choice between self-hosting and managed deployment ultimately depends on how an organization balances sovereignty against operational complexity.
| Decision Factor | Self-Hosted Command A+ | Managed Command A+ |
|---|---|---|
| Infrastructure Control | Very High | Moderate |
| Data Control | Very High | High |
| GPU Management | Customer responsibility | Provider responsibility |
| Deployment Complexity | Higher | Lower |
| Air-Gapped Operation | Possible | Generally unsuitable |
| Scaling Operations | Customer responsibility | Managed |
| Hardware Optimization | Customer controlled | Provider managed |
| Model Customization | Greater flexibility | Platform dependent |
| Time to Production | Longer | Faster |
| Sovereignty Potential | Maximum | Deployment dependent |
Why Command A+ Matters for Sovereign Enterprise AI
Command A+ combines characteristics that rarely appear together in a single enterprise model: 218 billion total parameters, approximately 25 billion active parameters, multimodal input, agentic reasoning, a 128K context window, 64K output capacity, four-bit quantization, downloadable weights, Apache 2.0 licensing, and officially supported self-hosting.
The W4A4 configuration is particularly important because it lowers the documented minimum infrastructure to one NVIDIA B200 or two NVIDIA H100 GPUs, making private deployment considerably more practical than the model’s 218-billion-parameter headline size might suggest.
For enterprises pursuing sovereign AI, the primary advantage is therefore control. Organizations can choose where the model runs, where sensitive information is processed, which networks it can access, how inference is logged, which model version remains in production, and whether external AI APIs participate in the workflow at all.
6. Financial Analysis, Pricing Models, and Total Cost of Ownership
The financial case for Cohere Command A+ differs from conventional API-only AI models because enterprises can choose among limited API access, Cohere-managed dedicated infrastructure, or self-hosted open-weight deployment.
As of September 2026, Command A+ does not have a conventional published per-million-token production price. Cohere currently makes Command A+ free within applicable API limits, while production deployment is primarily offered through Model Vault or private/self-hosted infrastructure. This distinction materially changes any total cost of ownership calculation.
Cohere Generative Model Pricing
Earlier Command models continue to use conventional token-based pricing. Command A+, however, follows a different commercial model for production deployments.
| Model | Context Window | Maximum Output | Input Pricing | Output Pricing |
|---|---|---|---|---|
| Command A+ | 128K | 64K | Free within API limits | Free within API limits |
| Command A | 256K | 8K | $2.50 per 1M tokens | $10.00 per 1M tokens |
| Command R+ 08-2024 | 128K | 4K | $2.50 per 1M tokens | $10.00 per 1M tokens |
| Command R 08-2024 | 128K | 4K | $0.15 per 1M tokens | $0.60 per 1M tokens |
Cohere confirms the $2.50 input and $10 output pricing for Command A, while its pricing documentation lists the same rates for Command R+ 08-2024 and $0.15/$0.60 for Command R.
Therefore, using Command A’s $2.50/$10 rates as a proxy for Command A+ can be useful for hypothetical modeling, but it should not be presented as Command A+’s actual production price.
Command A+ Production Pricing
Command A+ currently has three economically distinct deployment paths.
| Deployment Method | Pricing Structure | Best Suited For |
|---|---|---|
| Evaluation API | Free within limits | Testing and development |
| Cohere Model Vault | Per dedicated instance | Managed enterprise production |
| Self-Hosted Command A+ | Infrastructure cost | Private and sovereign AI |
The API rate limit for Command A+ is currently 20 requests per minute, with production capacity requiring engagement with Cohere. Newer model variants are also subject to a 1,000-call monthly limitation under applicable trial-style access.
Command A+ Model Vault Pricing
Cohere publishes much more concrete pricing for Model Vault, its managed dedicated model infrastructure.
Command A+ is currently priced at $17.50 per hour for the Large performance tier and $32.50 per hour for XL. Generative-model access may require a waitlist, and longer-term commitment pricing is handled separately.
| Command A+ Model Vault Tier | Hourly Price | Approximate 730-Hour Monthly Cost |
|---|---|---|
| Large | $17.50 | $12,775 |
| XL | $32.50 | $23,725 |
These simple monthly figures assume an instance operates continuously for approximately 730 hours. Actual contracted pricing, autoscaling, commitments and capacity requirements can change the final cost.
Model Vault Pricing Across the Cohere Stack
Cohere also publishes dedicated-instance pricing for its retrieval models.
| Model | Performance Tier | Hourly Rate | Monthly Commitment |
|---|---|---|---|
| Embed 4 | Small | $4.00 | $2,500 |
| Embed 4 | Medium | $5.00 | $3,250 |
| Rerank 4 Fast | Medium | $5.00 | $3,250 |
| Rerank 4 Pro | Medium | $5.00 | $3,250 |
| Rerank 4 Pro | Large | $10.00 | $6,500 |
| Command A+ | Large | $17.50 | Contact Cohere |
| Command A+ | XL | $32.50 | Contact Cohere |
This pricing model is important for large enterprises because dedicated inference capacity behaves differently from token billing. Once an instance has been provisioned, utilization becomes a major determinant of effective cost per query.
Retrieval Costs
Cohere’s retrieval products use different billing units from generative models.
Embedding models are charged according to embedded tokens, whereas Rerank is charged according to searches. Cohere defines one Rerank search as one query involving up to 100 documents, although long documents can be split into multiple chunks and consequently consume additional search units.
| AI Operation | Typical Billing Unit |
|---|---|
| Command Generation | Input and output tokens |
| Embed | Embedded tokens |
| Rerank | Searches |
| Model Vault | Dedicated instance capacity |
| Self-Hosting | GPU infrastructure and operations |
This distinction is essential when calculating RAG costs because retrieved context does not automatically imply that all source documents need to be embedded again for every query. In most production architectures, documents are embedded during ingestion and their vectors are reused.
Enterprise RAG Cost Model
Consider an enterprise support and knowledge-management system processing 500,000 requests per month.
| Workload Variable | Monthly Volume |
|---|---|
| Queries | 500,000 |
| Average Input per Query | 3,000 tokens |
| Average Output per Query | 500 tokens |
| Total Input | 1.5 billion tokens |
| Total Output | 250 million tokens |
| Reranking Operations | Approximately 500,000 |
If the hypothetical $2.50/$10 pricing associated with Command A were applied, generation costs would be:
| Component | Calculation | Monthly Cost |
|---|---|---|
| Input | 1,500M × $2.50 per million | $3,750 |
| Output | 250M × $10 per million | $2,500 |
| Generation Total | Input + output | $6,250 |
The arithmetic in the supplied calculation is therefore correct for generation.
However, adding approximately $16,000 for embeddings and reranking without specifying the ingestion volume, index-refresh frequency, number of Rerank documents and current pricing structure creates a misleading estimate.
Why Embedding Costs Should Be Modeled Separately
A typical RAG application embeds its knowledge corpus when documents enter or change within the system.
The resulting vectors are stored in a vector database and reused.
| Event | Usually Requires Re-Embedding? |
|---|---|
| New Document Added | Yes |
| Existing Document Changed | Usually |
| User Submits Query | Query embedding only |
| Document Retrieved | No |
| Document Reranked | No new embedding required |
| Command A+ Generates Answer | No |
Consequently, multiplying all 1.5 billion monthly prompt tokens by an embedding rate would usually overestimate embedding expenditure unless the application genuinely embeds that entire content volume every month.
Self-Hosted Command A+ Economics
Command A+ creates a substantially different TCO equation because the Apache 2.0 weights can be deployed independently.
The W4A4 model has an officially documented minimum hardware configuration of one NVIDIA B200 or two NVIDIA H100 GPUs.
| Quantization | Minimum Blackwell Hardware | Minimum Hopper Hardware |
|---|---|---|
| BF16 | 4 x B200 | 8 x H100 |
| FP8 | 2 x B200 | 4 x H100 |
| W4A4 | 1 x B200 | 2 x H100 |
Cohere recommends W4A4 for most deployments because the company reports negligible benchmark differences between the three available quantizations while W4A4 offers the smallest hardware footprint and superior speed and latency characteristics.
Calculating Self-Hosted Cloud TCO
Assume, purely for financial modeling, that an enterprise obtains two H100 GPUs for $3.50 per GPU-hour.
| Cost Component | Calculation | Monthly Cost |
|---|---|---|
| H100 GPU 1 | $3.50 × 730 hours | $2,555 |
| H100 GPU 2 | $3.50 × 730 hours | $2,555 |
| GPU Infrastructure | Combined | $5,110 |
| Storage, Network and Operations | Assumed | $1,090 |
| Estimated Total | Combined | $6,200 |
The $6,200 figure is mathematically correct under those assumptions.
It should not, however, be described as the universal cost of self-hosting Command A+. H100 prices vary substantially according to provider, geography, commitment period, GPU configuration, networking and availability.
Hidden Costs of Self-Hosting
GPU rental represents only one part of production TCO.
| Cost Category | Self-Hosted Financial Impact |
|---|---|
| GPU Compute | Primary infrastructure expense |
| CPU and System Memory | Required for serving infrastructure |
| Storage | Model weights, logs and application data |
| Networking | Internal and external traffic |
| Engineering | Deployment and optimization |
| Monitoring | Observability and incident detection |
| Security | Hardening and vulnerability management |
| High Availability | Additional replicas may be required |
| Disaster Recovery | Redundant infrastructure |
| Software Maintenance | Inference-engine upgrades |
| Capacity Headroom | Idle resources required for traffic spikes |
| Power and Cooling | Relevant to on-premises deployments |
A production environment requiring high availability may need more than the minimum two-H100 configuration because minimum inference hardware does not provide redundancy.
Managed Model Vault Versus Self-Hosting
Using Cohere’s published Command A+ Model Vault rate provides a more defensible comparison than applying Command A token pricing to Command A+.
| Deployment | Illustrative Monthly Cost | Operations Responsibility |
|---|---|---|
| Command A+ Vault Large | Approximately $12,775 | Cohere |
| Command A+ Vault XL | Approximately $23,725 | Cohere |
| 2-H100 Self-Hosted Example | Approximately $6,200 | Customer |
At the assumed $6,200 self-hosting cost, the raw infrastructure difference versus a continuously running Large Model Vault instance would be approximately $6,575 per month.
That does not mean self-hosting is automatically 51% cheaper overall. Internal engineering, redundancy, monitoring, security and capacity management must also be included.
Effective Cost per Query
At 500,000 requests per month, the infrastructure cost can be converted into a useful operational metric.
| Deployment Scenario | Monthly Cost | Approximate Cost per Query |
|---|---|---|
| Hypothetical Command A Token Rates | $6,250 generation only | $0.0125 |
| Command A+ Vault Large | $12,775 | $0.0256 |
| Command A+ Vault XL | $23,725 | $0.0475 |
| Illustrative 2-H100 Hosting | $6,200 | $0.0124 |
These calculations exclude retrieval, storage, networking and application-level infrastructure unless already included in the scenario.
Utilization Is the Critical Self-Hosting Variable
The economic advantage of self-hosting depends heavily on utilization.
A GPU cluster costing $6,200 per month costs approximately the same whether it spends most of the month generating tokens or sitting idle. API-based pricing behaves differently because expenditure generally rises with consumption.
| Traffic Pattern | Likely Economic Preference |
|---|---|
| Small Experimental Workload | Limited API access |
| Low Production Volume | Managed service |
| Highly Variable Traffic | Managed or autoscaling service |
| Large Stable Traffic | Self-hosting becomes attractive |
| Continuous Internal Usage | Dedicated infrastructure |
| Sensitive Regulated Workload | Private deployment |
| Air-Gapped Workload | Self-hosting |
| Very High Utilization | Self-hosting can improve economics |
The 150-Million-Token Break-Even Claim
The assertion that self-hosting becomes cheaper above 150 million combined tokens per month is not supported by the stated assumptions.
Using the hypothetical Command A prices of $2.50 per million input tokens and $10 per million output tokens, the break-even point depends strongly on the ratio between input and output tokens.
For the stated workload ratio of six input tokens for every output token, the weighted generation cost is approximately $3.57 per million combined tokens.
At an assumed self-hosting cost of $6,200 per month, the theoretical generation-only crossover would therefore occur around 1.74 billion combined tokens per month, not 150 million.
| Metric | Approximate Value |
|---|---|
| Input-to-Output Ratio | 6:1 |
| Weighted API Cost | $3.57 per 1M combined tokens |
| Assumed Self-Hosting Cost | $6,200/month |
| Theoretical Break-Even | Approximately 1.74B tokens/month |
Even this figure is only illustrative because Command A+’s actual production commercial structure is not the assumed $2.50/$10 token schedule.
TCO Decision Matrix
| Financial Factor | Managed Deployment | Self-Hosted Command A+ |
|---|---|---|
| Initial Infrastructure | Low | Higher |
| Cost at Low Utilization | Generally favorable | Generally unfavorable |
| Cost at High Utilization | Can become expensive | Potentially favorable |
| GPU Procurement | Not required | Required |
| Infrastructure Engineers | Limited requirement | Required |
| Scaling | Managed | Customer managed |
| Redundancy | Provider managed | Customer funded |
| Data Sovereignty | Deployment dependent | Maximum control |
| Air-Gapped Operation | Limited | Possible |
| Cost Predictability | High with commitments | High after capacity planning |
| Operational Complexity | Lower | Higher |
Financial Implications for Enterprise Buyers
The strongest economic argument for Command A+ is not simply that self-hosting is always cheaper. Its advantage is optionality.
An organization can experiment using limited API access, move production workloads to Cohere Model Vault, or deploy the Apache 2.0 model on its own GPU infrastructure when utilization, privacy requirements, sovereignty or infrastructure economics justify doing so. Command A+ itself currently remains free through Cohere’s API within its applicable rate limits, while Model Vault provides the clearest published commercial production pricing.
For high-volume deployments, TCO should therefore be calculated using actual measured throughput and utilization rather than a universal token threshold. GPU utilization, redundancy requirements, output-token ratios, retrieval architecture, engineering costs and negotiated Cohere pricing can move the break-even point substantially in either direction.
7. Industry Adoption, Developer Feedback, and Strategic Trade-offs
Cohere Command A+ entered the enterprise AI market with a different positioning from many frontier models. Rather than concentrating exclusively on benchmark leadership or consumer-facing applications, Cohere has emphasized private deployment, agentic workflows, multilingual enterprise AI, open weights, infrastructure efficiency, and data sovereignty.
The model’s Apache 2.0 licensing, 218-billion-parameter Sparse Mixture-of-Experts architecture, 25 billion active parameters, multimodal capabilities, and relatively compact W4A4 deployment footprint make it particularly relevant to organizations that want greater control over their AI infrastructure.
Enterprise Adoption of the Cohere Command Ecosystem
Cohere already has established enterprise relationships spanning technology, consulting, cloud infrastructure, financial services, telecommunications, and government-oriented applications.
However, an important distinction should be made between organizations using the broader Cohere Command ecosystem and organizations confirmed to be running Command A+ specifically.
| Organization or Ecosystem | Confirmed Relationship | Command A+ Specifically Confirmed |
|---|---|---|
| Fujitsu | Strategic Cohere partnership and Takane | Not established for Takane |
| Microsoft Azure AI Foundry | Command A+ listed | Yes |
| Amazon Bedrock | Earlier Command models available | No current Command A+ listing |
| Amazon SageMaker | Earlier Command models supported | No current Command A+ listing |
| Oracle OCI Generative AI | Earlier Command models available | No current Command A+ listing |
| LivePerson | Historical Cohere customer relationship | Not established |
| Notion | Historical Cohere integration | Not established |
This distinction prevents earlier Command deployments from being incorrectly attributed to Command A+.
Fujitsu and the Takane Enterprise Model
Fujitsu represents one of Cohere’s most significant enterprise partnerships.
The companies collaborated to develop Takane, a Japanese enterprise large language model based on Cohere’s Command model family. Takane targets regulated and security-sensitive Japanese organizations and supports applications including multilingual understanding, information extraction, complex reasoning, and enterprise workflow acceleration.
| Fujitsu-Cohere Area | Strategic Role |
|---|---|
| Takane | Japanese enterprise LLM |
| Foundation | Cohere Command technology |
| Target Market | Japanese enterprises |
| Regulated Industries | Major deployment focus |
| Data Extraction | Supported enterprise workload |
| Reasoning | Core capability |
| Multilingual Processing | Enterprise application |
The supplied claim that Takane was built specifically from Command A+ should nevertheless be avoided. The Fujitsu partnership and Takane predate Command A+’s May 2026 release, and Cohere describes Takane more generally as being built using its Command series.
Command A+ on Microsoft Azure AI Foundry
Microsoft’s Azure AI Foundry represents a confirmed third-party cloud route for Command A+.
Cohere’s current platform matrix lists Command A+ under the Azure AI Foundry identifier coherelabs-command-a-plus-05-2026-w4a4.
| Cloud Platform | Command A+ Availability |
|---|---|
| Microsoft Azure AI Foundry | Confirmed |
| Amazon Bedrock | Not currently listed |
| Amazon SageMaker | Not currently listed |
| Oracle OCI Generative AI | Not currently listed |
This corrects an important misconception about cloud availability. OCI, Bedrock, and SageMaker support other Cohere Command models, but Cohere’s current compatibility table does not list Command A+ for those platforms.
LivePerson and Notion
LivePerson and Notion have both been associated with Cohere technologies historically, but they should not be described as confirmed Command A+ adopters without current evidence specifically connecting their production workloads to the May 2026 model.
This distinction is particularly important for an article focused specifically on Command A+ rather than Cohere as a company.
A defensible description would characterize these organizations as examples of the broader enterprise ecosystem and historical adoption of Cohere technology, not as verified Command A+ production deployments.
Developer Interest in Apache 2.0 Licensing
One of the clearest differences between Command A+ and some earlier open-weight Command releases is its Apache 2.0 license.
Cohere explicitly positions the model as open weight and suitable for deployment in private clouds, VPCs, on-premises environments, and fully air-gapped infrastructure.
| Licensing Characteristic | Enterprise Impact |
|---|---|
| Apache 2.0 | Permissive open-source licensing |
| Commercial Use | Permitted under license terms |
| Modification | Permitted |
| Redistribution | Permitted subject to license |
| Self-Hosting | Supported |
| Private Infrastructure | Supported |
| Air-Gapped Deployment | Supported |
| Provider Independence | Significantly increased |
This makes Command A+ particularly attractive to enterprises concerned about vendor lock-in or licenses that impose non-commercial restrictions.
W4A4 Deployment Efficiency
The W4A4 checkpoint is arguably one of Command A+’s most strategically important releases.
Despite having 218 billion total parameters, the model can operate on a minimum of two H100 GPUs or a single B200 in its W4A4 configuration. By comparison, BF16 requires eight H100s or four B200s.
| Precision | Minimum Hopper Configuration | Minimum Blackwell Configuration |
|---|---|---|
| BF16 | 8 x H100 | 4 x B200 |
| FP8 | 4 x H100 | 2 x B200 |
| W4A4 | 2 x H100 | 1 x B200 |
Cohere reports up to a 110% increase in throughput and up to a 30% reduction in latency compared with Command A Reasoning, although these results should be interpreted within Cohere’s test configuration rather than as universal performance guarantees.
Developer Self-Hosting Experience
Early technical experimentation also demonstrates that Command A+ can operate outside Cohere’s managed environment.
For example, an NVIDIA developer-community user documented running the W4A4 checkpoint across a dual DGX Spark configuration with tensor parallelism, vLLM, Cohere Melody, automatic tool choice, and Cohere’s reasoning and tool-call parsers.
This should be treated as community experience rather than an official performance benchmark, but it illustrates the experimentation enabled by downloadable weights and open deployment tooling.
Production Parsing Dependencies
Command A+ requires additional consideration when deployed through vLLM because sophisticated outputs such as reasoning and tool calls need to be parsed correctly.
The current Command A+ W4A4 model card requires vLLM 0.25.0 or later together with Cohere Melody 0.9.0 or later for accurate response parsing.
| Deployment Component | Requirement |
|---|---|
| Inference Engine | vLLM |
| Current W4A4 Requirement | vLLM 0.25.0 or later |
| Parsing Library | Cohere Melody 0.9.0 or later |
| Tool Parser | Cohere Command parser |
| Reasoning Parser | Cohere Command parser |
| Automatic Tool Choice | Supported |
Earlier model-card revisions specified vLLM 0.21.0, explaining why that version appears in some documentation and discussions. The current model card has since increased the requirement to 0.25.0.
128K Context Versus Command A
Command A+ supports 128K of context and up to 64K of output, whereas the earlier dense Command A supports a 256K context window and an 8K maximum output.
This creates a genuine architectural trade-off.
| Context Characteristic | Command A | Command A+ |
|---|---|---|
| Input Context | 256K | 128K |
| Maximum Output | 8K | 64K |
| Architecture | 111B dense | 218B Sparse MoE |
| Active Parameters | 111B | Approximately 25B |
| Image Input | Supported | Supported |
| Agentic Workflows | Supported | Enhanced |
| License | CC-BY-NC | Apache 2.0 |
Applications requiring extremely large input prompts may therefore prefer Command A’s larger context allowance or need stronger retrieval and context-selection strategies when migrating to Command A+.
Conversely, Command A+’s 64K output allowance is eight times that of Command A and is better suited to lengthy agentic execution, reasoning, generation, and tool-oriented workflows.
Unified Enterprise Capabilities
One of Command A+’s major advantages is capability consolidation.
Cohere describes Command A+ as combining vision inputs, reasoning, translation, multilingual processing, and agentic tasks within the same model. It is also the strongest agentic model in the Command family according to Cohere’s release documentation.
| Capability | Command A+ |
|---|---|
| Text Understanding | Integrated |
| Image Understanding | Integrated |
| Reasoning | Integrated |
| Translation | Integrated |
| Tool Use | Integrated |
| Structured Output | Integrated |
| Citations | Integrated |
| Multilingual Processing | 48 languages |
| Enterprise Agents | Core specialization |
For organizations maintaining several specialized models, this consolidation could simplify routing, deployment, monitoring, governance, and infrastructure management.
Citation and RAG Advantages
Command A+ also inherits Cohere’s strong emphasis on enterprise retrieval and grounded generation.
Citations, structured outputs, tool use, and reasoning are explicitly supported capabilities.
This makes the model particularly suitable for enterprise systems where users need to inspect the evidence behind generated information rather than accepting an untraceable response.
However, native citation functionality should not be described as eliminating hallucinations. Citations improve provenance and verification, but the underlying retrieved information and generated interpretation can still contain errors.
Production API Constraints
Command A+ is currently free through Cohere’s API within applicable rate limits, while Cohere directs production customers requiring dedicated capacity toward Model Vault.
This creates an operational distinction between evaluation and large-scale production.
| Deployment Stage | Typical Route |
|---|---|
| Initial Evaluation | Cohere API |
| Development | API or downloaded weights |
| Managed Production | Cohere Model Vault |
| Cloud Deployment | Azure AI Foundry |
| Private Production | Self-hosted weights |
| Sovereign Deployment | VPC or on-premises |
| Maximum Isolation | Air-gapped infrastructure |
Organizations should therefore consider capacity procurement and deployment architecture relatively early rather than assuming that a trial API key can simply scale indefinitely into production.
Strategic Advantages and Operational Constraints
| Strategic Advantages | Operational Constraints |
|---|---|
| Apache 2.0 licensing | 128K context versus Command A’s 256K |
| 218B total model capacity | Large complete model-weight footprint |
| Only approximately 25B parameters active | MoE deployment requires capable infrastructure |
| 1 x B200 or 2 x H100 W4A4 minimum | BF16 requires substantially more hardware |
| Vision and text input | Text-only output |
| 64K maximum output | Long generation increases inference demand |
| Reasoning and agentic capabilities | Agent reliability still requires evaluation |
| 48-language coverage | Performance can vary by language |
| Native citation support | Citations do not guarantee factual correctness |
| Downloadable model weights | Customer assumes infrastructure responsibility |
| Private and air-gapped deployment | Self-hosting increases operational complexity |
| Azure AI Foundry availability | Not currently listed for Bedrock, SageMaker or OCI |
| Model consolidation | Specialized models can still outperform general models |
Where Command A+ Fits Best
Command A+’s characteristics make it especially compelling where infrastructure ownership and enterprise functionality matter simultaneously.
| Organization Type | Command A+ Fit | Primary Reason |
|---|---|---|
| Regulated Enterprise | High | Private deployment and data control |
| Government Agency | High | Sovereign and air-gapped deployment |
| Financial Institution | High | Controlled RAG and agent infrastructure |
| Multinational Enterprise | High | 48-language support |
| Enterprise Search Platform | High | Retrieval and citation capabilities |
| Agent Platform | High | Tool use and reasoning |
| Small Startup | Moderate | Hardware footprint may remain substantial |
| Consumer Chat Application | Moderate | Enterprise specialization may be unnecessary |
| Extreme Long-Context Application | Moderate | 128K input limitation |
| Dedicated Coding Platform | Moderate | Specialized coding models may be stronger |
The Strategic Trade-Off
Command A+ should not be viewed simply as an attempt to build the highest-scoring general-purpose AI model. Its differentiation lies in the combination of enterprise capability and operational control.
The Apache 2.0 license removes an important barrier to commercial self-hosting. Sparse MoE execution reduces active computation to approximately 25 billion parameters despite 218 billion total parameters. W4A4 brings the minimum deployment footprint down to two H100s or one B200. Meanwhile, reasoning, vision, translation, multilingual processing, citations, and tool use are consolidated into one model.
The trade-off is that organizations adopting Command A+ assume more architectural responsibility when self-hosting, face a smaller input context than Command A, need appropriate parsing and inference infrastructure, and cannot assume that strong enterprise-agent performance translates into leadership across every coding, scientific, or general-intelligence benchmark.
For organizations prioritizing sovereign AI, private enterprise agents, multilingual RAG, regulated workloads, and control over model infrastructure, those compromises may be worthwhile. For applications primarily seeking maximum context length, minimal infrastructure management, or category-leading performance in one narrow domain, competing or more specialized models may remain a better fit.
Conclusion
Cohere Command A+ represents a significant evolution in enterprise-focused artificial intelligence, combining large-scale reasoning, multimodal understanding, multilingual processing, retrieval-augmented generation, tool use, and agentic workflows within a single open-weight model. Its 218-billion-parameter Sparse Mixture-of-Experts architecture activates approximately 25 billion parameters per token, balancing substantial model capacity with more practical inference requirements.
One of Command A+’s strongest differentiators is its focus on enterprise deployment and operational control. The Apache 2.0 license, downloadable weights, W4A4 quantization, and support for private cloud, on-premises, and air-gapped infrastructure give organizations greater flexibility over where their models run and how sensitive business data is processed. Its 128K context window and 64K output capacity further support demanding applications involving enterprise agents, document intelligence, multilingual RAG, research, data analysis, and complex multi-step workflows.
Command A+ also benefits from Cohere’s broader enterprise AI ecosystem. Embed v4 can retrieve relevant multimodal information, Rerank v4 can improve search relevance, and Command A+ can then reason over that evidence and generate grounded responses with citations. Specialized models such as North Mini Code extend the ecosystem into agentic software engineering, allowing organizations to select models according to specific workload requirements.
Command A+ is not necessarily the strongest model for every application. Its 128K input context is smaller than the 256K window of Command A, self-hosting still requires substantial GPU infrastructure, and specialized coding or scientific reasoning models may outperform it in particular benchmarks. Organizations should therefore evaluate model quality, infrastructure costs, latency, retrieval performance, security requirements, and total cost of ownership against their actual workloads.
Ultimately, Cohere Command A+ is best understood as an enterprise AI platform foundation rather than simply another large language model. Its combination of sparse inference, reasoning, vision, multilingual capabilities, tool use, citations, open weights, permissive licensing, and sovereign deployment options makes it particularly compelling for enterprises and public-sector organizations building private AI agents, enterprise search systems, RAG applications, document intelligence platforms, and other production AI workflows where control, efficiency, and data governance matter alongside model capability.
If you find this article useful, why not share it with your hiring manager and C-level suite friends and also leave a nice comment below?
We, at the 9cv9 Research Team, strive to bring the latest and most meaningful data, guides, and statistics to your doorstep.
To get access to top-quality guides, click over to 9cv9 Blog.
To hire top talents using our modern AI-powered recruitment agency, find out more at 9cv9 Modern AI-Powered Recruitment Agency.
People Also Ask
What is Cohere Command A+?
Cohere Command A+ is an open-weight enterprise AI model designed for reasoning, multimodal understanding, RAG, tool use, multilingual processing, and agentic workflows.
Who developed Cohere Command A+?
Command A+ was developed by Cohere and Cohere Labs as part of the Command family of enterprise-focused large language models.
How does Cohere Command A+ work?
Command A+ uses a Sparse Mixture-of-Experts architecture that dynamically routes each token through selected expert networks instead of activating the entire model for every token.
How many parameters does Cohere Command A+ have?
Command A+ contains 218 billion total parameters, while approximately 25 billion parameters are activated per token through its sparse Mixture-of-Experts architecture.
What is the Cohere Command A+ context window?
Command A+ supports a 128,000-token context window, allowing it to process lengthy documents, retrieved knowledge, conversations, instructions, and agent histories.
What is the maximum output length of Command A+?
Command A+ can generate up to 64,000 output tokens, making it suitable for lengthy reports, complex reasoning, agentic workflows, document generation, and multi-step tasks.
What is a Sparse Mixture-of-Experts model?
A Sparse Mixture-of-Experts model contains specialized expert networks but activates only selected experts for each token, increasing overall model capacity without using every parameter during inference.
How many experts does Command A+ use?
Command A+ has 128 routed experts plus a shared expert. Eight routed experts are dynamically activated for each token alongside the shared expert.
Is Cohere Command A+ open source?
Command A+ is an open-weight model released under the permissive Apache 2.0 license, enabling broad commercial use, modification, distribution, and self-hosted deployment subject to the license terms.
Can Cohere Command A+ be used commercially?
Yes. Command A+ uses the Apache 2.0 license, which permits commercial applications subject to its terms, making it attractive for businesses building proprietary enterprise AI systems.
Can Cohere Command A+ be self-hosted?
Yes. Organizations can self-host Command A+ on their own infrastructure, giving them greater control over model deployment, sensitive information, security policies, and data residency.
Can Command A+ run on-premises?
Yes. Command A+ can be deployed within controlled on-premises infrastructure, making it suitable for organizations that cannot routinely send sensitive information to external AI APIs.
Can Command A+ run in an air-gapped environment?
Yes. Its downloadable weights allow Command A+ inference to operate without depending on Cohere’s hosted API, enabling architectures for isolated and highly controlled environments.
What hardware is required to run Command A+?
Hardware requirements depend on precision. The W4A4 version has a documented minimum of one NVIDIA B200 or two NVIDIA H100 GPUs, while higher-precision versions require additional GPUs.
What is Command A+ W4A4 quantization?
W4A4 reduces selected model weights and activations to four-bit precision, substantially lowering Command A+’s inference hardware requirements while aiming to preserve model quality.
Does Cohere Command A+ support images?
Yes. Command A+ accepts text and image inputs, enabling multimodal applications involving documents, charts, screenshots, diagrams, scanned materials, and other visual information.
Does Command A+ support AI agents?
Yes. Agentic AI is a major Command A+ use case. The model supports reasoning, tool calling, structured outputs, long workflows, and interactions with external applications and information sources.
Does Cohere Command A+ support RAG?
Yes. Command A+ is designed for retrieval-augmented generation, allowing enterprise applications to retrieve private information and use it as context when producing grounded responses.
Does Command A+ support citations?
Yes. Cohere supports fine-grained citations that can associate generated text with supporting retrieved documents, improving traceability in enterprise RAG and knowledge applications.
Does Command A+ support tool calling?
Yes. Command A+ supports tool use, allowing AI agents to interact with external APIs, databases, search systems, enterprise applications, and other software during multi-step workflows.
How many languages does Cohere Command A+ support?
Command A+ supports 48 languages, making it suitable for multilingual enterprise search, document processing, customer support, translation, RAG, and international AI applications.
What are the main Cohere Command A+ use cases?
Major use cases include enterprise AI agents, RAG, knowledge assistants, document intelligence, enterprise search, multilingual support, data extraction, research, tool automation, and sovereign AI.
Is Command A+ good for enterprise search?
Yes. Command A+ can work with retrieval systems such as embeddings and reranking to interpret enterprise knowledge and produce contextual, grounded answers with supporting citations.
What is the difference between Command A and Command A+?
Command A provides a larger 256K input context, while Command A+ uses a 218B Sparse MoE architecture, activates about 25B parameters per token, supports up to 64K output, and uses Apache 2.0 licensing.
Is Command A+ better than Command R+?
Command A+ is newer and designed for more advanced reasoning, multimodal, agentic, multilingual, and enterprise workloads. The best model still depends on application requirements, infrastructure, latency, and cost.
Is Cohere Command A+ good for coding?
Command A+ can handle coding and tool-based workflows, but organizations focused primarily on software engineering should also compare specialized coding models designed specifically for agentic development.
What is Cohere Embed v4?
Embed v4 is Cohere’s multimodal embedding model for representing text and images as vectors. It can serve as the semantic retrieval layer in RAG and enterprise search applications.
What is Cohere Rerank v4?
Rerank v4 reorders retrieved documents according to their relevance to a query. It can improve the quality of evidence supplied to Command A+ in enterprise search and RAG systems.
What is sovereign AI and how does Command A+ support it?
Sovereign AI emphasizes control over models, data, infrastructure, and processing locations. Command A+ supports this approach through open weights, self-hosting, private deployment, and Apache 2.0 licensing.
Is Cohere Command A+ suitable for enterprise AI in 2026?
Yes. Command A+ is particularly relevant for enterprises needing private AI agents, multilingual RAG, multimodal document intelligence, tool use, citations, self-hosting, and greater control over AI infrastructure.
Sources
Cohere AQ Score HokAI Lightning AI Codersera GIGAZINE ZharfAI AI Prompt Packs Business Wire note Local AI Master CorX Labs Medium Microsoft Tech Community arXiv Spheron Network Sebastian Raschka Snippets AI Kingy AI The Rundown AI OpenRouter ExplainX KJU eesel AI Microsoft Developer Blogs Microsoft Amazon Web Services Oracle Reddit