Key Takeaways
- Schematron V2 transforms complex HTML into structured JSON using schema-driven AI extraction, reducing reliance on fragile CSS selectors and manual scraping rules.
- Schematron V2 Small prioritizes extraction quality for complex documents, while V2 Turbo delivers higher throughput and lower costs for large-scale web data extraction.
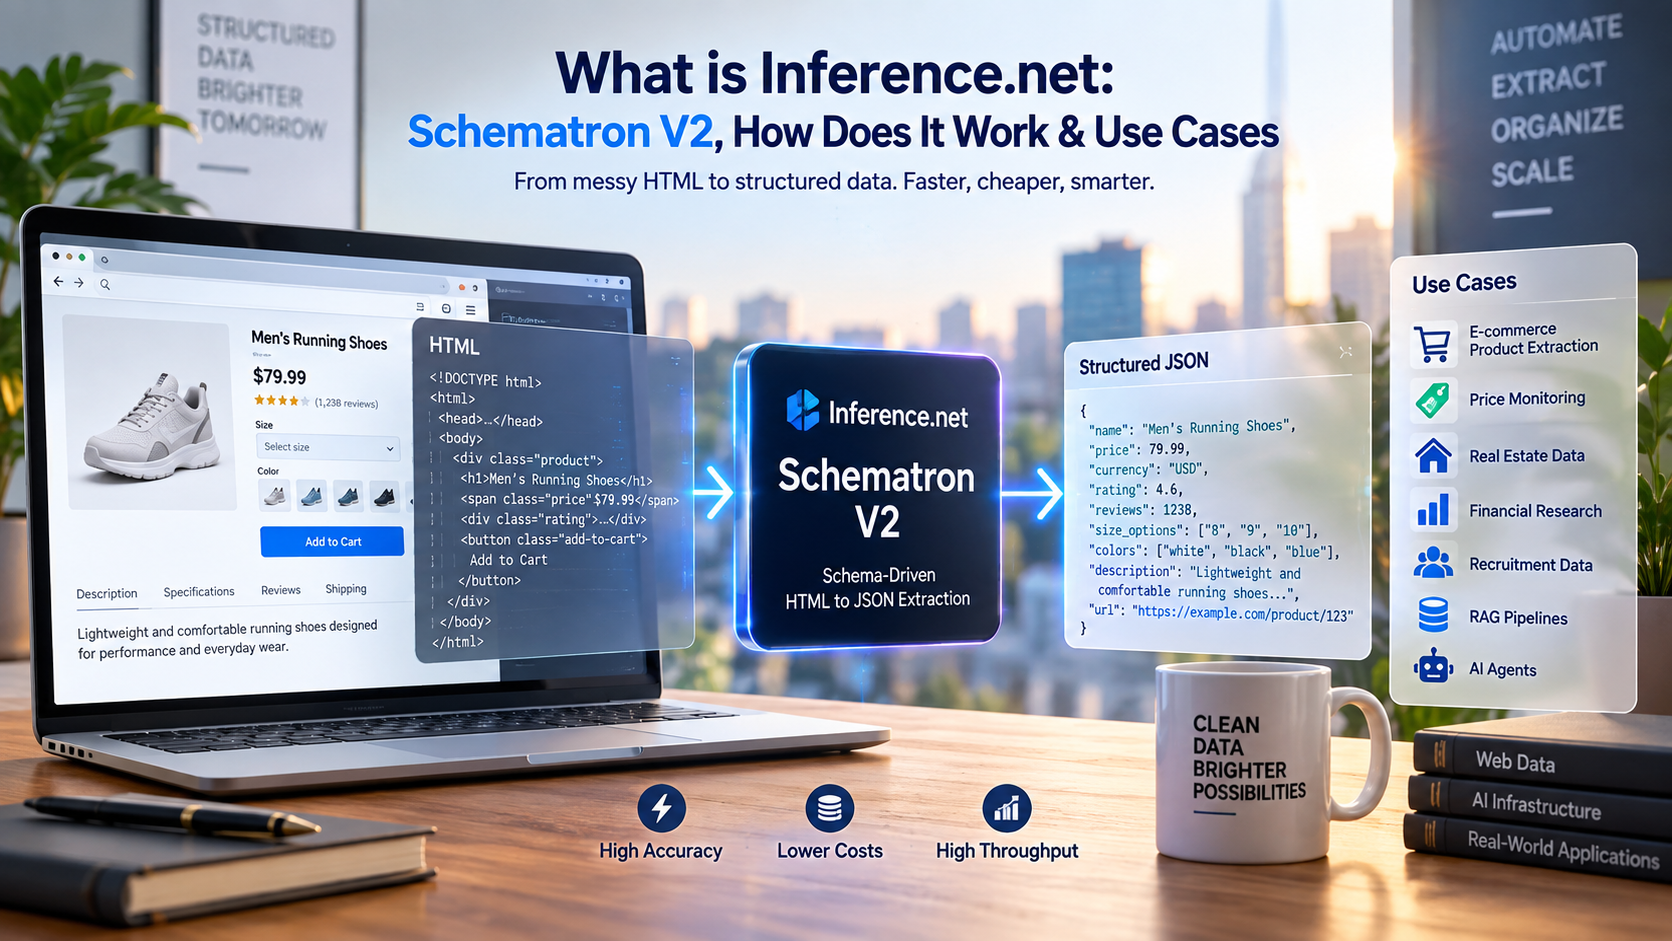
- Key Schematron V2 use cases include e-commerce product extraction, price monitoring, financial and real estate data, recruitment intelligence, RAG pipelines, and AI agents.
Inference.net Schematron V2 transforms unstructured HTML into structured JSON using predefined schemas instead of complex prompts. Designed for fast, cost-efficient web data extraction, it supports applications such as e-commerce product parsing, price monitoring, financial research, real estate intelligence, recruitment data, RAG pipelines, and AI agents.
The modern web contains an enormous amount of valuable business data, but much of it remains trapped inside complex, inconsistent, and frequently changing HTML. E-commerce products, property listings, job advertisements, financial information, pricing data, reviews, and company profiles may all be publicly accessible, yet converting those pages into reliable structured datasets can require substantial engineering work. This is the problem that Inference.net Schematron V2 is designed to address.

Inference.net Schematron V2 is a specialized AI model family built for HTML-to-JSON data extraction at scale. Instead of asking a general-purpose large language model to read an entire webpage and respond to a lengthy extraction prompt, developers can define the structure of the information they need and use Schematron V2 to transform relevant webpage content into structured JSON. This schema-driven approach makes Schematron particularly useful for applications where predictable, machine-readable output is more important than conversational reasoning.
Schematron V2 is available in two complementary variants: Schematron V2 Small and Schematron V2 Turbo. Small focuses on extraction quality and more challenging schemas, making it suitable for complex webpages and accuracy-sensitive workloads. Turbo prioritizes throughput and cost efficiency, making it particularly attractive for businesses processing hundreds of thousands or millions of webpages. Both are designed around long-context HTML extraction and structured output.
The technology addresses one of the biggest limitations of traditional web scraping. Conventional scrapers often depend on CSS selectors, XPath expressions, or site-specific parsing rules. These approaches remain highly effective for predictable websites, but maintaining them across thousands of different layouts can become difficult. A schema-driven extraction model can instead identify semantically equivalent information even when websites represent that information differently.
Consider product pricing as an example. One retailer might display a product price inside a specific HTML class, another may use a completely different component structure, while a third could simultaneously show a regular price, discounted price, installment amount, and membership price. With Schematron V2, developers can define fields such as product name, current price, original price, currency, SKU, availability, brand, specifications, and variants, then extract those concepts into a consistent structure.
This makes Schematron V2 relevant far beyond basic web scraping. Potential Schematron V2 use cases include e-commerce product data extraction, competitive price monitoring, real estate intelligence, financial research, recruitment and job aggregation, market research, web intelligence, RAG pipelines, and AI agents that need structured information from webpages before making decisions.
Schematron V2 can also play an important role in the emerging architecture of AI agents. Instead of sending large quantities of noisy webpage HTML directly to expensive reasoning models, an application can retrieve a webpage, clean unnecessary markup, use Schematron to extract the required information, and pass a smaller structured representation to the reasoning layer. This separation between extraction and reasoning can make AI workflows more efficient and easier to validate.
However, Schematron V2 should not be confused with a complete web crawling platform. It primarily handles the extraction stage. Developers may still need crawlers, browser automation, JavaScript rendering, proxy infrastructure, anti-bot handling, preprocessing, storage, validation, and monitoring depending on the application. Likewise, websites offering reliable APIs, JSON-LD, XBRL, or other native structured data may be better served by deterministic parsing.
The broader significance of Inference.net Schematron V2 is therefore not simply that another AI model can read webpages. It represents a more specialized approach to large-scale AI data infrastructure: use purpose-built models for repetitive extraction tasks and reserve powerful general-purpose models for reasoning, synthesis, planning, and decision-making.
For businesses building data-intensive applications in 2026, this distinction can have major implications for scalability, cost, reliability, and architecture. Understanding what Schematron V2 is, how its schema-driven HTML-to-JSON extraction works, how Small differs from Turbo, and where it fits within a complete data pipeline can help teams determine whether it is the right technology for their web extraction workloads.
This guide explores how Inference.net Schematron V2 works, its key features and model options, its advantages and limitations, and practical use cases across e-commerce, finance, real estate, recruitment, RAG, AI agents, and large-scale web intelligence.
Before we venture further into this article, we would like to share who we are and what we do.
About 9cv9
9cv9 is a business tech startup based in Singapore and Asia, with a strong presence all over the world.
With over ten years of startup and business experience, and being highly involved in connecting with thousands of companies and startups, the 9cv9 team has listed some of the top and best companies/tools in this review.
If you like to get your company listed in our top B2B software reviews, check out our world-class 9cv9 Media and PR service and pricing plans here.
What is Inference.net: Schematron V2, How Does It Work & Use Cases
- What Is Inference.net Schematron V2?
- Technical Architecture and Zero-Prompt Execution Mechanism
- Model Evolution: Schematron V1 to Schematron V2
- Empirical Benchmarks, Latency, and Accuracy Metrics
- Economic Models, Token Pricing, and Operational Cost Infrastructure
- Industry Use Cases, Implementation Paradigms, and Community Feedback2
- Technical Boundaries, Operational Guidelines, and Future Outlook
1. What Is Inference.net Schematron V2?
Inference.net Schematron V2 is a family of specialized language models designed specifically to convert messy, unstructured HTML into clean, structured, schema-conforming JSON data. Rather than using a large general-purpose AI model for web extraction, Schematron V2 concentrates its capabilities on a narrower task: understanding web-page structure and extracting the requested information into predefined data fields.
Released in April 2026, Schematron V2 succeeds the original Schematron 3B and 8B models. The second generation consists primarily of Schematron V2 Small, which prioritizes extraction quality, and Schematron V2 Turbo, which prioritizes throughput and lower operating costs.
The technology is particularly relevant for businesses building large-scale web scraping, product intelligence, competitive monitoring, search, data enrichment, AI agent, and retrieval-augmented generation systems. Instead of maintaining thousands of website-specific CSS selectors and XPath rules, developers can define the structure of the information they need and allow Schematron V2 to map relevant HTML content into that schema.
| Schematron V2 Attribute | Description | Business Significance |
|---|---|---|
| Primary function | HTML-to-JSON extraction | Converts web pages into machine-readable datasets |
| Extraction approach | Schema-guided AI extraction | Reduces dependence on site-specific parsing rules |
| Input | HTML web content | Works with complex and noisy web documents |
| Output | Structured JSON | Simplifies downstream databases, APIs and analytics |
| Maximum context | Up to 128K tokens | Supports unusually long web documents |
| V2 Small | Quality-focused model | Better suited to difficult extraction workloads |
| V2 Turbo | Throughput-focused model | Better suited to large-scale extraction pipelines |
| Structured output | Strict schema adherence | Improves consistency of production data pipelines |
Why Schematron V2 Was Developed
Traditional web scraping generally relies on deterministic parsers using CSS selectors, XPath expressions or custom extraction rules. These techniques can be extremely efficient when websites maintain stable structures, but their reliability declines when layouts, class names, templates or page components change.
Large language models introduced another approach. A general-purpose LLM can examine a page semantically and identify information even when the underlying layout changes. However, feeding thousands of HTML tokens into large frontier models can become expensive when extraction is performed across hundreds of thousands or millions of pages.
Schematron V2 attempts to occupy the middle ground.
| Extraction Method | Main Strength | Main Weakness | Best Environment |
|---|---|---|---|
| CSS selectors | Very fast and inexpensive | Fragile when layouts change | Stable websites |
| XPath | Precise structural targeting | Requires maintenance | Predictable HTML |
| Regex parsing | Lightweight | Poor for complex documents | Simple patterns |
| General-purpose LLM | Strong semantic understanding | Higher inference cost | Irregular reasoning-heavy extraction |
| Schematron V2 | Specialized semantic extraction | Focused mainly on structured extraction | Large-scale HTML-to-JSON workloads |
Its specialization matters economically because an extraction pipeline does not necessarily need the broad reasoning, writing, coding and conversational abilities provided by a frontier general-purpose model.
Schematron instead allocates its capabilities toward understanding HTML structures, identifying requested fields and producing schema-conforming output.
How Inference.net Schematron V2 Works
Schematron V2 operates through a schema-first extraction architecture.
Instead of instructing the model with lengthy natural-language prompts, developers define the structure of the information that should be returned. The HTML document becomes the source material, while the schema defines the expected output.
Inference.net specifically recommends preprocessing HTML to remove unnecessary scripts, styles and JavaScript. Its documentation recommends lxml because this preprocessing approach resembles the data preparation used during Schematron training.
A typical pipeline therefore follows this structure:
| Processing Stage | Operation | Result |
|---|---|---|
| Web acquisition | Fetch target page | Raw HTML |
| Preprocessing | Remove scripts, styles and unnecessary markup | Cleaner HTML |
| Schema definition | Define required fields and data types | Extraction specification |
| Model inference | Submit HTML with schema | Semantic extraction |
| Structured generation | Map discovered information into fields | JSON output |
| Validation | Verify required fields and types | Production-ready record |
| Storage | Send results downstream | Database, warehouse, search index or API |
For example, an e-commerce company could define fields such as product name, price, currency, SKU, manufacturer, availability, description and specifications.
Schematron analyzes the page and attempts to locate information corresponding to those fields regardless of whether individual websites organize the information differently.
Schema-First Extraction Explained
The schema is one of the most important elements of Schematron’s architecture.
Traditional scraping essentially asks:
“Where on this particular website is the price located?”
Schema-guided extraction instead asks:
“What is the price represented on this page?”
That distinction allows extraction systems to become less dependent on a specific page layout.
Inference.net supports schema-first extraction using JSON Schema or typed models such as Pydantic. Its documentation reports strict JSON output and 100% schema adherence, meaning generated responses conform structurally to the supplied schema.
| Traditional Scraping Logic | Schematron V2 Logic |
|---|---|
| Find a specific HTML element | Identify information matching a schema field |
| Depends heavily on page structure | Depends more heavily on semantic meaning |
| Rules often differ by website | One schema can potentially cover many websites |
| Layout changes can break selectors | More resilient to structural variation |
| Engineering maintains parsers | Engineering maintains schemas and validation |
Schematron V2 Small vs Schematron V2 Turbo
The two V2 models address different production priorities.
Schematron V2 Small is optimized for higher extraction quality and is recommended for complex schemas and very long documents. Schematron V2 Turbo sacrifices a small amount of benchmark quality in exchange for substantially greater throughput and lower token pricing.
| Metric | Schematron V2 Small | Schematron V2 Turbo |
|---|---|---|
| Primary priority | Maximum extraction quality | Maximum throughput |
| LLM-as-judge score | 4.060 / 5 | 4.039 / 5 |
| Throughput on single H100 | 2.47 requests/sec | 4.14 requests/sec |
| Input price per 1M tokens | $0.05 | $0.03 |
| Output price per 1M tokens | $0.25 | $0.15 |
| Context capability | Up to 128K tokens | Up to 128K tokens |
| Recommended workload | Difficult pages and complex schemas | High-volume extraction |
| Cost profile | Higher | Lower |
These published figures show how narrow the quality difference is relative to the throughput difference. Turbo processes approximately 68% more requests per second than Small under the published single-H100 benchmark while costing roughly 40% less per token.
Schematron V2 Performance
Inference.net evaluated the models using an LLM-as-judge methodology in which GPT-5.4 graded extraction quality on a five-point scale. V2 Small received 4.060 while Turbo received 4.039. The company reports that both models exceeded DeepSeek V3.2 and GPT-5.4 Nano in its extraction benchmark.
| Performance Indicator | V2 Small | V2 Turbo |
|---|---|---|
| Extraction quality | 4.060 | 4.039 |
| SimpleQA score | 83.10 | 79.42 |
| Single-H100 throughput | 2.47 req/s | 4.14 req/s |
| Relative positioning | Quality leader | Throughput leader |
These figures should be interpreted as vendor-published benchmarks rather than universal guarantees. Real-world performance will depend on HTML quality, schema complexity, document length, field ambiguity and preprocessing.
Why Specialized Models Can Reduce Web Extraction Costs
HTML extraction is unusually input-heavy.
A web page may contain thousands or tens of thousands of tokens while producing only a relatively small JSON record. Consequently, input-token pricing can dominate extraction economics.
At current published pricing, Schematron V2 Turbo costs $0.03 per million input tokens and V2 Small costs $0.05. Output pricing is $0.15 and $0.25 per million tokens respectively.
Consider a simplified workload where every cleaned page contains approximately 10,000 input tokens.
| Workload | Approximate Input Tokens | V2 Turbo Input Cost | V2 Small Input Cost |
|---|---|---|---|
| 1,000 pages | 10 million | $0.30 | $0.50 |
| 10,000 pages | 100 million | $3.00 | $5.00 |
| 100,000 pages | 1 billion | $30.00 | $50.00 |
| 1 million pages | 10 billion | $300.00 | $500.00 |
These calculations cover input tokens only and illustrate why specialized extraction models become particularly attractive at web scale.
Major Schematron V2 Use Cases
Schematron V2 is applicable wherever organizations repeatedly transform heterogeneous web pages into predictable structured records.
| Use Case | Information Extracted | Typical Destination |
|---|---|---|
| E-commerce intelligence | Products, prices, SKUs, specifications | Product database |
| Price monitoring | Price, discount, currency, availability | Pricing engine |
| Marketplace aggregation | Listings, sellers, categories, attributes | Marketplace catalog |
| Real estate intelligence | Property details, prices, locations, amenities | Property database |
| Recruitment data | Job titles, companies, locations, requirements | Recruitment platform |
| Company intelligence | Company names, descriptions, industries, contacts | CRM or research database |
| News monitoring | Headlines, dates, authors, entities | Monitoring platform |
| Financial research | Tables, metrics and company information | Analytical database |
| RAG pipelines | Structured facts and metadata | Vector or retrieval system |
| AI agents | Machine-readable web observations | Agent context layer |
E-Commerce and Product Data Extraction
E-commerce represents one of the clearest applications.
Different retailers may describe essentially identical products through completely different HTML structures. A schema-guided extractor can normalize these pages into a consistent product format containing fields such as title, brand, SKU, price, currency, availability, specifications and category.
Inference.net specifically positions Turbo for large catalog extraction workloads and Small for difficult pages or complex product schemas.
This can support price comparison engines, marketplace aggregation, competitor monitoring, assortment analysis and dynamic pricing systems.
Price Intelligence and Competitive Monitoring
Businesses monitoring competitor pricing frequently need to process large numbers of product pages repeatedly.
Schematron V2 can transform those pages into standardized records containing product identifier, current price, original price, discount, currency, stock availability and other commercial attributes.
Turbo’s 4.14 requests-per-second published single-H100 throughput makes it particularly relevant when extraction volume matters more than achieving the final incremental amount of benchmark accuracy.
AI Agents and Retrieval-Augmented Generation
Schematron V2 can also operate as an intermediate layer between the web and another AI system.
Instead of giving an AI agent an entire noisy webpage, a system can first extract only the information relevant to the task.
| Direct Web-to-LLM Pipeline | Schematron-Assisted Pipeline |
|---|---|
| Retrieve webpage | Retrieve webpage |
| Send large HTML document to LLM | Clean HTML |
| LLM interprets entire document | Schematron extracts defined fields |
| Generate answer | Send compact structured data to LLM |
| Higher context consumption | Generate answer from normalized evidence |
This architecture can reduce unnecessary context consumption and provide downstream models with cleaner, more predictable evidence.
Batch and Large-Scale Data Processing
Inference.net provides asynchronous processing options for larger extraction workloads.
Its Batch API supports as many as 50,000 extraction jobs in a submission, while its Group API is intended for smaller groups of up to 50 requests. Webhook-based updates can also be incorporated into asynchronous processing architectures.
| Processing Method | Intended Scale | Typical Application |
|---|---|---|
| Individual request | Single-page extraction | Interactive applications |
| Group processing | Up to 50 requests | Smaller extraction batches |
| Batch API | Up to 50,000 jobs | Large datasets |
| Webhook workflow | Asynchronous processing | Automated production pipelines |
Where Schematron V2 Fits in a Modern Data Stack
Schematron should not be viewed as an entire web scraping platform by itself.
Crawling and extraction remain separate responsibilities. A crawler discovers and retrieves pages; Schematron transforms their HTML into structured records. Inference.net’s own guidance explicitly distinguishes fetching from extraction.
A typical architecture looks like this:
| Infrastructure Layer | Responsibility |
|---|---|
| URL discovery | Determine pages to process |
| Crawler or browser | Retrieve HTML |
| HTML preprocessing | Remove unnecessary page noise |
| Schematron V2 | Convert HTML into structured JSON |
| Validation layer | Verify data quality |
| Storage layer | Persist structured records |
| Analytics or AI layer | Consume extracted information |
This distinction is important because Schematron does not eliminate the challenges of crawling, proxy management, JavaScript rendering, anti-bot systems or website access policies. Its specialization begins primarily after usable HTML has been obtained.
Limitations of Schematron V2
Schematron V2 is intentionally specialized rather than universal.
Its maximum context window is 128K tokens, meaning exceptionally large documents may require truncation or chunking. Schemas also need sufficiently clear field definitions when the requested information is ambiguous.
Most importantly, Schematron is primarily an extraction model rather than a broad reasoning engine.
| Requirement | Schematron V2 Suitability |
|---|---|
| HTML-to-JSON conversion | Excellent |
| Product extraction | Excellent |
| Price extraction | Excellent |
| Large-scale structured web ingestion | Excellent |
| Long HTML processing | Strong |
| General conversational AI | Not its primary purpose |
| Creative content generation | Not appropriate |
| Complex strategic reasoning | General-purpose LLM preferable |
| Web crawling | Requires separate infrastructure |
| Browser automation | Requires separate tooling |
Schematron V2 Small or Turbo: Which Should Businesses Choose?
The decision largely depends on the economics and complexity of the extraction workload.
| Business Requirement | Recommended Model |
|---|---|
| Millions of relatively predictable pages | V2 Turbo |
| Lowest extraction cost | V2 Turbo |
| Maximum throughput | V2 Turbo |
| Price monitoring | V2 Turbo |
| Large product catalogs | V2 Turbo |
| Complex nested schemas | V2 Small |
| Very long documents | V2 Small |
| Difficult or irregular pages | V2 Small |
| Highest available extraction quality | V2 Small |
Organizations can also adopt a tiered architecture: Turbo handles the majority of routine pages while difficult or failed extraction cases are escalated to Small or, when genuine reasoning is required, to a larger general-purpose model.
The Significance of Schematron V2
Schematron V2 reflects a broader shift in artificial intelligence infrastructure toward specialized language models.
The conventional assumption that every AI workload should be sent to increasingly large general-purpose models is economically inefficient for many narrowly defined production tasks. HTML extraction is a strong example because the system primarily needs structural understanding, semantic field identification and reliable structured output.
Schematron V2 attempts to optimize specifically for those requirements.
Its combination of schema-first extraction, up to 128K-token context, strict structured output, low token pricing and specialized Small and Turbo variants makes it particularly relevant for organizations processing web data at scale.
Rather than replacing crawlers, databases or general-purpose LLMs, Schematron V2 can serve as the structured extraction layer connecting them. For e-commerce intelligence, competitive monitoring, AI agents, RAG systems, recruitment data, real estate analytics and other web-data applications, that specialization can turn large volumes of inconsistent HTML into standardized information that downstream software can actually use.
2. Technical Architecture and Zero-Prompt Execution Mechanism
Schematron V2 is designed around a schema-first, promptless extraction architecture. Unlike conventional general-purpose language model workflows, the model does not rely on user or system prompts to explain what information should be extracted. Instead, the requested data structure itself becomes the extraction instruction.
Inference.net documentation explicitly states that Schematron does not use user or system prompts for extraction instructions. Developers define the required fields through a JSON Schema or typed data model, while the webpage HTML is supplied as the source material. Field names, types and descriptions tell the model what information should be returned.
This architecture turns Schematron V2 from a conversational interface into a specialized HTML-to-structured-data engine.
| Architecture Element | Schematron V2 Approach | Conventional LLM Approach |
|---|---|---|
| Extraction instructions | JSON Schema or typed model | Natural-language prompt |
| HTML input | Supplied as source content | Usually embedded in prompt |
| Field requirements | Defined by schema | Explained through instructions |
| Nested structures | Defined directly in schema | Described conversationally |
| Output format | Strict structured JSON | May require formatting instructions |
| Schema validation | Native structured-output workflow | Often requires additional validation |
| Prompt engineering | Minimal for extraction | Frequently required |
| Primary purpose | Structured extraction | General-purpose generation |
How the Zero-Prompt Architecture Works
The term “zero-prompt” is best understood as an extraction architecture rather than the literal absence of an API message.
The HTML still needs to be transmitted to the model. However, developers do not need to write extraction instructions such as “find the product name, determine its price and return only JSON.”
Instead, the schema communicates those requirements.
For example, an e-commerce extraction schema might contain:
| Schema Field | Data Type | Extraction Meaning |
|---|---|---|
| product_name | String | Exact product title |
| price | Number | Current purchase price |
| currency | String | Currency associated with price |
| brand | String or null | Product manufacturer |
| in_stock | Boolean | Current purchasing availability |
| specifications | Object | Product attributes and values |
| variants | Array | Available product configurations |
Field descriptions become particularly important when the underlying information could be interpreted in several ways. A field called “price,” for example, could represent list price, sale price, subscription price or starting price.
A more explicit schema description can specify that the field represents the active purchase price rather than the crossed-out manufacturer’s suggested retail price.
Inference.net recommends making schema descriptions explicit when extraction requires interpretation, summarization or synthesis because Schematron does not accept separate extraction directions.
Structured Outputs as the Control Layer
Schematron V2 works through the OpenAI-compatible API architecture supported by Inference.net. Structured output requirements can be supplied through response_format, including strict JSON Schema definitions.
The architecture can therefore be conceptualized as:
HTML Document
→ Typed Schema
→ Schematron V2
→ Schema-Conforming JSON
→ Application Validation
→ Downstream Data System
This removes much of the prompt-engineering layer normally positioned between the source document and the model.
| Conventional Extraction Pipeline | Schematron V2 Pipeline |
|---|---|
| HTML document | HTML document |
| System prompt | Schema |
| Extraction instructions | Field descriptions |
| Few-shot examples | Usually unnecessary |
| Formatting instructions | Structured response format |
| LLM generation | Specialized extraction |
| JSON cleanup | Structured JSON |
| Schema validation | Typed validation |
Inference.net reports 100% schema adherence for Schematron’s strict JSON mode. This means structural compliance is one of the model’s core design objectives, although schema compliance should not be confused with guaranteed factual extraction accuracy. A response can satisfy a schema structurally while still requiring validation of the values extracted from the source document.
Typed Schema Integration
Schematron V2 can be integrated with typed application models rather than manually maintained JSON definitions.
Inference.net provides examples using Zod in TypeScript and Pydantic in Python. These frameworks allow developers to define application-level data structures that can simultaneously function as extraction contracts and validation models.
| Development Environment | Schema Approach | Practical Benefit |
|---|---|---|
| TypeScript | Zod | Runtime validation and typed application data |
| Python | Pydantic | Typed models and automatic validation |
| Other environments | JSON Schema | Language-independent extraction contract |
This design can reduce differences between what the AI is expected to produce and what downstream software expects to receive.
Long-Context HTML Processing
Schematron V2 supports HTML documents with context lengths of up to 128K tokens. This makes the models suitable for substantial product pages, marketplace listings, financial documents, directories and other large webpages.
| Processing Characteristic | Schematron V2 Capability |
|---|---|
| Maximum context | Up to 128K tokens |
| Input orientation | Long and noisy HTML |
| Nested extraction | Supported |
| Array extraction | Supported |
| Structured JSON | Supported |
| Typed schemas | Supported |
| Very large documents beyond context | Truncation or chunking required |
Inference.net recommends trimming HTML to relevant regions whenever possible rather than automatically transmitting an entire page. Reducing irrelevant markup lowers token consumption and gives the extraction model less noise to process.
HTML Preprocessing Layer
Schematron is responsible for extracting information, not retrieving webpages.
A production architecture therefore normally places a crawling or rendering system upstream of the model. HTTP clients, crawlers, proxy infrastructure or browser automation systems first obtain the HTML. Schematron subsequently receives that markup for extraction.
Cleaning the HTML before inference is also recommended. Inference.net provides an example based on lxml that removes scripts, JavaScript, styles and inline styling before extraction.
| HTML Component | Typical Treatment | Reason |
|---|---|---|
| Product text | Retain | Contains extraction evidence |
| Headings | Retain | Provides semantic hierarchy |
| Tables | Retain | Frequently contain structured facts |
| Lists | Retain | Common source of specifications |
| Links | Usually retain relevant content | May contain useful labels or destinations |
| Scripts | Remove | Usually irrelevant to extraction |
| JavaScript | Remove | Adds substantial noise |
| Styles | Remove | Visual formatting rarely contributes facts |
| Inline styling | Remove | Reduces unnecessary input |
The exact token reduction depends heavily on the webpage. Therefore, claims that preprocessing always reduces context by a specific percentage should be treated as workload-dependent rather than as a guaranteed Schematron V2 performance characteristic.
Five-Layer Production Architecture
A practical Schematron V2 deployment can be divided into five major layers.
| Architecture Layer | Primary Responsibility | Typical Output |
|---|---|---|
| Acquisition Layer | Fetch or render webpages | Raw HTML |
| Preprocessing Layer | Remove irrelevant markup | Cleaned HTML |
| Extraction Layer | Run Schematron V2 against schema | Structured JSON |
| Validation Layer | Enforce application rules | Validated records |
| Distribution Layer | Store or transmit results | Production datasets |
Acquisition Layer
The first layer handles URL discovery, HTTP requests, proxy management, browser rendering and other web-access responsibilities.
This separation is important because Schematron V2 should not be interpreted as an autonomous crawler. A page must first be retrieved by another component before its HTML can be processed.
Preprocessing Layer
The retrieved markup is normalized and cleaned. Scripts, styles and other unnecessary elements can be removed while semantic content is preserved.
This stage improves extraction economics because Schematron pricing is token-based. Sending unnecessary markup therefore creates avoidable processing costs.
Extraction Layer
Cleaned HTML and the required schema are submitted to Schematron V2.
Schematron V2 Small is positioned for difficult extraction problems, complex schemas and very long pages, while V2 Turbo prioritizes throughput and lower costs for large-volume processing.
Validation Layer
Returned data can subsequently be validated using Pydantic, Zod, JSON Schema validation or application-specific business rules.
This layer remains important even with strict schema adherence.
| Validation Type | Example |
|---|---|
| Structural validation | Price must be numeric |
| Required-field validation | Product name cannot be missing |
| Range validation | Quantity cannot be negative |
| Format validation | Currency should follow expected format |
| Business validation | Sale price should not exceed configured limits |
| Cross-field validation | Discounted price should correspond with original price |
Distribution Layer
Validated records can finally enter operational systems such as relational databases, warehouses, search indexes, analytics platforms, product catalogs or retrieval systems.
The architecture consequently keeps AI extraction isolated from both webpage acquisition and downstream business logic.
Synchronous vs Asynchronous Processing
Inference.net provides multiple execution patterns for different workload sizes.
| Processing Mode | Maximum Request Scale | Input Method | Best Use Case |
|---|---|---|---|
| Standard API | Individual requests | API request | Real-time extraction |
| Group API | Up to 50 requests | JSON array | Small asynchronous workloads |
| Batch API | Up to 1,000,000 requests | JSONL file | Large offline extraction pipelines |
The current Inference.net documentation lists a maximum of 50 requests for the Group API and 1,000,000 requests for the Batch API. Both support webhook-based workflows.
This is an important update to earlier Schematron documentation that described a 50,000-job Batch API limit. The current general Batch API documentation supports substantially larger workloads.
Batch API Architecture
For large-scale extraction, the Batch API separates job submission from immediate inference execution.
Engineering teams prepare a JSONL file containing individual API requests and submit the workload to the asynchronous service. The batch infrastructure processes the jobs independently, allowing applications to avoid maintaining thousands of concurrent synchronous connections.
The resulting workflow becomes:
Source URLs
→ Fetch and Clean HTML
→ Generate JSONL Requests
→ Submit Batch
→ Asynchronous Schematron Processing
→ Webhook or Status Monitoring
→ Retrieve Results
→ Validate
→ Load Into Data Platform
| Batch Characteristic | Current Capability |
|---|---|
| Maximum requests | 1,000,000 |
| Request representation | JSONL |
| Immediate connection required | No |
| Webhook support | Yes |
| Primary purpose | High-volume asynchronous inference |
| Schematron compatibility | Supported through platform Batch API |
Current documentation comparing the Group and Batch APIs lists expected completion windows of approximately 1 to 72 hours rather than the previously stated 24-hour-to-seven-day range.
Schematron V2 as an Extraction Microservice
The architectural advantage of Schematron V2 becomes clearer when it is treated as a dedicated extraction microservice rather than a general AI assistant.
| Component | Responsibility |
|---|---|
| Crawler | Find and retrieve pages |
| Browser renderer | Execute JavaScript when necessary |
| HTML cleaner | Minimize irrelevant markup |
| Schematron V2 | Convert page evidence into structured data |
| Validator | Detect invalid or unacceptable records |
| Database | Persist normalized information |
| Search or vector system | Make information retrievable |
| General-purpose LLM | Perform reasoning or synthesis when required |
This modular design allows each technology to perform the task for which it is best suited.
Schematron does not need to browse the internet, operate a browser, reason about business strategy or write reports. Its role is narrower: transform web documents into predictable structured information.
Why the Zero-Prompt Design Matters
The significance of Schematron V2’s architecture is not simply that developers write fewer prompts. The larger advantage is that the extraction contract becomes explicit and machine-readable.
Schemas can be version-controlled, automatically tested, shared across services and validated before data reaches production systems.
| Prompt-Centric Extraction | Schema-Centric Extraction |
|---|---|
| Instructions exist as prose | Requirements exist as types |
| Interpretation can vary | Structure is explicitly defined |
| Prompt changes can be difficult to validate | Schema changes can be versioned |
| Formatting errors require cleanup | Structured output is enforced |
| Harder to integrate with typed applications | Naturally integrates with typed applications |
| General-purpose interaction model | Extraction-specific interaction model |
Schematron V2 therefore represents more than a smaller model optimized for HTML parsing. Its architecture changes the developer interface for AI-based extraction: the schema effectively becomes the program.
For large-scale web intelligence, e-commerce aggregation, price monitoring, recruitment data, real estate datasets, financial research, RAG ingestion and AI-agent infrastructure, this schema-driven model can make extraction pipelines simpler, more deterministic and considerably easier to integrate with conventional data engineering systems.
3. Model Evolution: Schematron V1 to Schematron V2
Schematron has evolved from an experimental family of compact, open-weight HTML extraction models into a more production-oriented generation of specialized models optimized for quality, throughput and large-scale structured web-data processing.
Inference.net introduced the original Schematron family in September 2025 with Schematron 3B and Schematron 8B. The central premise was straightforward: HTML-to-JSON extraction does not necessarily require the enormous parameter counts and broad capabilities of frontier general-purpose language models. A smaller model trained specifically for web extraction could potentially deliver comparable extraction performance with substantially lower inference costs and latency.
Schematron V2, released in April 2026, advances this strategy with two specialized successors: Schematron V2 Small and Schematron V2 Turbo. Rather than differentiating models primarily by parameter scale, V2 separates them according to production workload requirements: extraction quality versus maximum throughput.
Schematron V1: Establishing the Specialized Extraction Model
The first Schematron generation launched on September 9, 2025 as Schematron 3B and Schematron 8B.
Both models were purpose-built to transform noisy HTML into structured JSON according to developer-defined schemas. The original models supported context windows of up to 128K tokens and were designed to handle malformed HTML, complicated schemas and substantial web documents.
Inference.net reported that the original models could deliver frontier-level extraction quality at approximately 1% to 2% of the cost of large general-purpose LLMs while providing more than 10 times faster inference under its tested workloads.
| Model | Generation | Context Window | Original Positioning | Current Role |
|---|---|---|---|---|
| Schematron 3B | V1 | Up to 128K tokens | Cost-efficient default extractor | Legacy and self-hosted model |
| Schematron 8B | V1 | Up to 128K tokens | Higher-quality difficult extraction | Legacy and self-hosted model |
| Schematron V2 Small | V2 | Up to 128K tokens | Quality-focused production extraction | Successor to Schematron 8B API workloads |
| Schematron V2 Turbo | V2 | Up to 128K tokens | High-throughput extraction | Successor to Schematron 3B API workloads |
How Schematron V1 Was Trained
The original Schematron project used large-scale web data to create a specialized HTML extraction training environment.
Inference.net reports that approximately one million pages were collected from Common Crawl. The company then generated diverse schemas and extraction examples rather than relying exclusively on manually labeled datasets.
The training methodology included document clustering, synthetic schema generation and frontier-model-assisted creation of extraction examples. The training process was also designed to expose Schematron to realistic variations in webpage structures and extraction requirements.
| V1 Training Component | Purpose |
|---|---|
| Common Crawl web documents | Supply realistic HTML structures |
| Approximately one million pages | Establish large-scale training corpus |
| Document clustering | Increase structural diversity |
| Synthetic schemas | Generate varied extraction requirements |
| Frontier-model distillation | Produce high-quality extraction targets |
| Long-context training | Prepare models for large HTML documents |
| Schema-conditioned extraction | Teach direct HTML-to-JSON transformation |
This training approach was important because web extraction presents a fundamentally different optimization target from ordinary conversational AI.
Schematron needed to learn where information exists within noisy documents, how fields correspond to schema definitions and how to produce consistently structured outputs without adding conversational commentary.
Schematron 3B vs Schematron 8B
The first generation offered a relatively conventional model-size trade-off.
Schematron 3B was positioned as the recommended default because it delivered strong extraction quality with significantly better economics. Schematron 8B provided a smaller additional quality improvement for harder and longer pages but required approximately twice the cost.
| V1 Characteristic | Schematron 3B | Schematron 8B |
|---|---|---|
| Model class | Smaller specialized model | Larger specialized model |
| Context window | Up to 128K | Up to 128K |
| Primary objective | Cost efficiency | Maximum V1 extraction quality |
| Difficult-page performance | Strong | Stronger |
| Relative cost | Lower | Approximately 2x 3B |
| Original recommendation | Default model | Difficult extraction workloads |
Published first-generation benchmarking reported an LLM-as-judge extraction score of 4.41 for Schematron 3B and 4.64 for Schematron 8B, compared with 4.74 for GPT-4.1 in that particular evaluation.
The benchmark demonstrated the core argument behind Schematron: relatively small task-specific models could approach the extraction quality of substantially larger general-purpose systems when evaluated on the specialized task for which they were trained.
Open-Weight Schematron
Another significant characteristic of V1 was the availability of its model weights.
The original Schematron 3B and 8B weights remain publicly available for self-hosting. Schematron 3B carries the Llama 3.2 license metadata and can be deployed through common inference frameworks.
This gives organizations several deployment possibilities.
| Deployment Approach | V1 Suitability | Main Advantage |
|---|---|---|
| Managed API | Legacy | Minimal infrastructure management |
| Local development | Strong | Developer experimentation |
| Private GPU infrastructure | Strong | Greater infrastructure control |
| Self-hosted production | Strong | Data and deployment control |
| Offline environments | Possible | No external inference dependency |
The continued availability of V1 weights means the first generation remains relevant for organizations prioritizing self-hosting even after the managed endpoints transition toward V2.
Schematron V2: From Model Size to Workload Optimization
Inference.net released Schematron V2 on April 16, 2026.
The second generation changes the product segmentation. Instead of simply presenting a smaller and larger model, V2 introduces variants optimized around different operational objectives.
Schematron V2 Small focuses on extraction quality.
Schematron V2 Turbo focuses on throughput.
| Design Philosophy | V1 | V2 |
|---|---|---|
| Main differentiation | Parameter scale | Workload characteristics |
| Cost-oriented model | Schematron 3B | Schematron V2 Turbo |
| Quality-oriented model | Schematron 8B | Schematron V2 Small |
| Long context | Up to 128K | Up to 128K |
| Structured extraction | Yes | Yes |
| Primary workload | HTML-to-JSON | HTML-to-JSON |
| Production emphasis | Model-size selection | Quality-throughput selection |
Schematron V2 Small
Schematron V2 Small is positioned as the quality-focused successor within the managed Schematron lineup.
Inference.net states that Small nearly matches the quality of the original Schematron 8B while maintaining performance closer to a 3B-class model.
This changes the economics of the previous generation. Under V1, organizations requiring the highest Schematron extraction quality generally needed the larger 8B model. V2 Small aims to provide approximately that quality tier without requiring the same inference footprint.
Typical workloads include complex nested schemas, difficult webpages, long HTML documents and extraction tasks where maximizing field accuracy matters more than absolute throughput.
Schematron V2 Turbo
Schematron V2 Turbo targets the opposite side of the production spectrum.
It is optimized for maximum throughput while still improving extraction quality relative to the previous-generation Schematron 3B.
Inference.net reports throughput of 4.14 requests per second on a single H100 for Turbo. Importantly, the company’s V2 announcement describes this as approximately 2.5 times the throughput of the original Schematron 3B, rather than 2.5 times the original 8B.
| Performance Dimension | V2 Small | V2 Turbo |
|---|---|---|
| Optimization target | Extraction quality | Maximum throughput |
| Single-H100 throughput | 2.47 requests/sec | 4.14 requests/sec |
| Extraction quality score | 4.060 | 4.039 |
| SimpleQA score | 83.10 | 79.42 |
| Recommended workload | Complex extraction | High-volume extraction |
| Typical priority | Accuracy | Speed and economics |
The very small difference between the published extraction-quality scores illustrates the attraction of Turbo for industrial workloads. Businesses processing millions of relatively predictable pages may gain significantly more from increased throughput than from a marginal improvement in extraction quality.
V1 to V2 Performance Evolution
The most meaningful evolution is therefore not simply that V2 is newer. Inference.net has changed the performance frontier of its specialized extraction architecture.
| Engineering Dimension | Schematron V1 | Schematron V2 |
|---|---|---|
| Entry model | Schematron 3B | V2 Turbo |
| Quality model | Schematron 8B | V2 Small |
| Maximum context | 128K | 128K |
| Primary optimization | Model size | Workload characteristics |
| High-throughput option | V1 3B | V2 Turbo |
| High-quality option | V1 8B | V2 Small |
| Schema-first extraction | Supported | Supported |
| Strict structured output | Supported | Supported |
| Managed API direction | Legacy | Current generation |
V2 Migration and Legacy Endpoint Routing
The transition from V1 to V2 has also been designed to minimize production disruption.
Inference.net scheduled the original managed Schematron 3B and Schematron 8B endpoints for deprecation in April 2026. However, applications using the old identifiers were not simply allowed to fail.
Legacy requests are transparently mapped to their corresponding V2 successors.
| Legacy Model Request | V2 Successor | Migration Logic |
|---|---|---|
| Schematron 3B | Schematron V2 Turbo | Throughput-oriented successor |
| Schematron 8B | Schematron V2 Small | Quality-oriented successor |
Inference.net nevertheless recommends explicitly updating model identifiers. Doing so ensures that developers understand which model, pricing structure and performance characteristics their application is actually using.
Open Weights vs Managed V2 Deployment
One of the more important distinctions between generations concerns deployment strategy.
The original Schematron weights remain available for organizations that want to self-host them. The current V2 product direction emphasizes Inference.net’s managed inference infrastructure.
| Deployment Requirement | V1 Models | V2 Models |
|---|---|---|
| Managed inference | Legacy | Primary deployment path |
| Public model weights | Available | Not positioned as the primary V2 distribution model |
| Self-hosting | Supported through V1 weights | Managed V2 preferred |
| Private GPU deployment | Possible with V1 | Depends on deployment arrangement |
| Serverless production | Legacy endpoints transitioning | Primary V2 use case |
Consequently, V1 has not become technically irrelevant. It can remain useful where model ownership, offline inference, local execution or infrastructure control outweigh the performance improvements available from managed V2 endpoints.
Which Schematron Generation Should Developers Use?
For new API-based production workloads, Schematron V2 represents the logical default because the original managed V1 endpoints have transitioned to their V2 successors.
The decision between Small and Turbo should then be based on workload characteristics rather than simply choosing the larger model.
| Requirement | Recommended Option |
|---|---|
| Highest V2 extraction quality | Schematron V2 Small |
| High-volume web extraction | Schematron V2 Turbo |
| Maximum throughput | Schematron V2 Turbo |
| Complex nested schemas | Schematron V2 Small |
| Difficult long webpages | Schematron V2 Small |
| Large product catalogs | Schematron V2 Turbo |
| Price-monitoring pipelines | Schematron V2 Turbo |
| Local self-hosting | Schematron V1 open weights |
| Offline deployment | Schematron V1 open weights |
| Existing Schematron 3B API workload | Migrate explicitly to V2 Turbo |
| Existing Schematron 8B API workload | Migrate explicitly to V2 Small |
What the Schematron Evolution Represents
The progression from Schematron V1 to Schematron V2 illustrates an important development in specialized language models.
V1 demonstrated that relatively compact models trained specifically for HTML-to-JSON extraction could compete surprisingly closely with much larger general-purpose models while dramatically improving inference economics.
V2 develops that concept further by optimizing models around production requirements rather than merely parameter counts. Small targets difficult, quality-sensitive extraction, while Turbo targets large-scale workloads where latency, throughput and cost become critical engineering constraints.
The result is a clearer specialization hierarchy: V1 remains valuable as an open-weight, self-hostable foundation, while Schematron V2 represents Inference.net’s current production-oriented evolution for scalable schema-driven web extraction.
4. Empirical Benchmarks, Latency, and Accuracy Metrics
Inference.net evaluates Schematron V2 across three complementary dimensions: extraction quality, hardware throughput, and downstream factual accuracy. These benchmarks are important because a production-grade HTML extraction model must do more than generate valid JSON. It must correctly identify the requested information, process large quantities of HTML economically, and preserve enough factual evidence to improve downstream AI applications.
For Schematron V2, Inference.net used GPT-5.4 as an LLM judge to grade extraction results on a scale from 1 to 5. The company also measured throughput on a single NVIDIA H100 GPU using a standardized workload containing approximately 10,000 input tokens and 500 output tokens per request.
Schematron V2 Extraction Quality Benchmark
The LLM-as-a-judge benchmark measures the quality of extracted information rather than simply checking whether the resulting JSON is syntactically valid.
Schematron V2 Small achieved a score of 4.060, only 0.010 points behind the first-generation Schematron 8B model at 4.070. V2 Turbo achieved 4.039 while substantially increasing processing throughput.
| Model | LLM-as-a-Judge Score | H100 Throughput | SimpleQA Score |
|---|---|---|---|
| Schematron 8B V1 | 4.070 | 1.63 req/sec | 85.58 |
| Schematron V2 Small | 4.060 | 2.47 req/sec | 83.10 |
| Schematron V2 Turbo | 4.039 | 4.14 req/sec | 79.42 |
| Schematron 3B V1 | 3.909 | 2.47 req/sec | 75.47 |
| GPT-5 Nano without search | Not directly comparable | Not reported | 8.54 |
The benchmark illustrates an important engineering characteristic of V2: model size alone is no longer the principal determinant of extraction performance.
V2 Small nearly reproduces the quality of the previous 8B model while operating at substantially higher throughput. Turbo gives up only 0.021 points relative to Small on the five-point extraction benchmark while increasing throughput from 2.47 to 4.14 requests per second.
Quality Improvements Across Schematron Generations
Comparing the generations reveals how Inference.net has improved the quality-to-compute relationship.
| Comparison | Quality Difference | Throughput Difference | Practical Meaning |
|---|---|---|---|
| V2 Small vs V1 8B | -0.010 | +51.5% | Nearly identical quality at much higher throughput |
| V2 Turbo vs V1 8B | -0.031 | +154.0% | Small quality trade-off for approximately 2.54x throughput |
| V2 Small vs V1 3B | +0.151 | Same published throughput | Higher extraction quality without sacrificing throughput |
| V2 Turbo vs V1 3B | +0.130 | +67.6% | Higher quality and significantly higher throughput |
These calculations are derived from Inference.net’s published benchmark figures.
The particularly important comparison is V2 Small against V1 3B. Both are reported at 2.47 requests per second under the benchmark configuration, yet V2 Small raises the quality score from 3.909 to 4.060.
Turbo moves the performance frontier further toward scale by reaching 4.14 requests per second.
Hardware Throughput
Inference.net’s throughput benchmark uses a single NVIDIA H100 with a workload consisting of 10,000 input tokens and 500 output tokens per request.
This workload is more representative of HTML extraction than conventional short-prompt LLM benchmarks because web pages typically contain substantially more input data than the JSON records produced from them.
| Model | Requests per Second | Approx. Requests per Minute | Approx. Requests per Hour |
|---|---|---|---|
| Schematron 8B V1 | 1.63 | 98 | 5,868 |
| Schematron 3B V1 | 2.47 | 148 | 8,892 |
| Schematron V2 Small | 2.47 | 148 | 8,892 |
| Schematron V2 Turbo | 4.14 | 248 | 14,904 |
The hourly figures are theoretical calculations based directly on published requests-per-second throughput and assume continuous saturation without pipeline overhead.
Actual production throughput will depend on batching, networking, request scheduling, document lengths, output sizes and infrastructure utilization.
V2 Turbo’s Throughput Advantage
Schematron V2 Turbo demonstrates the clearest performance improvement.
At 4.14 requests per second compared with 1.63 for V1 8B, Turbo provides approximately 2.54 times the throughput under the published benchmark configuration. Inference.net describes this as roughly a 2.5x improvement.
| Workload | V1 8B Theoretical Time | V2 Turbo Theoretical Time |
|---|---|---|
| 1,000 pages | ~10.2 minutes | ~4.0 minutes |
| 10,000 pages | ~102 minutes | ~40 minutes |
| 100,000 pages | ~17.0 hours | ~6.7 hours |
| 1,000,000 pages | ~7.1 days | ~2.8 days |
These values are simple capacity estimates from the published single-H100 throughput figures rather than measured end-to-end processing times.
At production scale, however, the difference becomes significant. A seemingly small improvement in requests per second compounds dramatically when a system continuously processes millions of pages.
Throughput Is Not the Same as End-to-End Latency
Throughput and latency should not be treated as interchangeable metrics.
A throughput result of 4.14 requests per second does not mean every Turbo request necessarily completes in 0.24 seconds. Multiple requests can be processed concurrently, and production latency also includes network communication, scheduling, HTML preprocessing and other infrastructure overhead.
| Metric | What It Measures |
|---|---|
| Requests per second | Aggregate processing capacity |
| Model latency | Time required for individual inference |
| Time to first token | Delay before generation begins |
| End-to-end latency | Complete application request time |
| Batch completion time | Time required for an asynchronous workload |
Therefore, the published 4.14 requests-per-second H100 benchmark provides strong evidence of Turbo’s throughput advantage, but claims about a universal 0.54-second page latency should not be inferred directly from that figure unless separately measured under the same deployment conditions.
Why V2 Small Prioritizes Accuracy
Schematron V2 Small is optimized differently.
Its 2.47 requests-per-second throughput is considerably below Turbo’s 4.14, but its extraction-quality score increases from 4.039 to 4.060 and its SimpleQA result rises from 79.42 to 83.10.
| Requirement | V2 Small | V2 Turbo |
|---|---|---|
| Maximum extraction quality | Preferred | Strong |
| Maximum throughput | Moderate | Preferred |
| Complex nested schemas | Preferred | Capable |
| Long difficult pages | Preferred | Capable |
| High-volume catalog extraction | Strong | Preferred |
| Cost-sensitive scraping | Strong | Preferred |
| Second-pass validation | Preferred | Less necessary |
| Real-time monitoring | Strong | Preferred |
This distinction makes the two models complementary rather than strictly competitive.
SimpleQA and Downstream Factual Accuracy
Inference.net also evaluates Schematron as part of a retrieval-augmented factual question-answering pipeline using SimpleQA.
This benchmark measures a different property from HTML extraction quality. Instead of asking whether a JSON object accurately represents a page, SimpleQA evaluates whether structured web extraction helps another model answer factual questions correctly.
Inference.net’s evaluation used GPT-5 Nano as the downstream base model with Exa providing web search for the Schematron-assisted configurations.
| Retrieval Configuration | SimpleQA Score |
|---|---|
| Schematron 8B V1 | 85.58 |
| Schematron V2 Small | 83.10 |
| Schematron V2 Turbo | 79.42 |
| Schematron 3B V1 | 75.47 |
| GPT-5 Nano without search | 8.54 |
The comparison should be interpreted carefully.
The 8.54 score represents GPT-5 Nano without web search, whereas the Schematron configurations incorporate web retrieval and structured extraction. Consequently, the difference cannot be attributed solely to Schematron. It demonstrates the effectiveness of the complete search-plus-extraction pipeline compared with an ungrounded model baseline.
Why Structured Extraction Can Improve RAG Accuracy
Traditional retrieval pipelines can pass large quantities of raw webpage content directly into a reasoning model.
This approach can create several problems: irrelevant navigation content consumes context, scripts and markup add noise, multiple webpages compete for attention, and important facts can become buried inside extremely long inputs.
Schematron introduces a compression and normalization layer between retrieval and reasoning.
| Raw Retrieval Pipeline | Schematron-Assisted Pipeline |
|---|---|
| Search web | Search web |
| Retrieve pages | Retrieve pages |
| Collect raw HTML | Collect raw HTML |
| Send large documents downstream | Extract requested attributes |
| Reason across noisy context | Produce compact structured JSON |
| Generate answer | Reason over normalized evidence |
| Higher downstream token consumption | Lower downstream context requirements |
The objective is not conventional text summarization. Schematron transforms relevant evidence into explicitly typed fields that downstream systems can consume more predictably.
Extraction Quality vs Schema Compliance
Another important distinction is between structural correctness and factual correctness.
Inference.net reports that Schematron operates in strict JSON mode with 100% schema adherence. That means outputs conform structurally to the requested schema. It does not mean every extracted value is guaranteed to be factually correct.
| Evaluation Dimension | Question Being Tested |
|---|---|
| JSON validity | Is the response valid JSON? |
| Schema adherence | Does it match the required structure? |
| Field extraction accuracy | Were the correct values extracted? |
| Semantic interpretation | Did the model understand what each field means? |
| Factuality | Are the resulting facts correct? |
| Throughput | How many requests can the system process? |
| Cost efficiency | What does extraction cost at production scale? |
This distinction is particularly important for financial, legal, commercial or other high-value datasets where structurally valid but incorrect information could still create downstream problems.
Benchmark Interpretation
Schematron V2’s published benchmark results demonstrate a strong quality-throughput trade-off, but they should be interpreted as vendor benchmarks rather than universal performance guarantees.
Real-world results can vary substantially according to page complexity, schema quality, document length, malformed markup, ambiguity, preprocessing and the amount of relevant evidence contained within the page.
| Benchmark Finding | Practical Interpretation |
|---|---|
| V2 Small scores 4.060 | Highest published V2 extraction quality |
| V2 Turbo scores 4.039 | Very small quality reduction |
| Small reaches 2.47 req/sec | Balanced quality and throughput |
| Turbo reaches 4.14 req/sec | Optimized for large-scale extraction |
| V1 8B scores 4.070 | Still marginally ahead on quality benchmark |
| Small SimpleQA reaches 83.10 | Strong performance in tested retrieval pipeline |
| 100% schema adherence | Reliable output structure, not guaranteed factual perfection |
What the Benchmarks Mean for Production Deployment
The benchmark results suggest that Schematron V2 Small and Turbo serve two distinct production strategies.
Small is the stronger choice when extraction errors are expensive, schemas contain complicated nested relationships, webpages are unusually difficult, or downstream systems require the highest available V2 extraction quality.
Turbo becomes more attractive when organizations process hundreds of thousands or millions of pages and throughput, latency and unit economics dominate the decision.
A particularly effective architecture can combine both.
| Processing Tier | Model | Purpose |
|---|---|---|
| Primary extraction | V2 Turbo | Process the majority of pages cheaply and quickly |
| Validation | Business rules | Detect incomplete or suspicious records |
| Reprocessing | V2 Small | Re-extract difficult cases |
| Escalation | General-purpose LLM | Handle cases requiring deeper reasoning |
| Human review | Analyst | Resolve high-value ambiguous records |
This tiered approach exploits Turbo’s throughput while reserving Small’s additional extraction quality for the minority of documents that actually require it.
Overall, Inference.net’s published benchmarks show that Schematron V2’s principal advantage is not simply raw accuracy or raw speed in isolation. It is the combination of near-V1-8B extraction quality, substantially higher throughput, strict structured output and strong performance when used as an extraction layer inside retrieval systems. For large-scale HTML-to-JSON workloads, those characteristics can materially change the economics of turning the open web into structured, machine-readable data.
5. Economic Models, Token Pricing, and Operational Cost Infrastructure
The economics of large-scale web extraction are fundamentally different from those of ordinary conversational AI. Extraction workloads are heavily input-weighted: a webpage can contain thousands or tens of thousands of HTML tokens while the resulting structured JSON may contain only a few hundred.
Consequently, input-token pricing, HTML preprocessing, page volume and schema size become the dominant variables when estimating the operating cost of an AI-powered extraction pipeline. Inference.net explicitly identifies input tokens as the main cost driver for Schematron workloads because HTML pages are generally much larger than their extracted outputs.
Web Extraction Cost Formula
The basic cost model can be expressed as:
Daily Cost = Number of Pages × ((Average Input Tokens ÷ 1,000,000 × Input Price) + (Average Output Tokens ÷ 1,000,000 × Output Price))
This formula makes Schematron’s economics relatively straightforward to forecast.
| Variable | Meaning | Primary Cost Driver |
|---|---|---|
| Number of pages | Documents processed per day | Workload scale |
| Input tokens | Cleaned HTML tokens per page | Usually largest contributor |
| Output tokens | Extracted JSON tokens | Usually secondary |
| Input price | Cost per million input tokens | Critical at web scale |
| Output price | Cost per million output tokens | Important for large schemas |
| Page preprocessing | Amount of HTML removed before inference | Can reduce input spending |
| Schema complexity | Number and depth of requested fields | Influences output volume |
Current Schematron V2 Pricing
Current Inference.net pricing places Schematron V2 Small at $0.05 per million input tokens and $0.25 per million output tokens. Schematron V2 Turbo costs $0.03 per million input tokens and $0.15 per million output tokens.
| Model | Input Cost per 1M Tokens | Output Cost per 1M Tokens | Primary Economic Role |
|---|---|---|---|
| Schematron V2 Small | $0.05 | $0.25 | Quality-sensitive extraction |
| Schematron V2 Turbo | $0.03 | $0.15 | High-volume extraction |
Turbo is therefore approximately 40% cheaper than Small for both input and output tokens.
This difference becomes increasingly significant as page volumes move from thousands to millions or billions.
Why Input Tokens Dominate Extraction Costs
Consider a cleaned product page containing 10,000 input tokens that produces 500 output tokens.
Using V2 Turbo:
Input cost per page = 10,000 ÷ 1,000,000 × $0.03 = $0.00030
Output cost per page = 500 ÷ 1,000,000 × $0.15 = $0.000075
Total extraction cost = $0.000375 per page
Inference.net independently presents the same worked figure: approximately $37.50 per 100,000 pages for Turbo under a 10,000-input-token and 500-output-token workload. Small costs approximately $62.50 for the same workload.
| Scale | V2 Turbo | V2 Small |
|---|---|---|
| 1 page | $0.000375 | $0.000625 |
| 1,000 pages | $0.375 | $0.625 |
| 100,000 pages | $37.50 | $62.50 |
| 1 million pages | $375 | $625 |
| 30 million pages | $11,250 | $18,750 |
These are calculated extraction costs rather than guaranteed invoices. Actual expenditure depends on the token profile of the pages being processed.
Cost for Smaller E-Commerce Pages
Product pages do not necessarily require 10,000 input tokens after cleaning.
For a catalog workload averaging 3,000 input tokens and 200 output tokens, Schematron V2 Turbo costs:
Input = 3,000 ÷ 1,000,000 × $0.03 = $0.00009
Output = 200 ÷ 1,000,000 × $0.15 = $0.00003
Total = $0.00012 per page
That translates to approximately:
| Catalog Volume | Estimated V2 Turbo Extraction Cost |
|---|---|
| 1,000 pages | $0.12 |
| 10,000 pages | $1.20 |
| 100,000 pages | $12.00 |
| 1 million pages | $120.00 |
| 10 million pages | $1,200.00 |
This supports Inference.net’s broader observation that extracting 1,000 cleaned product pages can cost only tens of cents when page sizes remain relatively small.
Schematron V2 Small vs Turbo Economics
The decision between Small and Turbo should not be based solely on token price.
Small offers slightly higher published extraction quality, while Turbo combines lower token pricing with substantially higher throughput.
| Economic Factor | V2 Small | V2 Turbo |
|---|---|---|
| Input price | $0.05/M | $0.03/M |
| Output price | $0.25/M | $0.15/M |
| H100 throughput | 2.47 req/sec | 4.14 req/sec |
| Extraction quality score | 4.060 | 4.039 |
| Cost priority | Secondary | Primary |
| Throughput priority | Moderate | High |
| Complex schemas | Preferred | Capable |
| Large recurring crawls | Strong | Preferred |
Turbo therefore provides both approximately 40% lower token pricing and roughly 68% higher published H100 throughput than Small, while giving up only 0.021 points on Inference.net’s five-point extraction-quality benchmark.
Comparing Schematron with General-Purpose Models
The original cost comparison needs updating because current API pricing differs substantially from some historical figures.
For example, GPT-5 is currently listed at $1.25 per million input tokens, $0.125 per million cached input tokens and $10 per million output tokens. It should therefore not be modeled using the approximately $15 input and $60 output figures in the original calculation.
Gemini 2.5 Flash currently lists paid text input at $0.30 per million tokens, output at $2.50 per million tokens and context caching at $0.03 per million text tokens.
| Model | Input per 1M Tokens | Cached Input | Output per 1M Tokens |
|---|---|---|---|
| GPT-5 | $1.25 | $0.125 | $10.00 |
| Gemini 2.5 Flash | $0.30 | $0.03 | $2.50 |
| Schematron V2 Small | $0.05 | Not required for comparison | $0.25 |
| Schematron V2 Turbo | $0.03 | Not required for comparison | $0.15 |
These models are not functionally equivalent. GPT-5 and Gemini are general-purpose systems with substantially broader capabilities, whereas Schematron is optimized specifically for structured extraction.
The comparison therefore illustrates extraction economics rather than overall model value.
One Million Pages per Day
Consider one million pages containing 10,000 input tokens and producing 500 output tokens each.
| Model | Approx. Daily Token Cost | Approx. Annual Cost |
|---|---|---|
| GPT-5 | $17,500 | $6.39 million |
| Gemini 2.5 Flash | $4,250 | $1.55 million |
| Schematron V2 Small | $625 | $228,125 |
| Schematron V2 Turbo | $375 | $136,875 |
These calculations use current published standard token prices and exclude caching, batch discounts, retrieval, crawling, proxies, networking and infrastructure charges.
Under this particular workload, moving from GPT-5 to Schematron V2 Turbo reduces the extraction-model token bill by approximately 97.9%.
That percentage should not be generalized to every workload because page size, output size, caching and model selection materially affect the result.
Cost Per 1,000 Pages
For engineering teams evaluating extraction providers, cost per 1,000 pages is often more intuitive than token pricing.
| Page Profile | V2 Small | V2 Turbo |
|---|---|---|
| 3K input + 200 output | $0.20 | $0.12 |
| 5K input + 500 output | $0.375 | $0.225 |
| 10K input + 500 output | $0.625 | $0.375 |
| 10K input + 1K output | $0.75 | $0.45 |
| 10K input + 2K output | $1.00 | $0.60 |
Inference.net publishes corresponding worked examples for several of these token profiles.
The Hidden Economics of HTML Cleaning
Token optimization begins before Schematron receives the document.
Raw HTML frequently contains scripts, CSS, tracking code, navigation, repeated templates and other information that does not contribute to the requested extraction.
Removing unnecessary markup therefore provides a direct economic benefit.
| Optimization | Token Effect | Economic Effect |
|---|---|---|
| Remove scripts | Lower input volume | Lower inference cost |
| Remove styles | Lower input volume | Lower inference cost |
| Target relevant DOM region | Potentially major reduction | Lower cost and less noise |
| Minimize requested fields | Smaller output | Lower output cost |
| Use concise field structures | Smaller JSON payload | Lower output cost |
| Route easy pages to Turbo | Lower model cost | Higher overall efficiency |
| Escalate failures to Small | Limits expensive processing | Preserves quality |
For large extraction systems, preprocessing can therefore function as a financial optimization layer rather than merely a technical cleanup step.
Extraction Cost Is Only Part of Total Cost
A low Schematron inference bill does not mean that collecting one million webpages costs only a few hundred dollars.
Web acquisition can involve HTTP infrastructure, residential or datacenter proxies, CAPTCHA handling, JavaScript rendering, browser instances, retries, storage and bandwidth.
Inference.net itself emphasizes the distinction between fetching and extraction, noting that fetching can become more expensive than the model-based extraction layer.
| Cost Layer | Typical Expense |
|---|---|
| URL discovery | Search, feeds or crawling |
| Proxy infrastructure | IP rotation and geographic access |
| Browser rendering | JavaScript-heavy websites |
| HTML storage | Raw-page archival |
| Preprocessing | Compute for cleaning documents |
| Schematron inference | Structured extraction |
| Validation | Quality-control processing |
| Database | Structured record storage |
| Downstream AI | Analysis, RAG or generation |
A realistic total-cost-of-ownership model should therefore separate acquisition cost from extraction cost.
Tiered Model Routing
One of the strongest economic architectures is to avoid processing every document with the highest-quality model.
Turbo can operate as the first-pass extraction engine, with Small reserved for records that fail deterministic validation.
| Pipeline Tier | Processing Engine | Economic Objective |
|---|---|---|
| Initial extraction | V2 Turbo | Lowest-cost high-volume processing |
| Schema validation | Deterministic code | Detect suspicious records cheaply |
| Difficult-page retry | V2 Small | Spend more only where necessary |
| Reasoning escalation | General-purpose LLM | Handle genuinely complex cases |
| Human review | Analyst | Resolve valuable exceptions |
Suppose 95% of pages can be processed successfully by Turbo and only 5% require Small. The organization avoids paying the higher Small rate across the entire dataset while retaining a higher-quality fallback mechanism.
Daily and Annual Budget Forecasting
Because Schematron follows linear token pricing, capacity planning can be modeled relatively easily.
For one million pages per day at 10,000 input and 500 output tokens:
| Cost Period | V2 Small | V2 Turbo |
|---|---|---|
| Daily | $625 | $375 |
| 30 days | $18,750 | $11,250 |
| 365 days | $228,125 | $136,875 |
For the smaller 3,000-input and 200-output catalog profile:
| Cost Period | V2 Small | V2 Turbo |
|---|---|---|
| Daily | $200 | $120 |
| 30 days | $6,000 | $3,600 |
| 365 days | $73,000 | $43,800 |
The enormous difference between these two scenarios illustrates why page preprocessing and actual token measurement matter more than headline cost-per-million-token figures.
Economic Role of Specialized Extraction Models
Schematron V2 demonstrates a broader economic principle emerging within AI infrastructure: organizations do not necessarily need frontier intelligence for every stage of an AI pipeline.
| Workload | Economically Appropriate Model Class |
|---|---|
| HTML field extraction | Specialized extraction model |
| Basic classification | Small specialized model |
| Complex document reasoning | General-purpose reasoning model |
| Strategic synthesis | Frontier LLM |
| Difficult extraction exception | V2 Small or general model |
| Millions of routine webpages | V2 Turbo |
A frontier model can remain extremely valuable at the reasoning layer while a much cheaper specialized model performs repetitive data transformation underneath it.
This creates a more efficient architecture:
Web Acquisition
→ HTML Cleaning
→ Schematron V2 Turbo
→ Validation
→ Schematron V2 Small for Exceptions
→ Structured Database
→ Frontier LLM for Reasoning
The expensive intelligence is therefore applied only after the raw web has been compressed into useful evidence.
Operational Cost Infrastructure
For organizations operating Schematron at very large scale, token pricing is only one dimension of infrastructure economics. Throughput, GPU utilization, asynchronous processing, failure rates, validation overhead and page acquisition costs must also be incorporated into the operating model.
| Infrastructure Metric | Financial Impact |
|---|---|
| Input tokens per page | Directly affects inference spending |
| Output tokens per page | Affects extraction cost |
| Requests per second | Determines infrastructure capacity |
| Extraction failure rate | Creates retry expenditure |
| Turbo-to-Small escalation rate | Determines blended model cost |
| Browser-rendering rate | Can materially increase fetching cost |
| Proxy cost | Can exceed extraction expense |
| Data retention | Adds storage expenditure |
| Downstream token reduction | Can offset extraction expenditure |
This broader perspective is important when assessing Schematron’s return on investment. The lowest extraction-token price does not automatically produce the lowest total cost of ownership.
Economic Significance of Schematron V2
Schematron V2’s strongest economic proposition emerges at scale.
At a few hundred pages, differences measured in fractions of a cent have little business significance. At hundreds of millions of pages, those fractions become substantial infrastructure expenses.
Current pricing of $0.03 per million input tokens and $0.15 per million output tokens makes V2 Turbo particularly suited to high-volume extraction, while Small’s $0.05 input and $0.25 output pricing provides a relatively inexpensive quality-oriented escalation path.
The larger architectural opportunity is therefore not simply replacing one API with a cheaper API. It is restructuring the web-data pipeline so that specialized models perform repetitive extraction, deterministic software handles validation, and expensive general-purpose models are reserved for tasks requiring genuine reasoning.
For enterprises operating product intelligence, competitive monitoring, financial research, recruitment aggregation, real estate analytics, AI agents or RAG systems across millions of webpages, that division of labor can substantially reduce the cost of converting the open web into usable structured data.
6. Industry Use Cases, Implementation Paradigms, and Community Feedback
Schematron V2 is designed for applications where organizations repeatedly need to transform heterogeneous HTML into predictable, typed data. Its most natural use cases therefore sit between web acquisition and downstream business systems: product catalogs, competitive intelligence, real estate datasets, financial research, AI retrieval pipelines and automated web-processing systems.
Inference.net positions Schematron V2 Small as the quality-oriented model for complex schemas and long pages, while V2 Turbo targets high-throughput, cost-sensitive extraction.
E-Commerce Product Data Extraction
E-commerce represents one of the strongest production use cases for Schematron V2.
Large marketplaces, price-comparison services and product intelligence platforms frequently ingest pages from hundreds or thousands of retailers. Each merchant may represent titles, prices, availability, variants and specifications differently.
Traditional scraping requires separate selectors or parsers for many of these templates. Schematron instead allows the extraction pipeline to define a common product schema and apply it across different HTML structures.
| Product Attribute | Recommended Schema Treatment | Business Purpose |
|---|---|---|
| Product name | Required string | Primary catalog identifier |
| SKU | Optional string | Merchant product matching |
| Brand | Optional string | Manufacturer normalization |
| Current price | Required number | Pricing intelligence |
| Currency | Optional or required string | Cross-market normalization |
| Availability | Typed field | Inventory monitoring |
| Specifications | Key-value object | Product comparison |
| Variants | Array | Size, color and configuration analysis |
| Tags | Array with empty default | Classification |
| Breadcrumbs | Array with empty default | Category reconstruction |
Inference.net specifically recommends distinguishing required and optional fields carefully. Critical fields can remain required, while information that legitimately may not exist on every page can use nullable types or empty defaults.
Why Unified Schemas Matter for Catalogs
The architectural advantage becomes clearer when the same extraction contract is reused across merchants.
| Selector-Based Catalog Pipeline | Schematron-Based Pipeline |
|---|---|
| Retailer A parser | Unified product schema |
| Retailer B parser | Unified product schema |
| Retailer C parser | Unified product schema |
| Custom fixes after redesign | Semantic extraction |
| Merchant-specific output cleanup | Standard typed output |
| Continuous selector maintenance | Schema and validation maintenance |
This does not eliminate all site-specific engineering. Fetching, JavaScript rendering, authentication and anti-bot systems remain separate problems.
What Schematron can reduce is the amount of site-specific parsing logic required after usable HTML has been obtained.
Price and Competitive Intelligence
Price-monitoring platforms face a similar problem at even greater frequency.
A competitor’s page may contain a list price, promotional price, installment price, member price and historical price simultaneously. Simply locating currency symbols is therefore insufficient.
Schema descriptions can explicitly define which value Schematron should extract.
| Pricing Field | Extraction Definition |
|---|---|
| active_price | Current price available to an ordinary buyer |
| list_price | Original non-discounted price |
| currency | Currency applying to active price |
| discount | Current advertised reduction |
| availability | Whether product can currently be purchased |
This is where Schematron’s schema-first architecture becomes particularly valuable: field descriptions carry semantic extraction requirements rather than relying entirely on DOM locations.
Real Estate Data Aggregation
Property websites provide another strong application.
Listings commonly contain current asking prices alongside previous prices, mortgage estimates, tax assessments, rental estimates and historical transaction values.
A property intelligence platform can define fields such as:
| Real Estate Field | Example Extraction Objective |
|---|---|
| Listing price | Current advertised asking price |
| Property type | Apartment, house, land or commercial |
| Bedrooms | Current listing bedroom count |
| Bathrooms | Current listing bathroom count |
| Floor area | Advertised usable or total area |
| Location | Address or geographic description |
| Amenities | Structured list of property features |
| Listing status | Active, pending, sold or unavailable |
| Agent | Listing representative |
| Historical prices | Separate array rather than current price |
Schematron V2 Small is particularly suited to difficult pages and long documents because Inference.net positions it as the highest-quality model in the V2 family for complex schemas and lengthy HTML.
Financial Data Extraction
Financial webpages can present an even harder extraction problem because relevant information frequently appears inside tables, filings, investor-relations pages and dense financial documents.
Schematron’s long-context capability allows it to process HTML inputs approaching 128K tokens, although Inference.net recommends trimming documents to the relevant region whenever practical.
| Financial Application | Potential Structured Output |
|---|---|
| Earnings pages | Revenue, profit, EPS, period |
| Investor relations | Report title, date, company, filing type |
| Financial tables | Period-value pairs |
| Company profiles | Industry, headquarters, executives |
| Market research | Market size, growth rates, periods |
| Regulatory pages | Filing metadata and disclosed fields |
For financially sensitive workflows, schema adherence alone should never be treated as proof that extracted values are correct. Deterministic validation and source-level verification remain important.
Recruitment and Job Intelligence
Recruitment platforms can use the same architecture to normalize job listings from different career sites.
| Job Data Field | Normalized Output |
|---|---|
| Job title | Standard string |
| Employer | Company identity |
| Location | Structured location |
| Employment type | Full-time, part-time or contract |
| Salary | Structured compensation |
| Requirements | Extracted requirement list |
| Skills | Structured skill array |
| Experience | Required experience |
| Application destination | Relevant application reference |
| Posting date | Normalized date |
Instead of maintaining extraction logic for every employer’s career-site template, a platform can maintain a standardized job schema and validate every extracted record before ingestion.
AI Agents and Browser Automation
Schematron can also function as a perception layer for web agents.
A browser agent frequently needs only a small subset of information from a webpage: available navigation targets, products, form information, search results or other state relevant to its next action.
A schema-guided extraction model can transform the HTML state into a smaller machine-readable representation before another model decides what to do.
| Agent Stage | Function |
|---|---|
| Browser | Loads and interacts with webpage |
| DOM acquisition | Captures current page state |
| HTML preprocessing | Removes irrelevant markup |
| Schematron | Extracts required state |
| Reasoning model | Determines next action |
| Browser controller | Executes action |
However, claims that Turbo universally processes every interactive DOM in approximately 0.54 seconds should be treated cautiously. Inference.net publishes throughput of 4.14 requests per second on a single H100 under its benchmark configuration, but aggregate throughput is not equivalent to guaranteed per-request end-to-end latency.
RAG and Web Research Pipelines
Schematron can also sit between web retrieval and a general-purpose reasoning model.
Rather than supplying complete HTML pages to the final model, a retrieval system can extract only the evidence relevant to the question.
Search
→ Retrieve HTML
→ Clean HTML
→ Schematron Extraction
→ Structured Evidence
→ Reasoning Model
→ Answer
| Direct Raw-Context RAG | Structured Extraction RAG |
|---|---|
| Large HTML context | Compact structured evidence |
| Navigation and markup included | Irrelevant markup removed |
| Facts buried in documents | Facts mapped to explicit fields |
| Higher downstream token consumption | Potentially lower token consumption |
| Reasoner also performs extraction | Extraction and reasoning separated |
This architecture illustrates a broader implementation paradigm: use specialized models for data transformation and reserve more expensive general-purpose models for actual reasoning.
Automated Data Pipelines
Inference.net describes production extraction as a multi-stage pipeline rather than a single model request. Crawling, cleaning, extraction, validation, retries and monitoring remain separate responsibilities.
| Pipeline Component | Recommended Responsibility |
|---|---|
| Crawler | Acquire pages |
| Browser | Render JavaScript where necessary |
| Cleaner | Remove irrelevant HTML |
| Schematron Turbo | Perform routine extraction |
| Validator | Detect missing or invalid records |
| Schematron Small | Retry difficult documents |
| Review queue | Handle unresolved exceptions |
| Database | Store normalized records |
| Monitoring | Detect extraction drift |
This approach is more robust than assuming an AI extractor eliminates the need for conventional data-engineering controls.
Validation-First Implementation
Inference.net recommends validating results on ingestion even though Schematron is designed to return schema-conforming JSON.
A production pipeline can consequently implement multiple validation levels.
| Validation Layer | Example |
|---|---|
| Type validation | Price must be numeric |
| Required-field validation | Product name cannot be absent |
| Range validation | Price cannot be negative |
| Semantic validation | Currency must correspond to supported market |
| Cross-field validation | Sale price should not contradict price fields |
| Historical validation | Detect implausible changes from previous record |
| Review threshold | Escalate suspicious records |
This separates structural conformity from business-level data quality.
Local and Self-Hosted Schematron
There is an important distinction between Schematron V2 and the original Schematron models when discussing local deployments.
The original Schematron 3B model remains available through Ollama and can run locally. Ollama lists the model at approximately 6.4 GB with a 128K context window.
| Deployment Requirement | Suitable Schematron Option |
|---|---|
| Current managed production API | V2 Small or Turbo |
| Lowest managed extraction cost | V2 Turbo |
| Maximum V2 quality | V2 Small |
| Local experimentation | V1 3B |
| Ollama deployment | V1 3B |
| Private offline processing | V1 open weights |
| Managed web-scale workload | V2 models |
Therefore, reports of developers running Schematron locally on Apple Silicon generally refer to the open-weight first-generation model rather than the current managed V2 endpoints.
Actual local performance will depend on memory capacity, quantization, context length and hardware configuration.
HTML Email Extraction
Local Schematron also creates interesting possibilities outside conventional web scraping.
HTML emails, for example, share many characteristics with webpages: inconsistent markup, repeated boilerplate and semi-structured information embedded within presentation-oriented HTML.
A local extraction workflow could operate as:
Inbound HTML Email
→ HTML Cleaning
→ Local Schematron
→ Typed JSON
→ Validation
→ Webhook or Automation
Potential applications include order confirmations, shipping notices, invoices, lead notifications and other machine-generated emails.
This represents a plausible implementation pattern for the open-weight model rather than a V2-specific capability documented by Inference.net.
Selecting the Right Implementation Paradigm
There is no single optimal Schematron deployment architecture.
| Operational Requirement | Recommended Architecture |
|---|---|
| Small real-time application | Synchronous V2 API |
| High-volume catalog | V2 Turbo |
| Difficult structured documents | V2 Small |
| Mixed-complexity workload | Turbo with Small fallback |
| Massive offline processing | Batch extraction |
| Private local data | Self-hosted V1 |
| AI research agent | Retrieval + Schematron + reasoning model |
| Browser automation | Browser + extraction + agent |
| Enterprise intelligence | Crawler + Schematron + validation + warehouse |
Community Feedback and Claims
Public discussion around specialized extraction models generally centers on three advantages: lower cost, reduced latency and less maintenance compared with either frontier-model extraction or large collections of brittle selectors.
However, community anecdotes need to be separated from controlled Schematron V2 benchmarks.
The strongest verifiable evidence currently comes from Inference.net’s own documentation and published benchmarks, which report 4.14 requests per second for Turbo, 2.47 requests per second for Small, strict schema adherence and substantially lower token prices than many general-purpose models.
Claims attributed to individual companies or developers should be treated as testimonials rather than independent benchmark evidence unless the underlying methodology, workloads and before-and-after measurements are publicly available.
Likewise, statements that Schematron universally reduces a $20,000 scraping workload to below $500 should be treated as illustrative cost scenarios rather than guaranteed outcomes. Actual savings depend heavily on page size, preprocessing, output size, crawling infrastructure and the alternative model being replaced.
What Developers Appear to Value Most
The most important practical benefit is arguably not simply lower token pricing.
It is the ability to replace large amounts of website-specific extraction logic with a stable data contract.
| Developer Concern | Schematron Approach |
|---|---|
| Changing CSS classes | Semantic schema-based extraction |
| Different merchant templates | Common output schema |
| JSON formatting failures | Strict structured output |
| Long HTML pages | Long-context processing |
| High inference bills | Specialized low-cost models |
| Difficult pages | Small quality tier |
| Massive page volumes | Turbo throughput tier |
| Sensitive local workloads | V1 self-hosting option |
| Production data quality | Typed validation layer |
Industry Adoption Pattern
Schematron V2 is therefore best understood as infrastructure rather than an end-user AI application.
It occupies a narrowly defined but economically important layer between unstructured web content and structured software systems.
| Industry | Input | Schematron Output | Downstream Application |
|---|---|---|---|
| E-commerce | Product pages | Product records | Catalog intelligence |
| Retail | Competitor pages | Prices and availability | Pricing systems |
| Real estate | Property listings | Property records | Market analytics |
| Recruitment | Job pages | Structured vacancies | Job databases |
| Finance | Tables and reports | Financial records | Research platforms |
| Market intelligence | Company pages | Company attributes | Business databases |
| AI search | Retrieved webpages | Structured evidence | RAG |
| AI agents | Current DOM state | Machine-readable state | Agent reasoning |
| Email automation | HTML emails | Event records | Workflow automation |
The broader implementation lesson is that Schematron should not be expected to replace crawlers, browsers, validators, databases or reasoning models. Its value comes from specializing in the transformation step between them.
For organizations processing large volumes of heterogeneous HTML, this specialization can simplify extraction architecture considerably: one stable schema can replace substantial amounts of site-specific parsing logic, Turbo can handle inexpensive high-volume processing, Small can address harder documents, and deterministic validators can prevent questionable records from reaching production systems.
7. Technical Boundaries, Operational Guidelines, and Future Outlook
Schematron V2 is a highly specialized HTML-to-JSON extraction system rather than a universal web-scraping or document-processing platform. Understanding this boundary is important because many production failures occur when an extraction model is assigned responsibilities that belong elsewhere in the data pipeline.
Inference.net explicitly separates webpage acquisition from information extraction. Schematron expects HTML to have already been obtained by a crawler, HTTP client, browser automation system or another upstream service. Its responsibility begins when that HTML needs to be converted into structured, schema-conforming information.
Where Schematron V2 Fits
A production web-data architecture should treat Schematron as one specialized component within a larger pipeline.
| Pipeline Requirement | Appropriate Technology | Schematron V2 Role |
|---|---|---|
| URL discovery | Crawler or search system | Not responsible |
| HTTP fetching | HTTP client or crawler | Not responsible |
| Proxy rotation | Proxy infrastructure | Not responsible |
| JavaScript rendering | Headless browser | Not responsible |
| Browser interaction | Automation framework | Not responsible |
| HTML cleaning | Parser or preprocessing library | Recommended upstream |
| Semantic field extraction | Schematron V2 | Core responsibility |
| JSON schema conformity | Schematron V2 | Core responsibility |
| Business-rule validation | Application code | Recommended downstream |
| Database ingestion | ETL or application layer | Downstream responsibility |
Inference.net specifically describes Schematron as the extraction layer rather than a crawler, proxy network or browser-automation tool.
When Schematron V2 Should Not Be Used
The presence of HTML does not automatically justify using an AI extraction model.
Conventional software remains more efficient when the underlying data can already be accessed deterministically.
| Data Situation | Preferred Approach | Reason |
|---|---|---|
| Public REST API available | Direct API integration | Data is already structured |
| Embedded JSON data available | Standard JSON parser | No semantic extraction needed |
| Reliable JSON-LD available | Structured-data parser | Faster and deterministic |
| Stable single-page template | CSS or XPath selectors | Lower computational overhead |
| Highly variable HTML | Schematron V2 | Semantic extraction adds value |
| Thousands of different layouts | Schematron V2 | Reduces selector maintenance |
| Scanned document images | OCR or vision pipeline | HTML extractor cannot read image pixels |
| Interactive JavaScript application | Browser renderer first | DOM must exist before extraction |
This illustrates an important engineering principle: AI extraction should solve ambiguity and structural variability rather than replace inexpensive deterministic parsing unnecessarily.
Static Selectors vs Schematron V2
CSS selectors and XPath remain excellent tools.
If an organization controls a website whose DOM structure changes infrequently, a selector-based parser may remain cheaper and faster indefinitely.
Schematron becomes more compelling as structural variability increases.
| Environment | Static Parser | Schematron V2 |
|---|---|---|
| One stable template | Excellent | Usually unnecessary |
| Ten similar templates | Strong | Potentially useful |
| Hundreds of changing sites | Maintenance-heavy | Strong |
| Unknown external websites | Fragile | Strong |
| Semantically ambiguous fields | Limited | Strong |
| Extremely high deterministic volume | Excellent | Depends on complexity |
| Frequent redesigns | High maintenance | More resilient |
The correct architecture can therefore combine deterministic and AI extraction rather than choosing one universally.
Schema Design as the Primary Control Surface
Because Schematron does not accept conventional extraction instructions, schema quality has an unusually large influence on extraction quality.
Inference.net explicitly advises developers to provide clear schemas with appropriate field types and descriptions. Ambiguous fields requiring interpretation or synthesis should be described carefully because those descriptions communicate what the extractor is expected to identify.
Provide Explicit Field Descriptions
A weak field definition might simply request:
price
A stronger definition communicates semantic intent:
current_price — The primary price currently payable by an ordinary customer, excluding the struck-through original price.
This distinction matters on pages containing several candidate values.
| Ambiguous Field | Better Semantic Definition |
|---|---|
| price | Current active purchase price |
| original_price | Non-discounted or struck-through list price |
| company | Legal or prominently identified company name |
| location | Location applying specifically to this listing |
| date | Publication date rather than modification date |
| availability | Current purchasing availability |
| revenue | Revenue for the explicitly requested reporting period |
Inference.net’s own price-extraction examples use schema descriptions to distinguish active prices from other pricing information on the page.
Design Nullability Around Reality
Not every webpage contains every desired attribute.
Schemas should therefore distinguish genuinely mandatory information from fields that may legitimately be absent.
| Field Situation | Recommended Schema Design |
|---|---|
| Always present | Required |
| Sometimes unavailable | Nullable |
| Optional collection | Empty-array default |
| Optional properties map | Empty-object default |
| Unknown scalar value | Null |
| Business-critical missing value | Validation failure |
For example, product name and primary price might be mandatory for a pricing database, whereas tags, breadcrumbs and secondary specifications could default to empty collections.
Inference.net’s product extraction guidance emphasizes designing required and optional fields carefully instead of requiring information that may not exist on every source page.
Preprocess HTML Before Extraction
HTML preprocessing is one of Inference.net’s strongest operational recommendations.
Schematron was trained using HTML cleaned with lxml-based processing that removes scripts, JavaScript, styles and inline styling. Matching production preprocessing to that training environment can improve consistency while simultaneously reducing unnecessary token consumption.
| HTML Element | Typical Action | Reason |
|---|---|---|
| Main content | Preserve | Contains evidence |
| Headings | Preserve | Provides semantic hierarchy |
| Tables | Preserve | Often contains target facts |
| Lists | Preserve | Frequently contains attributes |
| Scripts | Remove | Usually extraction noise |
| JavaScript | Remove | Consumes unnecessary tokens |
| CSS styles | Remove | Visual presentation rarely required |
| Inline styles | Remove | Reduces context |
| Boilerplate | Remove cautiously | Reduces irrelevant context |
Inference.net also cautions developers to err on the side of removing less content rather than aggressively cleaning away evidence that Schematron may need.
Validate After Extraction
Strict schema adherence should not be confused with guaranteed factual correctness.
Schematron is designed to return valid JSON conforming to the requested structure, but Inference.net still recommends validating records during ingestion. Pydantic, Zod or equivalent application-level validators can detect unacceptable values and trigger retries or review workflows.
| Validation Level | Example |
|---|---|
| Type validation | Price must be numeric |
| Presence validation | Product name must exist |
| Range validation | Price cannot be negative |
| Format validation | Currency follows expected format |
| Cross-field validation | Sale price should correspond with pricing fields |
| Historical validation | Detect implausible changes |
| Source validation | Preserve evidence for important extracted facts |
For sensitive financial extraction, retaining source evidence alongside extracted values can be especially useful. Inference.net’s financial extraction examples include source text with individual financial metrics.
Handle Long Documents Deliberately
Schematron V2 supports context windows of up to 128K tokens.
Documents exceeding that limit need to be truncated, divided into logical sections or processed through multiple extraction calls. Even documents below the maximum can benefit from narrowing the HTML to the relevant content region.
| Document Size | Recommended Strategy |
|---|---|
| Small page | Process directly |
| Medium page with noise | Clean before extraction |
| Large page under 128K | Clean and process |
| Very large structured page | Extract relevant DOM region |
| Page above 128K | Chunk or truncate |
| Multi-document dataset | Process independently or asynchronously |
Production Routing Strategy
Organizations do not necessarily need to choose permanently between Small and Turbo.
A tiered architecture can use Turbo as the inexpensive default and escalate uncertain records to Small.
| Processing Stage | Recommended Engine | Purpose |
|---|---|---|
| Primary extraction | V2 Turbo | Maximum throughput |
| Basic validation | Deterministic code | Detect obvious failures |
| Difficult retry | V2 Small | Improve extraction quality |
| Business validation | Application logic | Enforce domain rules |
| Exceptional ambiguity | General-purpose LLM or review | Resolve unusual cases |
This architecture takes advantage of Turbo’s speed while limiting higher-quality processing to records where it actually adds value.
Monitoring Extraction Drift
AI extraction reduces dependence on fragile selectors, but it does not eliminate the need for monitoring.
Websites change their content, terminology, layouts and business logic. A technically valid extraction may consequently become semantically incorrect without generating an obvious software error.
| Monitoring Signal | Potential Problem |
|---|---|
| Sudden null-field increase | Page redesign or missing evidence |
| Price distribution shift | Incorrect field interpretation |
| Record-count decline | Fetching or extraction failure |
| Validation-error increase | Schema-source mismatch |
| Output-size change | New page structure |
| Retry-rate increase | Extraction difficulty increasing |
| Source-content change | Website redesign |
Production systems should therefore monitor data distributions and business-level quality in addition to HTTP success rates.
Schematron V2 Operational Checklist
| Operational Practice | Recommendation |
|---|---|
| Separate crawling from extraction | Strongly recommended |
| Clean HTML before inference | Recommended |
| Use explicit schema descriptions | Strongly recommended |
| Keep temperature at zero | Recommended by Inference.net |
| Make optional fields nullable | Recommended |
| Validate extracted records | Recommended |
| Monitor extraction drift | Recommended |
| Use Turbo for high-volume workloads | Appropriate |
| Use Small for complex extraction | Appropriate |
| Chunk documents beyond 128K | Required |
| Use deterministic parsing when sufficient | More economical |
Current Technical Limitations
Schematron V2’s specialization creates both its advantages and its boundaries.
| Limitation | Practical Consequence |
|---|---|
| Maximum 128K context | Extremely large pages require segmentation |
| HTML-oriented extraction | Image-only documents need another system |
| No extraction prompts | Requirements must be encoded in schema |
| Does not fetch webpages | Separate crawler required |
| Does not render JavaScript | Browser infrastructure may be required |
| Schema compliance is structural | Factual validation remains necessary |
| Closed V2 weights | V2 Small and Turbo currently use managed API access |
Inference.net confirms that V2 Small and Turbo remain closed-source for now, while the original Schematron 3B and 8B weights remain available for self-hosting.
Future Outlook: Schematron Pro
The most significant announced addition to the Schematron family is Schematron Pro.
Inference.net states that Schematron Pro is under development and is intended to achieve extraction accuracy exceeding the original Schematron 8B while retaining similar request throughput. It is being positioned as a premium model for workloads where maximum extraction quality matters more than minimizing inference cost.
| Schematron Tier | Primary Optimization | Intended Workload |
|---|---|---|
| V2 Turbo | Throughput and cost | Internet-scale routine extraction |
| V2 Small | Quality and complexity | Difficult schemas and long pages |
| Schematron Pro | Maximum accuracy | High-value enterprise extraction |
Importantly, Schematron Pro should currently be regarded as an announced future model rather than a generally available production offering.
Potential Role of Schematron Pro
If Schematron Pro achieves its stated objective, it could create a three-tier extraction architecture.
Routine pages could flow through Turbo, difficult records could move to Small, and exceptionally important or ambiguous documents could escalate to Pro.
| Extraction Difficulty | Potential Model |
|---|---|
| Routine | V2 Turbo |
| Moderate | V2 Turbo |
| Difficult | V2 Small |
| Highly complex | V2 Small |
| Accuracy-critical | Schematron Pro |
| Requires genuine reasoning | General-purpose reasoning model |
Such routing could allow organizations to optimize cost and accuracy dynamically rather than processing every page with the most expensive available model.
The Broader Future of Specialized Extraction Models
Schematron V2 illustrates a broader shift in AI infrastructure from one-model-for-everything architectures toward specialized model pipelines.
General-purpose frontier models remain valuable when applications require reasoning, synthesis, planning or complex interpretation. But repetitive transformation tasks such as HTML extraction can often be assigned to smaller models optimized specifically for that operation.
| Pipeline Function | Appropriate AI or Software Layer |
|---|---|
| Web acquisition | Traditional software |
| Browser rendering | Browser automation |
| HTML preprocessing | Deterministic parser |
| Routine extraction | Schematron V2 Turbo |
| Difficult extraction | Schematron V2 Small |
| Maximum-quality extraction | Schematron Pro, if released as planned |
| Validation | Deterministic application logic |
| Complex reasoning | General-purpose LLM |
| Final analytics | Database, BI or AI system |
This separation can produce AI systems that are cheaper, faster and easier to control because expensive general-purpose intelligence is reserved for stages that genuinely require it.
Final Operational Perspective
Schematron V2 should ultimately be viewed as a specialized extraction engine rather than a replacement for the entire web-data stack.
Its strongest use case appears where conventional selectors become difficult to maintain because organizations must process large numbers of heterogeneous or frequently changing webpages. Conversely, APIs, JSON-LD, stable templates and deterministic data sources should continue to be handled with conventional software whenever practical.
The recommended production strategy is therefore hybrid: fetch and render with dedicated infrastructure, remove unnecessary HTML upstream, describe extraction requirements precisely through schemas, process routine pages with Turbo, escalate difficult documents to Small, validate everything downstream and continuously monitor extraction quality.
Schematron Pro could extend that architecture with a premium accuracy tier. Until it becomes generally available and independently measurable, however, its performance targets should be treated as Inference.net’s development objectives rather than established production benchmarks.
Conclusion
Inference.net Schematron V2 represents a specialized approach to one of the most resource-intensive challenges in modern data engineering: converting large volumes of inconsistent HTML into reliable, structured JSON. Instead of relying on expensive general-purpose language models or maintaining fragile website-specific selectors, Schematron V2 uses schema-driven extraction to identify and organize information according to predefined data structures.
With Schematron V2 Small focused on complex, accuracy-sensitive extraction and Schematron V2 Turbo optimized for high-throughput workloads, organizations can select a model according to their balance of quality, speed, and operating cost. Its support for long HTML documents, structured outputs, typed schemas, and large-scale asynchronous processing makes Schematron V2 particularly relevant for e-commerce catalog extraction, price monitoring, real estate intelligence, financial data processing, recruitment aggregation, AI agents, and retrieval-augmented generation pipelines.
However, Schematron V2 is best understood as an extraction layer rather than a complete web scraping platform. Crawling, JavaScript rendering, proxy management, HTML preprocessing, validation, and downstream storage remain separate responsibilities. APIs, JSON-LD, and predictable static webpages should also continue to use deterministic parsing when that approach is simpler and more economical.
Ultimately, the significance of Inference.net Schematron V2 extends beyond HTML-to-JSON conversion. It demonstrates how smaller, task-specific AI models can replace expensive general-purpose inference for narrowly defined production workloads. For businesses processing hundreds of thousands or millions of webpages, combining Schematron V2 Turbo for routine extraction, V2 Small for difficult documents, and deterministic validation for quality control can create a scalable and cost-efficient web data architecture.
As specialized AI infrastructure continues to mature, Schematron V2 provides a practical example of how organizations can move away from using frontier models for every task and instead build modular AI pipelines in which each model is optimized for a specific role. For large-scale structured web data extraction, this combination of specialization, schema-driven control, throughput, and low operating costs makes Schematron V2 a notable technology to watch in 2026.
If you find this article useful, why not share it with your hiring manager and C-level suite friends and also leave a nice comment below?
We, at the 9cv9 Research Team, strive to bring the latest and most meaningful data, guides, and statistics to your doorstep.
To get access to top-quality guides, click over to 9cv9 Blog.
To hire top talents using our modern AI-powered recruitment agency, find out more at 9cv9 Modern AI-Powered Recruitment Agency.
People Also Ask
What is Inference.net Schematron V2?
Inference.net Schematron V2 is a specialized AI model family designed to convert unstructured and complex HTML into structured JSON according to predefined schemas.
How does Schematron V2 work?
Schematron V2 analyzes supplied HTML and maps relevant information to fields defined within a JSON Schema, Pydantic model, or similar structured data specification.
What is Schematron V2 used for?
Schematron V2 is used for product extraction, price monitoring, real estate data, financial research, job aggregation, competitive intelligence, RAG pipelines, and AI agents.
What is the difference between Schematron V2 Small and Turbo?
Schematron V2 Small prioritizes extraction quality for difficult documents, while Schematron V2 Turbo prioritizes throughput, lower costs, and large-scale processing.
What is Schematron V2 Small?
Schematron V2 Small is the quality-focused Schematron model designed for complex schemas, difficult webpages, long documents, and extraction tasks requiring greater accuracy.
What is Schematron V2 Turbo?
Schematron V2 Turbo is the high-throughput Schematron model optimized for fast, economical HTML-to-JSON extraction across large numbers of webpages.
Is Schematron V2 an AI web scraping tool?
Schematron V2 performs the extraction stage of AI web scraping. It does not crawl websites, rotate proxies, solve anti-bot challenges, or render JavaScript by itself.
Can Schematron V2 convert HTML to JSON?
Yes. HTML-to-JSON conversion is Schematron V2’s primary purpose. Developers define the desired JSON structure, and the model extracts matching information from supplied HTML.
Does Schematron V2 require prompt engineering?
Schematron V2 uses a schema-first approach rather than conventional extraction prompts. Field names, types, descriptions, and schema structure communicate what data should be extracted.
What is schema-driven data extraction?
Schema-driven extraction defines the fields, types, and structures required before processing begins. Schematron uses this schema as the contract for transforming HTML into structured data.
Does Schematron V2 support JSON Schema?
Yes. Schematron supports structured extraction through schemas, allowing developers to define required fields, optional values, nested objects, arrays, and field descriptions.
Does Schematron V2 support Pydantic and Zod?
Yes. Schematron can work with typed schema frameworks such as Pydantic for Python and Zod for TypeScript through compatible structured-output workflows.
What context window does Schematron V2 support?
Schematron V2 supports context windows of up to 128K tokens, allowing it to process substantial HTML documents before exceptionally large pages require trimming or chunking.
How much does Schematron V2 cost?
Schematron V2 uses token-based pricing. Turbo is positioned as the lower-cost, high-throughput option, while Small costs more but prioritizes extraction quality for difficult workloads.
Is Schematron V2 cheaper than general-purpose LLMs?
For specialized HTML extraction, Schematron V2 can be substantially cheaper than many general-purpose frontier models because it is optimized specifically for structured web data extraction.
How fast is Schematron V2 Turbo?
Inference.net reports throughput of 4.14 requests per second on a single NVIDIA H100 for V2 Turbo under its standardized extraction benchmark.
How fast is Schematron V2 Small?
Inference.net reports throughput of 2.47 requests per second on a single NVIDIA H100 for V2 Small under its standardized HTML extraction benchmark.
Is Schematron V2 better than CSS selectors?
It depends on the workload. CSS selectors can be cheaper for stable templates, while Schematron becomes valuable when extracting standardized information across many changing or heterogeneous websites.
Can Schematron V2 replace web crawlers?
No. Schematron V2 extracts structured information from HTML that has already been obtained. Crawlers, HTTP clients, or browser automation systems are still needed to retrieve webpages.
Can Schematron V2 scrape JavaScript websites?
Schematron does not execute JavaScript itself. Dynamic websites generally need to be rendered by a browser or another upstream service before the resulting HTML is submitted for extraction.
Can Schematron V2 extract e-commerce product data?
Yes. Schematron can extract product names, prices, brands, SKUs, availability, variants, specifications, categories, and other attributes into standardized product records.
Can Schematron V2 be used for price monitoring?
Yes. Businesses can define schemas for current prices, list prices, discounts, currencies, and availability to create structured competitor price-monitoring pipelines.
Can Schematron V2 extract real estate data?
Yes. Schematron can structure property prices, locations, bedrooms, bathrooms, floor areas, amenities, listing statuses, agents, and other information from property pages.
Can Schematron V2 extract financial data?
Schematron can structure financial information contained in HTML pages and tables. High-value financial datasets should still undergo deterministic validation and source verification.
Can Schematron V2 extract job listing data?
Yes. Recruitment platforms can use Schematron to extract job titles, employers, locations, salaries, requirements, skills, employment types, and other vacancy information.
Can Schematron V2 improve RAG pipelines?
Schematron can extract relevant facts from retrieved webpages into compact structured records before a reasoning model processes them, potentially reducing noisy context and downstream token usage.
Can AI agents use Schematron V2?
Yes. AI agents can use Schematron as a structured extraction layer for webpage information before a separate reasoning or planning model determines the next action.
Should HTML be cleaned before using Schematron V2?
Yes. Removing irrelevant scripts, styles, and other unnecessary markup can reduce token consumption and noise while preserving the content required for extraction.
What is the difference between Schematron V1 and V2?
V1 introduced open-weight 3B and 8B extraction models. V2 advances the architecture with Small for quality-sensitive extraction and Turbo for higher-throughput production workloads.
What is Schematron Pro?
Schematron Pro is an announced future model intended to provide a higher accuracy tier for demanding extraction workloads. Its final production performance should be evaluated once generally available.
Sources
Inference.net Reddit Hacker News Ollama OpenRouter Hugging Face Infron AI